



Stable Diffusion, developed by CompVis, Stability AI, and LAION, has generated a great deal of interest due to its ability to generate highly accurate images by simply entering text prompts. Stable Diffusion mainly uses the English subset LAION2B-en of the LAION-5B dataset for its training data and, as a result, requires English text prompts to be entered producing images that tend to be more oriented towards Western culture.
rinna Co., Ltd. has developed a Japanese-specific text-to-image model named “Japanese Stable Diffusion” by fine-tuning Stable Diffusion on Japanese-captioned images. Japanese Stable Diffusion accepts Japanese text prompts and generates images that reflect the culture of the Japanese-speaking world which may be difficult to express through translation.
In this blog, we will discuss the background of the development of Japanese Stable Diffusion and its learning methodology.
Japanese Stable Diffusion is available on Hugging Face and GitHub. The code is based on 🧨 Diffusers.
Stable Diffusion
Recently diffusion models have been reported to be very effective in artificial synthesis, even more so than GANs (Generative Adversarial Networks) for images. Hugging Face explains how diffusion models work in the following articles:
Generally, a text-to-image model consists of a text encoder that interprets text and a generative model that generates an image from its output.
Stable Diffusion uses CLIP, the language-image pre-training model from OpenAI, as its text encoder and a latent diffusion model, which is an improved version of the diffusion model, as the generative model. Stable Diffusion was trained mainly on the English subset of LAION-5B and can generate high-performance images simply by entering text prompts. In addition to its high performance, Stable Diffusion is also easy to use with inference running at a computing cost of about 10GB VRAM GPU.
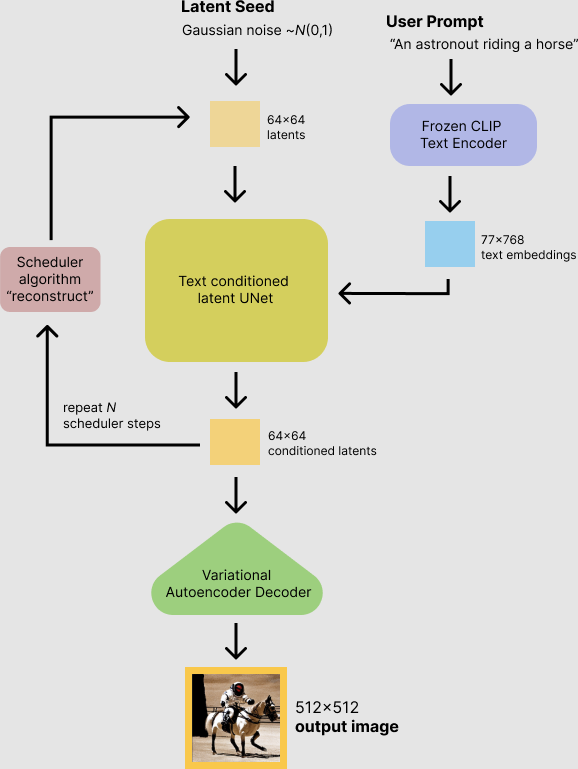
from Stable Diffusion with 🧨 Diffusers
Japanese Stable Diffusion
Why do we need Japanese Stable Diffusion?
Stable Diffusion is a very powerful text-to-image model not only in terms of quality but also in terms of computational cost. Because Stable Diffusion was trained on an English dataset, it is required to translate non-English prompts to English first. Surprisingly, Stable Diffusion can sometimes generate proper images even when using non-English prompts.
So, why do we need a language-specific Stable Diffusion? The answer is because we want a text-to-image model that can understand Japanese culture, identity, and unique expressions including slang. For example, one of the more common Japanese terms re-interpreted from the English word businessman is “salary man” which we most often imagine as a man wearing a suit. Stable Diffusion cannot understand such Japanese unique words correctly because Japanese is not their target.
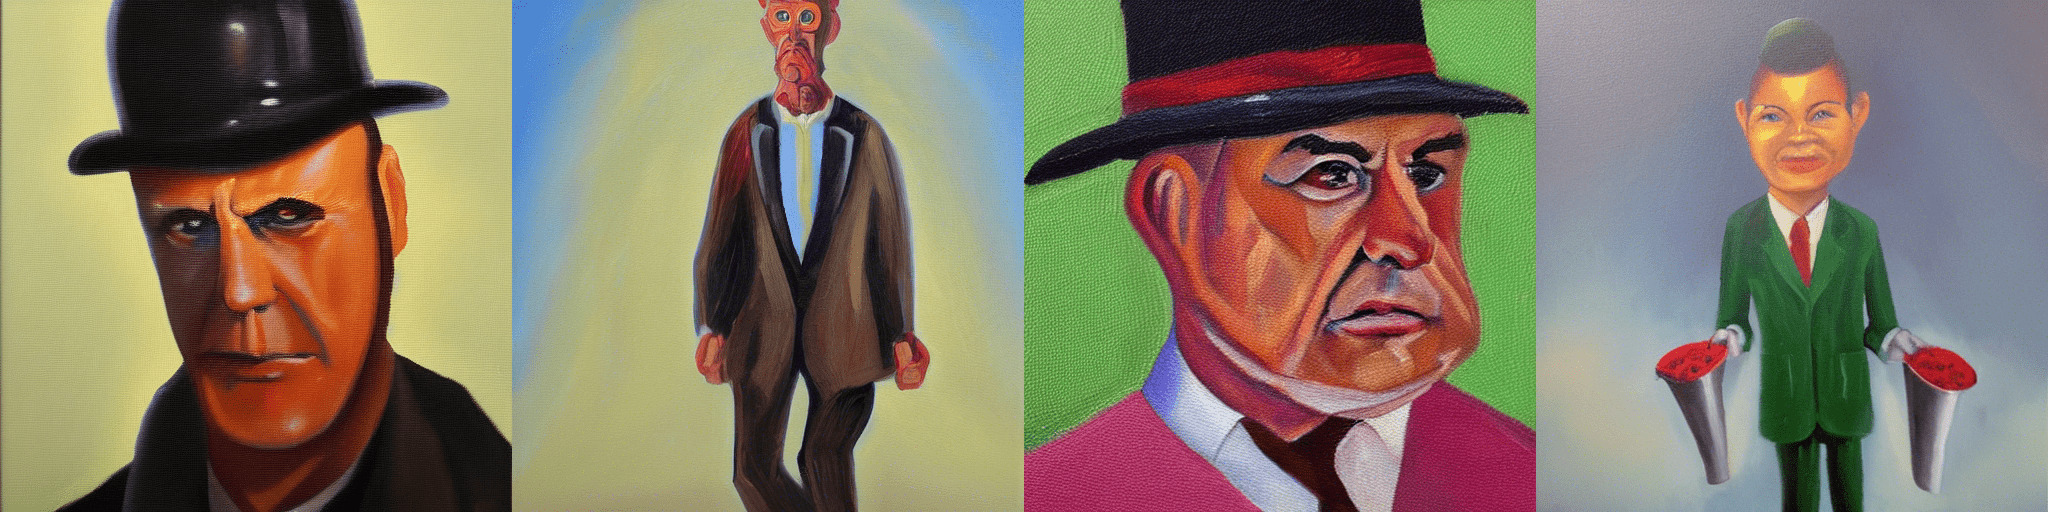
“salary man, oil painting” from the original Stable Diffusion
So, this is why we made a language-specific version of Stable Diffusion. Japanese Stable Diffusion can achieve the following points compared to the original Stable Diffusion.
- Generate Japanese-style images
- Understand Japanese words adapted from English
- Understand Japanese unique onomatope
- Understand Japanese proper noun
Training Data
We used approximately 100 million images with Japanese captions, including the Japanese subset of LAION-5B. In addition, to remove low quality samples, we used japanese-cloob-vit-b-16 published by rinna Co., Ltd. as a preprocessing step to remove samples whose scores were lower than a certain threshold.
Training Details
The biggest challenge in making a Japanese-specific text-to-image model is the size of the dataset. Non-English datasets are much smaller than English datasets, and this causes performance degradation in deep learning-based models. The dataset used to train Japanese Stable Diffusion is 1/20th the size of the dataset on which Stable Diffusion is trained. To make a good model with such a small dataset, we fine-tuned the powerful Stable Diffusion trained on the English dataset, rather than training a text-to-image model from scratch.
To make a good language-specific text-to-image model, we did not simply fine-tune but applied 2 training stages following the idea of PITI.
1st stage: Train a Japanese-specific text encoder
In the 1st stage, the latent diffusion model is fixed and we replaced the English text encoder with a Japanese-specific text encoder, which is trained. At this time, our Japanese sentencepiece tokenizer is used as the tokenizer. If the CLIP tokenizer is used as it is, Japanese texts are tokenized bytes, which makes it difficult to learn the token dependency, and the number of tokens becomes unnecessarily large. For example, if we tokenize “サラリーマン 油絵”, we get ['ãĤ', 'µ', 'ãĥ©', 'ãĥª', 'ãĥ¼ãĥ', 'ŀ', 'ãĥ³', 'æ', '²', '¹', 'çµ', 'µ'] which are uninterpretable tokens.
from transformers import CLIPTokenizer
tokenizer = CLIPTokenizer.from_pretrained("openai/clip-vit-large-patch14")
text = "サラリーマン 油絵"
tokens = tokenizer(text, add_special_tokens=False)['input_ids']
print("tokens:", tokenizer.convert_ids_to_tokens(tokens))

print("decoded text:", tokenizer.decode(tokens))
On the other hand, by using our Japanese tokenizer, the prompt is split into interpretable tokens and the number of tokens is reduced. For example, “サラリーマン 油絵” can be tokenized as ['▁', 'サラリーマン', '▁', '油', '絵'], which is correctly tokenized in Japanese.
from transformers import T5Tokenizer
tokenizer = T5Tokenizer.from_pretrained("rinna/japanese-stable-diffusion", subfolder="tokenizer", use_auth_token=True)
tokenizer.do_lower_case = True
tokens = tokenizer(text, add_special_tokens=False)['input_ids']
print("tokens:", tokenizer.convert_ids_to_tokens(tokens))

print("decoded text:", tokenizer.decode(tokens))
This stage enables the model to understand Japanese prompts but does not still output Japanese-style images because the latent diffusion model has not been changed at all. In other words, the Japanese word “salary man” can be interpreted as the English word “businessman,” but the generated result is a businessman with a Western face, as shown below.
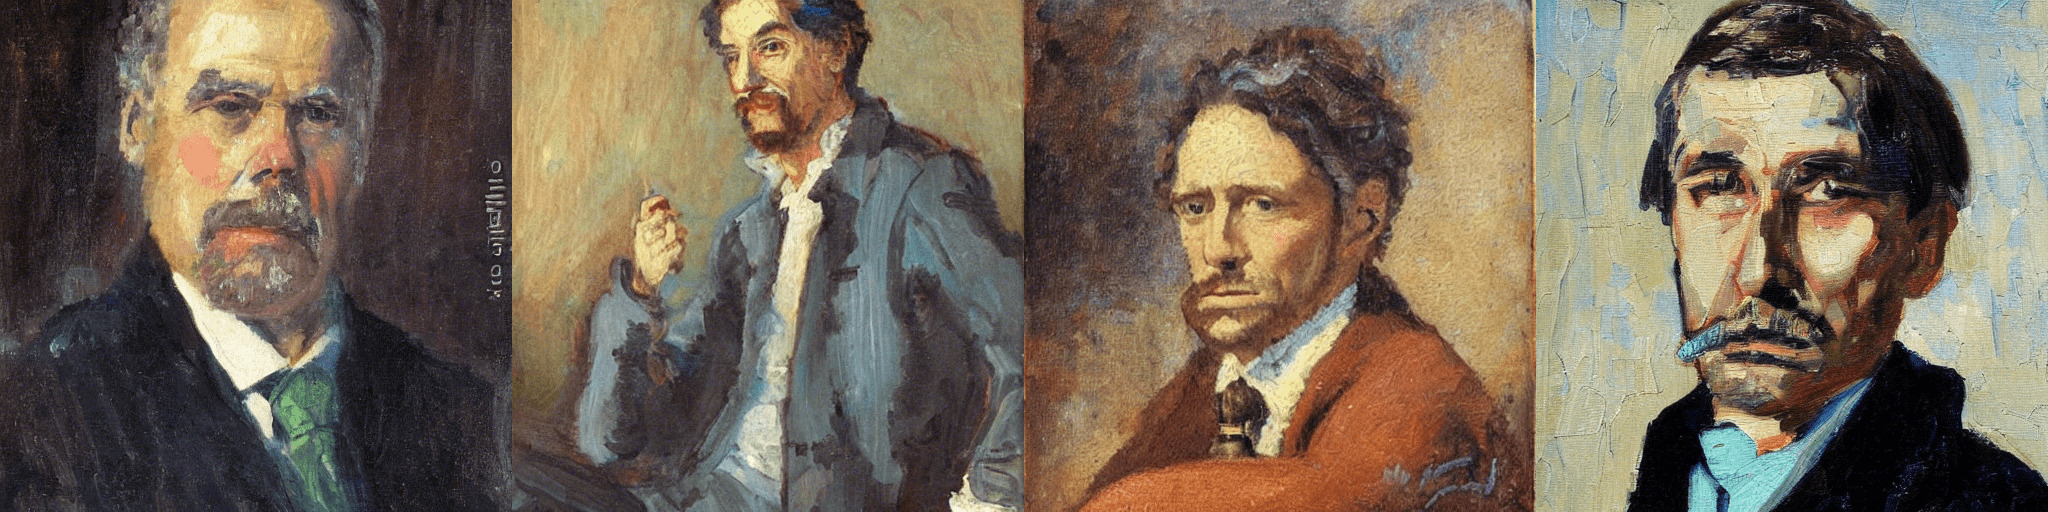
“サラリーマン 油絵”, which means exactly “salary man, oil painting”, from the 1st-stage Japanese Stable Diffusion
Therefore, in the 2nd stage, we train to output more Japanese-style images.
2nd stage: Fine-tune the text encoder and the latent diffusion model jointly
In the 2nd stage, we will train both the text encoder and the latent diffusion model to generate Japanese-style images. This stage is essential to make the model become a more language-specific model. After this, the model can finally generate a businessman with a Japanese face, as shown in the image below.
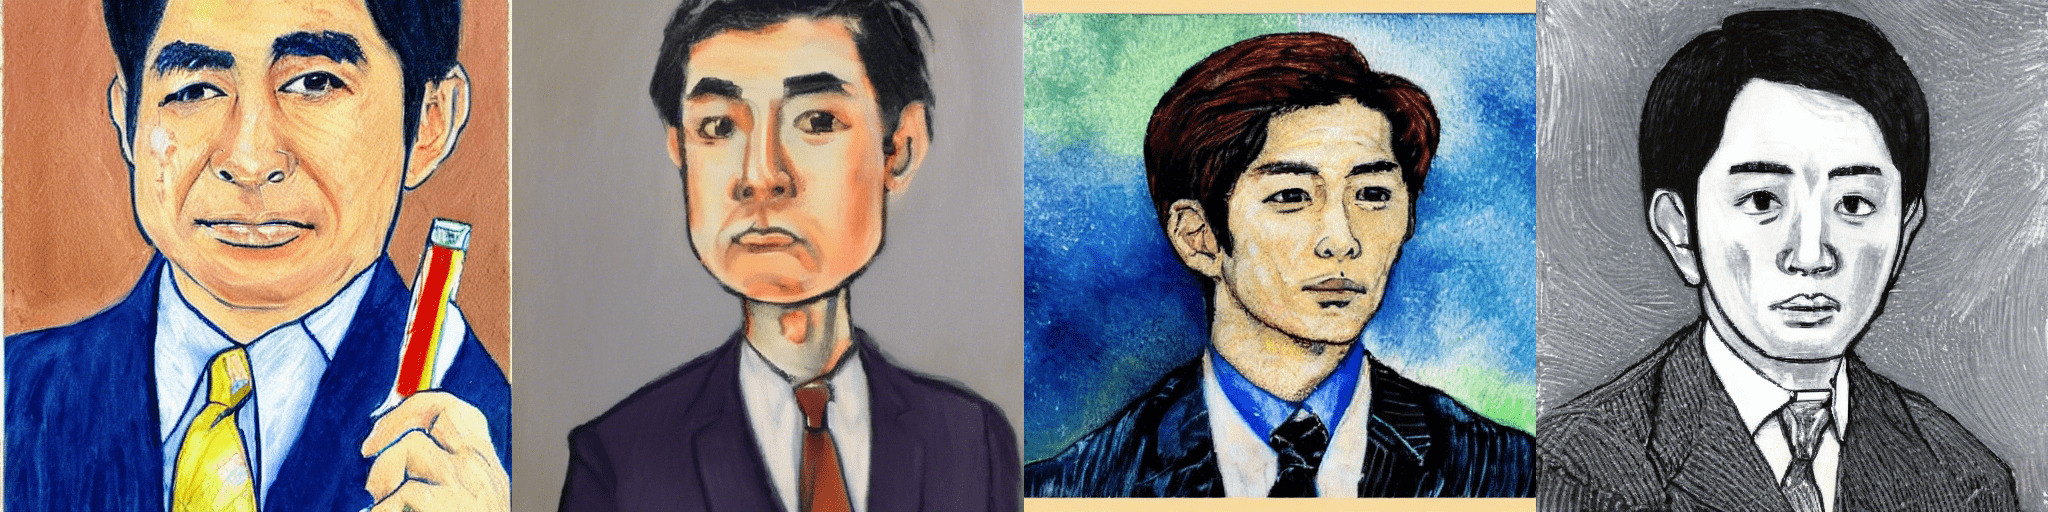
“サラリーマン 油絵”, which means exactly “salary man, oil painting”, from the 2nd-stage Japanese Stable Diffusion
rinna’s Open Strategy
Numerous research institutes are releasing their research results based on the idea of democratization of AI, aiming for a world where anyone can easily use AI. In particular, recently, pre-trained models with a large number of parameters based on large-scale training data have become the mainstream, and there are concerns about a monopoly of high-performance AI by research institutes with computational resources. Still, fortunately, many pre-trained models have been released and are contributing to the development of AI technology. However, pre-trained models on text often target English, the world’s most popular language. For a world in which anyone can easily use AI, we believe that it is desirable to be able to use state-of-the-art AI in languages other than English.
Therefore, rinna Co., Ltd. has released GPT, BERT, and CLIP, which are specialized for Japanese, and now have also released Japanese Stable Diffusion. By releasing a pre-trained model specialized for Japanese, we hope to make AI that is not biased toward the cultures of the English-speaking world but also incorporates the culture of the Japanese-speaking world. Making it available to everyone will help to democratize an AI that guarantees Japanese cultural identity.
What’s Next?
Compared to Stable Diffusion, Japanese Stable Diffusion is not as versatile and still has some accuracy issues. However, through the development and release of Japanese Stable Diffusion, we hope to communicate to the research community the importance and potential of language-specific model development.
rinna Co., Ltd. has released GPT and BERT models for Japanese text, and CLIP, CLOOB, and Japanese Stable Diffusion models for Japanese text and images. We will continue to improve these models and next we will consider releasing models based on self-supervised learning specialized for Japanese speech.
