


!pip install transformers==4.2.1
!pip install sentencepiece==0.1.95
The transformer-based encoder-decoder model was introduced by Vaswani
et al. in the famous Attention is all you need
paper and is today the de-facto
standard encoder-decoder architecture in natural language processing
(NLP).
Recently, there has been a lot of research on different pre-training
objectives for transformer-based encoder-decoder models, e.g. T5,
Bart, Pegasus, ProphetNet, Marge, etc…, but the model architecture
has stayed largely the same.
The goal of the blog post is to give an in-detail explanation of
how the transformer-based encoder-decoder architecture models
sequence-to-sequence problems. We will focus on the mathematical model
defined by the architecture and how the model can be used in inference.
Along the way, we will give some background on sequence-to-sequence
models in NLP and break down the transformer-based encoder-decoder
architecture into its encoder and decoder parts. We provide many
illustrations and establish the link between the theory of
transformer-based encoder-decoder models and their practical usage in
🤗Transformers for inference. Note that this blog post does not explain
how such models can be trained – this will be the topic of a future blog
post.
Transformer-based encoder-decoder models are the result of years of
research on representation learning and model architectures. This
notebook provides a short summary of the history of neural
encoder-decoder models. For more context, the reader is advised to read
this awesome blog
post by
Sebastion Ruder. Additionally, a basic understanding of the
self-attention architecture is recommended. The following blog post by
Jay Alammar serves as a good refresher on the original Transformer model
here.
At the time of writing this notebook, 🤗Transformers comprises the
encoder-decoder models T5, Bart, MarianMT, and Pegasus, which
are summarized in the docs under model
summaries.
The notebook is divided into four parts:
- Background – A short history of neural encoder-decoder models
is given with a focus on RNN-based models. - Encoder-Decoder – The transformer-based encoder-decoder model
is presented and it is explained how the model is used for
inference. - Encoder – The encoder part of the model is explained in
detail. - Decoder – The decoder part of the model is explained in
detail.
Each part builds upon the previous part, but can also be read on its
own.
Background
Tasks in natural language generation (NLG), a subfield of NLP, are best
expressed as sequence-to-sequence problems. Such tasks can be defined as
finding a model that maps a sequence of input words to a sequence of
target words. Some classic examples are summarization and
translation. In the following, we assume that each word is encoded
into a vector representation. input words can then be represented as
a sequence of input vectors:
Consequently, sequence-to-sequence problems can be solved by finding a
mapping from an input sequence of vectors to
a sequence of target vectors , whereas the number
of target vectors is unknown apriori and depends on the input
sequence:
Sutskever et al. (2014) noted that
deep neural networks (DNN)s, “*despite their flexibility and power can
only define a mapping whose inputs and targets can be sensibly encoded
with vectors of fixed dimensionality.*”
Using a DNN model to solve sequence-to-sequence problems would
therefore mean that the number of target vectors has to be known
apriori and would have to be independent of the input . This is suboptimal because, for tasks in NLG, the
number of target words usually depends on the input
and not just on the input length . E.g., an article of 1000 words
can be summarized to both 200 words and 100 words depending on its
content.
In 2014, Cho et al. and
Sutskever et al. proposed to use an
encoder-decoder model purely based on recurrent neural networks (RNNs)
for sequence-to-sequence tasks. In contrast to DNNS, RNNs are capable
of modeling a mapping to a variable number of target vectors. Let’s
dive a bit deeper into the functioning of RNN-based encoder-decoder
models.
During inference, the encoder RNN encodes an input sequence by successively updating its hidden state .
After having processed the last input vector , the
encoder’s hidden state defines the input encoding . Thus,
the encoder defines the mapping:
Then, the decoder’s hidden state is initialized with the input encoding
and during inference, the decoder RNN is used to auto-regressively
generate the target sequence. Let’s explain.
Mathematically, the decoder defines the probability distribution of a
target sequence given the hidden state :
By Bayes’ rule the distribution can be decomposed into conditional
distributions of single target vectors as follows:
Thus, if the architecture can model the conditional distribution of the
next target vector, given all previous target vectors:
then it can model the distribution of any target vector sequence given
the hidden state by simply multiplying all conditional
probabilities.
So how does the RNN-based decoder architecture model ?
In computational terms, the model sequentially maps the previous inner
hidden state and the previous target vector to the current inner hidden state and a
logit vector (shown in dark red below):
is thereby defined as being the output
hidden state of the RNN-based encoder. Subsequently, the softmax
operation is used to transform the logit vector to a
conditional probablity distribution of the next target vector:
For more detail on the logit vector and the resulting probability
distribution, please see footnote . From the above equation, we
can see that the distribution of the current target vector is directly conditioned on the previous target vector and the previous hidden state .
Because the previous hidden state depends on all
previous target vectors , it can
be stated that the RNN-based decoder implicitly (e.g. indirectly)
models the conditional distribution .
The space of possible target vector sequences is
prohibitively large so that at inference, one has to rely on decoding
methods that efficiently sample high probability target vector
sequences from .
Given such a decoding method, during inference, the next input vector can then be sampled from
and is consequently appended to the input sequence so that the decoder
RNN then models
to sample the next input vector and so on in an
auto-regressive fashion.
An important feature of RNN-based encoder-decoder models is the
definition of special vectors, such as the and vector. The vector often represents the final
input vector to “cue” the encoder that the input
sequence has ended and also defines the end of the target sequence. As
soon as the is sampled from a logit vector, the generation
is complete. The vector represents the input vector fed to the decoder RNN at the very first decoding step.
To output the first logit , an input is required and since
no input has been generated at the first step a special
input vector is fed to the decoder RNN. Ok – quite complicated! Let’s
illustrate and walk through an example.
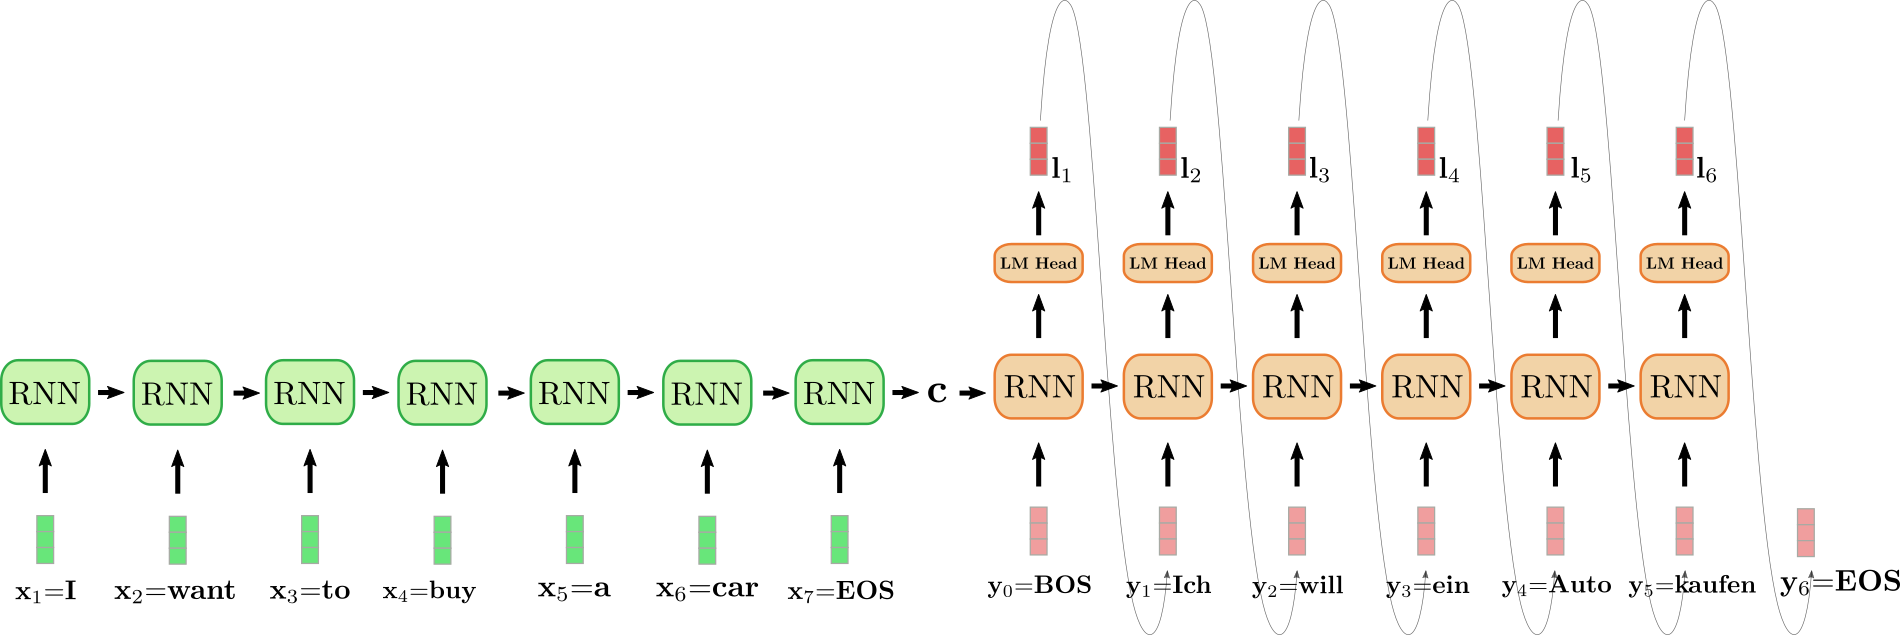
The unfolded RNN encoder is colored in green and the unfolded RNN
decoder is colored in red.
The English sentence “I want to buy a car”, represented by , , , , , and is translated into German: “Ich will ein
Auto kaufen” defined as , , , , and . To begin with, the input vector is processed by the encoder RNN and updates
its hidden state. Note that because we are only interested in the final
encoder’s hidden state , we can disregard the RNN
encoder’s target vector. The encoder RNN then processes the rest of the
input sentence , , , , , in the same fashion, updating its hidden
state at each step until the vector is reached . In the illustration above the horizontal arrow connecting the
unfolded encoder RNN represents the sequential updates of the hidden
state. The final hidden state of the encoder RNN, represented by then completely defines the encoding of the input
sequence and is used as the initial hidden state of the decoder RNN.
This can be seen as conditioning the decoder RNN on the encoded input.
To generate the first target vector, the decoder is fed the
vector, illustrated as in the design above. The target
vector of the RNN is then further mapped to the logit vector by means of the LM Head feed-forward layer to define
the conditional distribution of the first target vector as explained
above:
The word is sampled (shown by the grey arrow, connecting and ) and consequently the second target
vector can be sampled:
And so on until at step , the vector is sampled from and the decoding is finished. The resulting target
sequence amounts to , which is
“Ich will ein Auto kaufen” in our example above.
To sum it up, an RNN-based encoder-decoder model, represented by and defines
the distribution by
factorization:
During inference, efficient decoding methods can auto-regressively
generate the target sequence .
The RNN-based encoder-decoder model took the NLG community by storm. In
2016, Google announced to fully replace its heavily feature engineered
translation service by a single RNN-based encoder-decoder model (see
here).
Nevertheless, RNN-based encoder-decoder models have two pitfalls. First,
RNNs suffer from the vanishing gradient problem, making it very
difficult to capture long-range dependencies, cf. Hochreiter et al.
(2001). Second,
the inherent recurrent architecture of RNNs prevents efficient
parallelization when encoding, cf. Vaswani et al.
(2017).
The original quote from the paper is “Despite their flexibility
and power, DNNs can only be applied to problems whose inputs and targets
can be sensibly encoded with vectors of fixed dimensionality“, which
is slightly adapted here.
The same holds essentially true for convolutional neural networks
(CNNs). While an input sequence of variable length can be fed into a
CNN, the dimensionality of the target will always be dependent on the
input dimensionality or fixed to a specific value.
At the first step, the hidden state is initialized as a zero
vector and fed to the RNN together with the first input vector .
A neural network can define a probability distribution over all
words, i.e. as
follows. First, the network defines a mapping from the inputs to an embedded vector representation , which corresponds to the RNN target vector. The embedded
vector representation is then passed to the “language
model head” layer, which means that it is multiplied by the word
embedding matrix, i.e. , so that a score
between and each encoded vector is computed. The resulting
vector is called the logit vector and can be
mapped to a probability distribution over all words by applying a
softmax operation: .
Beam-search decoding is an example of such a decoding method.
Different decoding methods are out of scope for this notebook. The
reader is advised to refer to this interactive
notebook on decoding
methods.
Sutskever et al. (2014)
reverses the order of the input so that in the above example the input
vectors would correspond to , , , , , and . The
motivation is to allow for a shorter connection between corresponding
word pairs such as and . The research group emphasizes that the
reversal of the input sequence was a key reason for their model’s
improved performance on machine translation.
Encoder-Decoder
In 2017, Vaswani et al. introduced the Transformer and thereby gave
birth to transformer-based encoder-decoder models.
Analogous to RNN-based encoder-decoder models, transformer-based
encoder-decoder models consist of an encoder and a decoder which are
both stacks of residual attention blocks. The key innovation of
transformer-based encoder-decoder models is that such residual attention
blocks can process an input sequence of variable
length without exhibiting a recurrent structure. Not relying on a
recurrent structure allows transformer-based encoder-decoders to be
highly parallelizable, which makes the model orders of magnitude more
computationally efficient than RNN-based encoder-decoder models on
modern hardware.
As a reminder, to solve a sequence-to-sequence problem, we need to
find a mapping of an input sequence to an output
sequence of variable length . Let’s see how
transformer-based encoder-decoder models are used to find such a
mapping.
Similar to RNN-based encoder-decoder models, the transformer-based
encoder-decoder models define a conditional distribution of target
vectors given an input sequence :
The transformer-based encoder part encodes the input sequence to a sequence of hidden states , thus defining the mapping:
The transformer-based decoder part then models the conditional
probability distribution of the target vector sequence given the sequence of encoded hidden states :
By Bayes’ rule, this distribution can be factorized to a product of
conditional probability distribution of the target vector
given the encoded hidden states and all
previous target vectors :
The transformer-based decoder hereby maps the sequence of encoded hidden
states and all previous target vectors to the logit vector . The logit
vector is then processed by the softmax operation to
define the conditional distribution ,
just as it is done for RNN-based decoders. However, in contrast to
RNN-based decoders, the distribution of the target vector
is explicitly (or directly) conditioned on all previous target vectors as we will see later in more
detail. The 0th target vector is hereby represented by a
special “begin-of-sentence” vector.
Having defined the conditional distribution ,
we can now auto-regressively generate the output and thus define a
mapping of an input sequence to an output sequence at inference.
Let’s visualize the complete process of auto-regressive generation of
transformer-based encoder-decoder models.
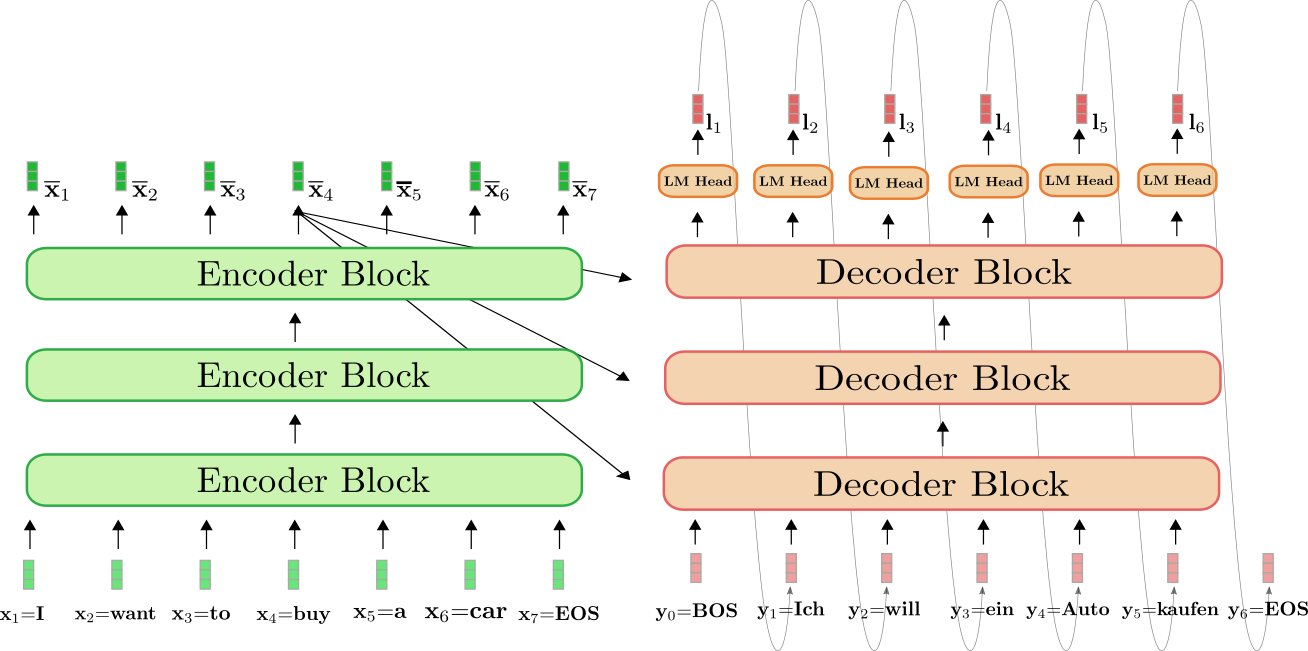
The transformer-based encoder is colored in green and the
transformer-based decoder is colored in red. As in the previous section,
we show how the English sentence “I want to buy a car”, represented by , , , , , , and is translated into German: “Ich will ein
Auto kaufen” defined as , , , , , and .
To begin with, the encoder processes the complete input sequence = “I want to buy a car” (represented by the light
green vectors) to a contextualized encoded sequence . E.g. defines
an encoding that depends not only on the input = “buy”,
but also on all other words “I”, “want”, “to”, “a”, “car” and
“EOS”, i.e. the context.
Next, the input encoding together with the
BOS vector, i.e. , is fed to the decoder. The decoder
processes the inputs and to
the first logit (shown in darker red) to define the
conditional distribution of the first target vector :
Next, the first target vector = is sampled
from the distribution (represented by the grey arrows) and can now be
fed to the decoder again. The decoder now processes both
= “BOS” and = “Ich” to define the conditional
distribution of the second target vector :
We can sample again and produce the target vector =
“will”. We continue in auto-regressive fashion until at step 6 the EOS
vector is sampled from the conditional distribution:
And so on in auto-regressive fashion.
It is important to understand that the encoder is only used in the first
forward pass to map to .
As of the second forward pass, the decoder can directly make use of the
previously calculated encoding . For
clarity, let’s illustrate the first and the second forward pass for our
example above.
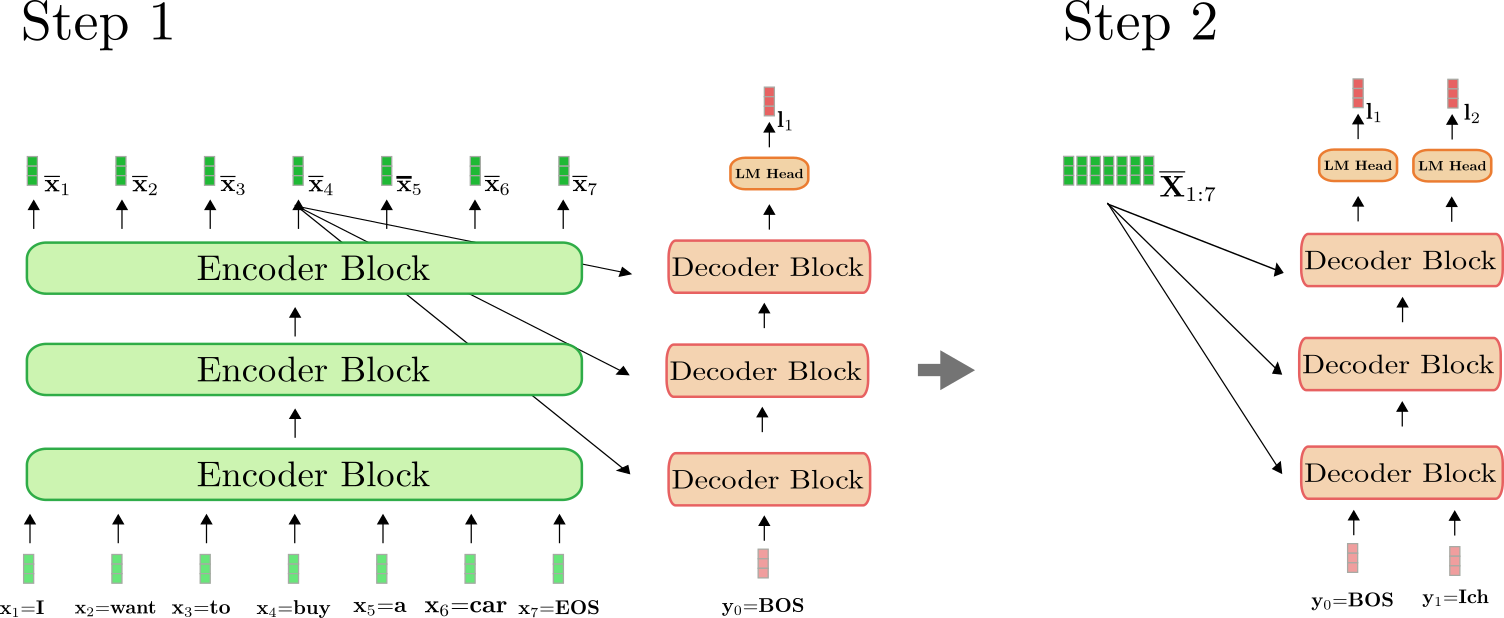
As can be seen, only in step do we have to encode “I want to buy
a car EOS” to . At step , the
contextualized encodings of “I want to buy a car EOS” are simply
reused by the decoder.
In 🤗Transformers, this auto-regressive generation is done under-the-hood
when calling the .generate() method. Let’s use one of our translation
models to see this in action.
from transformers import MarianMTModel, MarianTokenizer

tokenizer = MarianTokenizer.from_pretrained("Helsinki-NLP/opus-mt-en-de")
model = MarianMTModel.from_pretrained("Helsinki-NLP/opus-mt-en-de")


input_ids = tokenizer("I want to buy a car", return_tensors="pt").input_ids


output_ids = model.generate(input_ids)[0]


print(tokenizer.decode(output_ids))
Output:
Ich will ein Auto kaufen
Calling .generate() does many things under-the-hood. First, it passes
the input_ids to the encoder. Second, it passes a pre-defined token, which is the symbol in the case of
MarianMTModel along with the encoded input_ids to the decoder.
Third, it applies the beam search decoding mechanism to
auto-regressively sample the next output word of the last decoder
output . For more detail on how beam search decoding works, one is
advised to read this blog
post.
In the Appendix, we have included a code snippet that shows how a simple
generation method can be implemented “from scratch”. To fully
understand how auto-regressive generation works under-the-hood, it is
highly recommended to read the Appendix.
To sum it up:
- The transformer-based encoder defines a mapping from the input
sequence to a contextualized encoding sequence
. - The transformer-based decoder defines the conditional distribution
. - Given an appropriate decoding mechanism, the output sequence
can auto-regressively be sampled from
.
Great, now that we have gotten a general overview of how
transformer-based encoder-decoder models work, we can dive deeper into
both the encoder and decoder part of the model. More specifically, we
will see exactly how the encoder makes use of the self-attention layer
to yield a sequence of context-dependent vector encodings and how
self-attention layers allow for efficient parallelization. Then, we will
explain in detail how the self-attention layer works in the decoder
model and how the decoder is conditioned on the encoder’s output with
cross-attention layers to define the conditional distribution .
Along, the way it will become obvious how transformer-based
encoder-decoder models solve the long-range dependencies problem of
RNN-based encoder-decoder models.
In the case of "Helsinki-NLP/opus-mt-en-de", the decoding
parameters can be accessed
here,
where we can see that model applies beam search with num_beams=6.
Encoder
As mentioned in the previous section, the transformer-based encoder
maps the input sequence to a contextualized encoding sequence:
Taking a closer look at the architecture, the transformer-based encoder
is a stack of residual encoder blocks. Each encoder block consists of
a bi-directional self-attention layer, followed by two feed-forward
layers. For simplicity, we disregard the normalization layers in this
notebook. Also, we will not further discuss the role of the two
feed-forward layers, but simply see it as a final vector-to-vector
mapping required in each encoder block . The bi-directional
self-attention layer puts each input vector into relation with all
input vectors and by doing so
transforms the input vector to a more “refined”
contextual representation of itself, defined as .
Thereby, the first encoder block transforms each input vector of the
input sequence (shown in light green below) from a
context-independent vector representation to a context-dependent
vector representation, and the following encoder blocks further refine
this contextual representation until the last encoder block outputs the
final contextual encoding (shown in darker
green below).
Let’s visualize how the encoder processes the input sequence “I want
to buy a car EOS” to a contextualized encoding sequence. Similar to
RNN-based encoders, transformer-based encoders also add a special
“end-of-sequence” input vector to the input sequence to hint to the
model that the input vector sequence is finished .
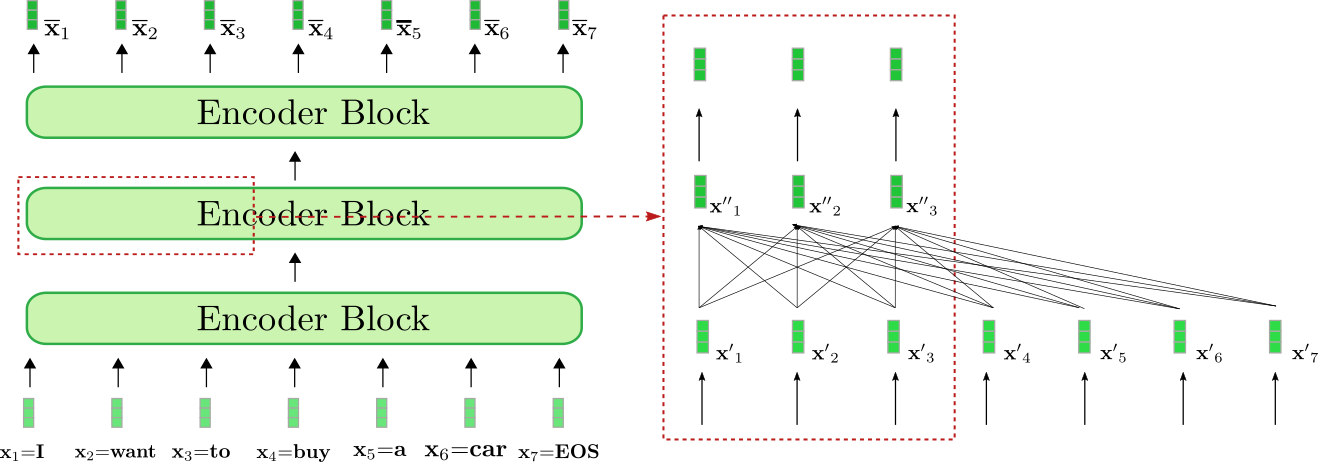
Our exemplary transformer-based encoder is composed of three encoder
blocks, whereas the second encoder block is shown in more detail in the
red box on the right for the first three input vectors . The bi-directional
self-attention mechanism is illustrated by the fully-connected graph in
the lower part of the red box and the two feed-forward layers are shown
in the upper part of the red box. As stated before, we will focus only
on the bi-directional self-attention mechanism.
As can be seen each output vector of the self-attention layer depends directly on
all input vectors . This means,
e.g. that the input vector representation of the word “want”, i.e. , is put into direct relation with the word “buy”,
i.e. , but also with the word “I”,i.e. . The output vector representation of “want”, i.e. , thus represents a more refined contextual
representation for the word “want”.
Let’s take a deeper look at how bi-directional self-attention works.
Each input vector of an input sequence of an encoder block is projected to a key vector , value vector and query vector (shown in orange, blue, and purple respectively below)
through three trainable weight matrices :
Note, that the same weight matrices are applied to each input vector . After projecting each
input vector to a query, key, and value vector, each
query vector is compared
to all key vectors . The more
similar one of the key vectors is to
a query vector , the more important is the corresponding
value vector for the output vector . More
specifically, an output vector is defined as the
weighted sum of all value vectors
plus the input vector . Thereby, the weights are
proportional to the cosine similarity between and the
respective key vectors , which is
mathematically expressed by as
illustrated in the equation below. For a complete description of the
self-attention layer, the reader is advised to take a look at
this blog post or
the original paper.
Alright, this sounds quite complicated. Let’s illustrate the
bi-directional self-attention layer for one of the query vectors of our
example above. For simplicity, it is assumed that our exemplary
transformer-based decoder uses only a single attention head
config.num_heads = 1 and that no normalization is applied.
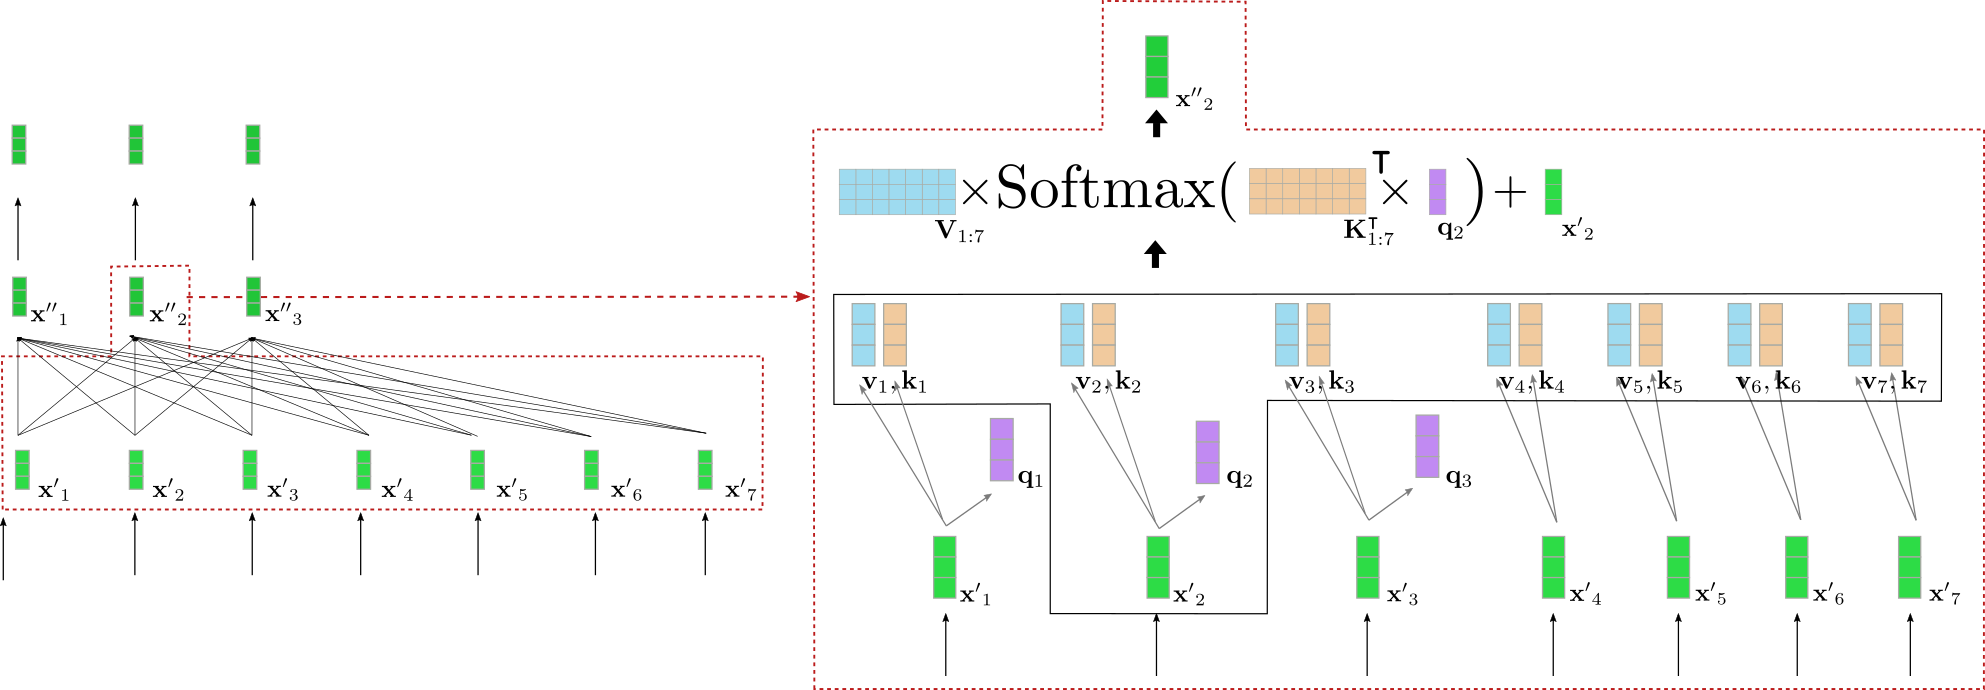
On the left, the previously illustrated second encoder block is shown
again and on the right, an in detail visualization of the bi-directional
self-attention mechanism is given for the second input vector that corresponds to the input word “want”. At first
all input vectors are projected
to their respective query vectors
(only the first three query vectors are shown in purple above), value
vectors (shown in blue), and key
vectors (shown in orange). The
query vector is then multiplied by the transpose of all
key vectors, i.e. followed by the
softmax operation to yield the self-attention weights. The
self-attention weights are finally multiplied by the respective value
vectors and the input vector is added to output the
“refined” representation of the word “want”, i.e.
(shown in dark green on the right). The whole equation is illustrated in
the upper part of the box on the right. The multiplication of and thereby makes it
possible to compare the vector representation of “want” to all other
input vector representations “I”, “to”, “buy”, “a”, “car”,
“EOS” so that the self-attention weights mirror the importance each of
the other input vector representations for the refined representation of the word “want”.
To further understand the implications of the bi-directional
self-attention layer, let’s assume the following sentence is processed:
“The house is beautiful and well located in the middle of the city
where it is easily accessible by public transport“. The word “it”
refers to “house”, which is 12 “positions away”. In
transformer-based encoders, the bi-directional self-attention layer
performs a single mathematical operation to put the input vector of
“house” into relation with the input vector of “it” (compare to the
first illustration of this section). In contrast, in an RNN-based
encoder, a word that is 12 “positions away”, would require at least 12
mathematical operations meaning that in an RNN-based encoder a linear
number of mathematical operations are required. This makes it much
harder for an RNN-based encoder to model long-range contextual
representations. Also, it becomes clear that a transformer-based encoder
is much less prone to lose important information than an RNN-based
encoder-decoder model because the sequence length of the encoding is
kept the same, i.e. ,
while an RNN compresses the length from to just , which makes it very difficult for RNNs
to effectively encode long-range dependencies between input words.
In addition to making long-range dependencies more easily learnable, we
can see that the Transformer architecture is able to process text in
parallel.Mathematically, this can easily be shown by writing the
self-attention formula as a product of query, key, and value matrices:
The output
is computed via a series of matrix multiplications and a softmax
operation, which can be parallelized effectively. Note, that in an
RNN-based encoder model, the computation of the hidden state has to be done sequentially: Compute hidden state of the
first input vector , then compute the hidden state of the
second input vector that depends on the hidden state of the first hidden
vector, etc. The sequential nature of RNNs prevents effective
parallelization and makes them much more inefficient compared to
transformer-based encoder models on modern GPU hardware.
Great, now we should have a better understanding of a) how
transformer-based encoder models effectively model long-range contextual
representations and b) how they efficiently process long sequences of
input vectors.
Now, let’s code up a short example of the encoder part of our
MarianMT encoder-decoder models to verify that the explained theory
holds in practice.
An in-detail explanation of the role the feed-forward layers play
in transformer-based models is out-of-scope for this notebook. It is
argued in Yun et. al, (2017)
that feed-forward layers are crucial to map each contextual vector individually to the desired output space, which the
self-attention layer does not manage to do on its own. It should be
noted here, that each output token is processed by the
same feed-forward layer. For more detail, the reader is advised to read
the paper.
However, the EOS input vector does not have to be appended to the
input sequence, but has been shown to improve performance in many cases.
In contrast to the 0th target vector of the
transformer-based decoder is required as a starting input vector to
predict a first target vector.
from transformers import MarianMTModel, MarianTokenizer
import torch

tokenizer = MarianTokenizer.from_pretrained("Helsinki-NLP/opus-mt-en-de")
model = MarianMTModel.from_pretrained("Helsinki-NLP/opus-mt-en-de")

embeddings = model.get_input_embeddings()


input_ids = tokenizer("I want to buy a car", return_tensors="pt").input_ids


encoder_hidden_states = model.base_model.encoder(input_ids, return_dict=True).last_hidden_state


input_ids_perturbed = tokenizer("I want to buy a house", return_tensors="pt").input_ids
encoder_hidden_states_perturbed = model.base_model.encoder(input_ids_perturbed, return_dict=True).last_hidden_state


print(f"Length of input embeddings {embeddings(input_ids).shape[1]}. Length of encoder_hidden_states {encoder_hidden_states.shape[1]}")


print("Is encoding for `I` equal to its perturbed version?: ", torch.allclose(encoder_hidden_states[0, 0], encoder_hidden_states_perturbed[0, 0], atol=1e-3))
Outputs:
    Length of input embeddings 7. Length of encoder_hidden_states 7
    Is encoding for `I` equal to its perturbed version?:  False
We compare the length of the input word embeddings, i.e.
embeddings(input_ids) corresponding to , with the
length of the encoder_hidden_states, corresponding to . Also, we have forwarded the word sequence
“I want to buy a car” and a slightly perturbated version “I want to
buy a house” through the encoder to check if the first output encoding,
corresponding to “I”, differs when only the last word is changed in
the input sequence.
As expected the output length of the input word embeddings and encoder
output encodings, i.e. and , is equal. Second, it can be
noted that the values of the encoded output vector of are different when the last word
is changed from “car” to “house”. This however should not come as a
surprise if one has understood bi-directional self-attention.
On a side-note, autoencoding models, such as BERT, have the exact same
architecture as transformer-based encoder models. Autoencoding
models leverage this architecture for massive self-supervised
pre-training on open-domain text data so that they can map any word
sequence to a deep bi-directional representation. In Devlin et al.
(2018), the authors show that a
pre-trained BERT model with a single task-specific classification layer
on top can achieve SOTA results on eleven NLP tasks. All autoencoding
models of 🤗Transformers can be found
here.
Decoder
As mentioned in the Encoder-Decoder section, the transformer-based
decoder defines the conditional probability distribution of a target
sequence given the contextualized encoding sequence:
which by Bayes’ rule can be decomposed into a product of conditional
distributions of the next target vector given the contextualized
encoding sequence and all previous target vectors:
Let’s first understand how the transformer-based decoder defines a
probability distribution. The transformer-based decoder is a stack of
decoder blocks followed by a dense layer, the “LM head”. The stack
of decoder blocks maps the contextualized encoding sequence and a target vector sequence prepended by
the vector and cut to the last target vector, i.e. , to an encoded sequence of target vectors . Then, the “LM head” maps the encoded
sequence of target vectors to a
sequence of logit vectors , whereas the
dimensionality of each logit vector corresponds to the
size of the vocabulary. This way, for each a
probability distribution over the whole vocabulary can be obtained by
applying a softmax operation on . These distributions
define the conditional distribution:
respectively. The “LM head” is often tied to the transpose of the word
embedding matrix, i.e. . Intuitively this means that for all
the “LM Head” layer compares the encoded output vector to all word embeddings in the vocabulary so that the logit
vector represents the similarity scores between the
encoded output vector and each word embedding. The softmax operation
simply transformers the similarity scores to a probability distribution.
For each , the following equations hold:
Putting it all together, in order to model the conditional distribution
of a target vector sequence , the target vectors prepended by the special vector,
i.e. , are first mapped together with the contextualized
encoding sequence to the logit vector
sequence . Consequently, each logit target vector is transformed into a conditional probability
distribution of the target vector using the softmax
operation. Finally, the conditional probabilities of all target vectors multiplied together to yield the
conditional probability of the complete target vector sequence:
In contrast to transformer-based encoders, in transformer-based
decoders, the encoded output vector should be
a good representation of the next target vector and
not of the input vector itself. Additionally, the encoded output vector should be conditioned on all contextualized
encoding sequence . To meet these
requirements each decoder block consists of a uni-directional
self-attention layer, followed by a cross-attention layer and two
feed-forward layers . The uni-directional self-attention layer
puts each of its input vectors only into relation with
all previous input vectors for
all to model the probability distribution of
the next target vectors. The cross-attention layer puts each of its
input vectors into relation with all contextualized
encoding vectors to condition the
probability distribution of the next target vectors on the input of the
encoder as well.
Alright, let’s visualize the transformer-based decoder for our
English to German translation example.
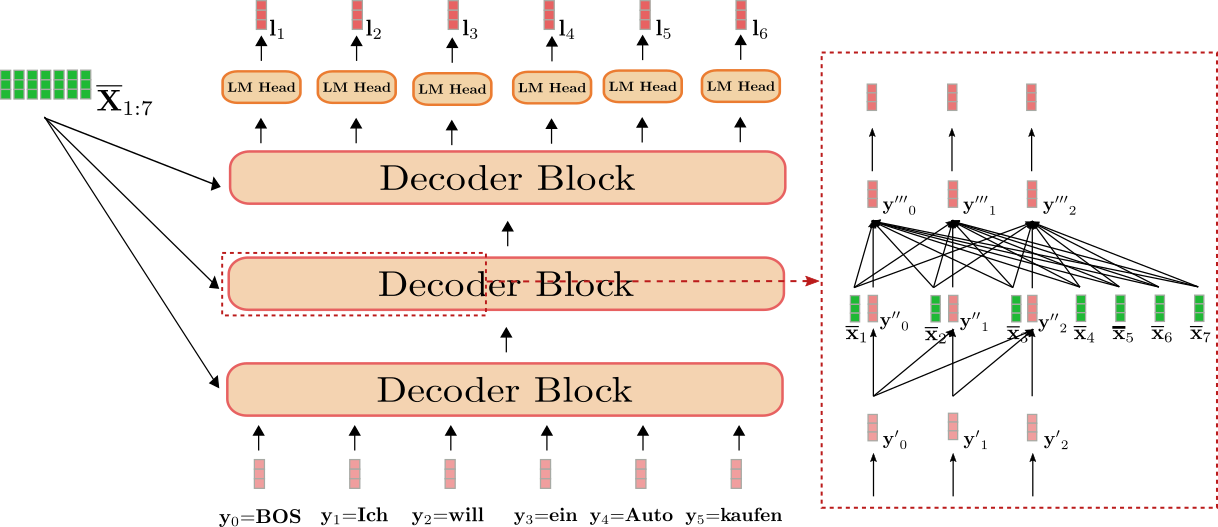
We can see that the decoder maps the input “BOS”,
“Ich”, “will”, “ein”, “Auto”, “kaufen” (shown in light red)
together with the contextualized sequence of “I”, “want”, “to”,
“buy”, “a”, “car”, “EOS”, i.e.
(shown in dark green) to the logit vectors (shown in
dark red).
Applying a softmax operation on each can thus define the
conditional probability distributions:
The overall conditional probability of:
can therefore be computed as the following product:
The red box on the right shows a decoder block for the first three
target vectors . In the lower
part, the uni-directional self-attention mechanism is illustrated and in
the middle, the cross-attention mechanism is illustrated. Let’s first
focus on uni-directional self-attention.
As in bi-directional self-attention, in uni-directional self-attention,
the query vectors (shown in
purple below), key vectors
(shown in orange below), and value vectors (shown in blue below) are
projected from their respective input vectors (shown in light red below).
However, in uni-directional self-attention, each query vector is compared only to its respective key vector and all
previous ones, namely to yield the
respective attention weights. This prevents an output vector (shown in dark red below) to include any information
about the following input vector for
all . As is the case in bi-directional
self-attention, the attention weights are then multiplied by their
respective value vectors and summed together.
We can summarize uni-directional self-attention as follows:
Note that the index range of the key and value vectors is instead
of which would be the range of the key vectors in
bi-directional self-attention.
Let’s illustrate uni-directional self-attention for the input vector for our example above.
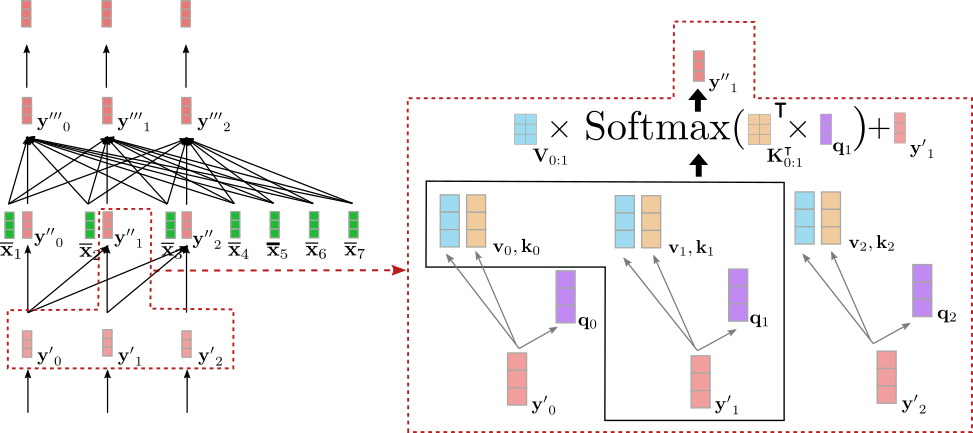
As can be seen only depends on and . Therefore, we put the vector representation of the word
“Ich”, i.e. only into relation with itself and the
“BOS” target vector, i.e. , but not with the
vector representation of the word “will”, i.e. .
So why is it important that we use uni-directional self-attention in the
decoder instead of bi-directional self-attention? As stated above, a
transformer-based decoder defines a mapping from a sequence of input
vector to the logits corresponding to the next
decoder input vectors, namely . In our example, this
means, e.g. that the input vector = “Ich” is mapped
to the logit vector , which is then used to predict the
input vector . Thus, if would have access
to the following input vectors , the decoder would
simply copy the vector representation of “will”, i.e. , to be its output . This would be
forwarded to the last layer so that the encoded output vector would essentially just correspond to the
vector representation .
This is obviously disadvantageous as the transformer-based decoder would
never learn to predict the next word given all previous words, but just
copy the target vector through the network to for all . In
order to define a conditional distribution of the next target vector,
the distribution cannot be conditioned on the next target vector itself.
It does not make much sense to predict from because the
distribution is conditioned on the target vector it is supposed to
model. The uni-directional self-attention architecture, therefore,
allows us to define a causal probability distribution, which is
necessary to effectively model a conditional distribution of the next
target vector.
Great! Now we can move to the layer that connects the encoder and
decoder – the cross-attention mechanism!
The cross-attention layer takes two vector sequences as inputs: the
outputs of the uni-directional self-attention layer, i.e. and the contextualized encoding vectors . As in the self-attention layer, the query
vectors are projections of the
output vectors of the previous layer, i.e. .
However, the key and value vectors and are projections of the
contextualized encoding vectors . Having
defined key, value, and query vectors, a query vector is
then compared to all key vectors and the corresponding score is used
to weight the respective value vectors, just as is the case for
bi-directional self-attention to give the output vector for all . Cross-attention
can be summarized as follows:
Note that the index range of the key and value vectors is
corresponding to the number of contextualized encoding vectors.
Let’s visualize the cross-attention mechanism for the input
vector for our example above.
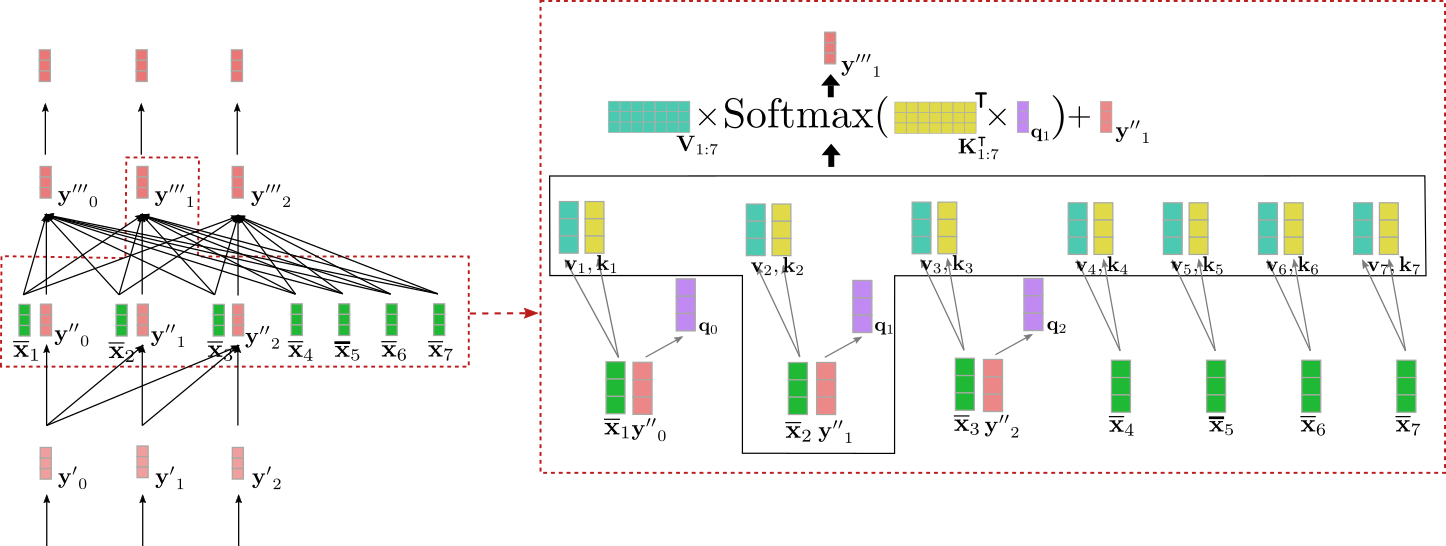
We can see that the query vector (shown in purple) is
derived from (shown in red) and therefore relies on a vector
representation of the word “Ich”. The query vector
is then compared to the key vectors (shown in yellow) corresponding to
the contextual encoding representation of all encoder input vectors = “I want to buy a car EOS”. This puts the vector
representation of “Ich” into direct relation with all encoder input
vectors. Finally, the attention weights are multiplied by the value
vectors (shown in turquoise) to
yield in addition to the input vector the output vector (shown in dark red).
So intuitively, what happens here exactly? Each output vector is a weighted sum of all value projections of the
encoder inputs plus the input
vector itself (c.f. illustrated formula above). The key
mechanism to understand is the following: Depending on how similar a
query projection of the input decoder vector is to a
key projection of the encoder input vector , the more
important is the value projection of the encoder input vector . In loose terms this means, the more “related” a
decoder input representation is to an encoder input representation, the
more does the input representation influence the decoder output
representation.
Cool! Now we can see how this architecture nicely conditions each output
vector on the interaction between the encoder input
vectors and the input vector . Another important observation at this point is that
the architecture is completely independent of the number of
contextualized encoding vectors on which
the output vector is conditioned on. All projection
matrices and to derive the key vectors and the value vectors respectively are shared across all
positions and all value vectors are summed together to a single
weighted averaged vector. Now it becomes obvious as well, why the
transformer-based decoder does not suffer from the long-range dependency
problem, the RNN-based decoder suffers from. Because each decoder logit
vector is directly dependent on every single encoded output vector,
the number of mathematical operations to compare the first encoded
output vector and the last decoder logit vector amounts essentially to
just one.
To conclude, the uni-directional self-attention layer is responsible for
conditioning each output vector on all previous decoder input vectors
and the current input vector and the cross-attention layer is
responsible to further condition each output vector on all encoded input
vectors.
To verify our theoretical understanding, let’s continue our code
example from the encoder section above.
The word embedding matrix gives each
input word a unique context-independent vector representation. This
matrix is often fixed as the “LM Head” layer. However, the “LM Head”
layer can very well consist of a completely independent “encoded
vector-to-logit” weight mapping.
Again, an in-detail explanation of the role the feed-forward
layers play in transformer-based models is out-of-scope for this
notebook. It is argued in Yun et. al,
(2017) that feed-forward layers
are crucial to map each contextual vector individually
to the desired output space, which the self-attention layer does not
manage to do on its own. It should be noted here, that each output token is processed by the same feed-forward layer. For more
detail, the reader is advised to read the paper.
from transformers import MarianMTModel, MarianTokenizer
import torch
tokenizer = MarianTokenizer.from_pretrained("Helsinki-NLP/opus-mt-en-de")
model = MarianMTModel.from_pretrained("Helsinki-NLP/opus-mt-en-de")
embeddings = model.get_input_embeddings()
input_ids = tokenizer("I want to buy a car", return_tensors="pt").input_ids
encoder_output_vectors = model.base_model.encoder(input_ids, return_dict=True).last_hidden_state
decoder_input_ids = tokenizer(" Ich will ein" , return_tensors="pt", add_special_tokens=False).input_ids
decoder_output_vectors = model.base_model.decoder(decoder_input_ids, encoder_hidden_states=encoder_output_vectors).last_hidden_state
lm_logits = torch.nn.functional.linear(decoder_output_vectors, embeddings.weight, bias=model.final_logits_bias)
decoder_input_ids_perturbed = tokenizer(" Ich will das" , return_tensors="pt", add_special_tokens=False).input_ids
decoder_output_vectors_perturbed = model.base_model.decoder(decoder_input_ids_perturbed, encoder_hidden_states=encoder_output_vectors).last_hidden_state
lm_logits_perturbed = torch.nn.functional.linear(decoder_output_vectors_perturbed, embeddings.weight, bias=model.final_logits_bias)
print(f"Shape of decoder input vectors {embeddings(decoder_input_ids).shape}. Shape of decoder logits {lm_logits.shape}")
print("Is encoding for `Ich` equal to its perturbed version?: ", torch.allclose(lm_logits[0, 0], lm_logits_perturbed[0, 0], atol=1e-3))
Output:
    Shape of decoder input vectors torch.Size([1, 5, 512]). Shape of decoder logits torch.Size([1, 5, 58101])
    Is encoding for `Ich` equal to its perturbed version?:  True
We compare the output shape of the decoder input word embeddings, i.e.
embeddings(decoder_input_ids) (corresponds to ,
here
tokens) with the dimensionality of the lm_logits(corresponds to ). Also, we have passed the word sequence
“
“
encoder_output_vectors through the decoder to check if the second
lm_logit, corresponding to “Ich”, differs when only the last word is
changed in the input sequence (“ein” -> “das”).
As expected the output shapes of the decoder input word embeddings and
lm_logits, i.e. the dimensionality of and are different in the last dimension. While the
sequence length is the same (=5), the dimensionality of a decoder input
word embedding corresponds to model.config.hidden_size, whereas the
dimensionality of a lm_logit corresponds to the vocabulary size
model.config.vocab_size, as explained above. Second, it can be noted
that the values of the encoded output vector of are the same when the last word is changed
from “ein” to “das”. This however should not come as a surprise if
one has understood uni-directional self-attention.
On a final side-note, auto-regressive models, such as GPT2, have the
same architecture as transformer-based decoder models if one
removes the cross-attention layer because stand-alone auto-regressive
models are not conditioned on any encoder outputs. So auto-regressive
models are essentially the same as auto-encoding models but replace
bi-directional attention with uni-directional attention. These models
can also be pre-trained on massive open-domain text data to show
impressive performances on natural language generation (NLG) tasks. In
Radford et al.
(2019),
the authors show that a pre-trained GPT2 model can achieve SOTA or close
to SOTA results on a variety of NLG tasks without much fine-tuning. All
auto-regressive models of 🤗Transformers can be found
here.
Alright, that’s it! Now, you should have gotten a good understanding of
transformer-based encoder-decoder models and how to use them with the
🤗Transformers library.
Thanks a lot to Victor Sanh, Sasha Rush, Sam Shleifer, Oliver Åstrand,
Ted Moskovitz and Kristian Kyvik for giving valuable feedback.
Appendix
As mentioned above, the following code snippet shows how one can program
a simple generation method for transformer-based encoder-decoder
models. Here, we implement a simple greedy decoding method using
torch.argmax to sample the target vector.
from transformers import MarianMTModel, MarianTokenizer
import torch
tokenizer = MarianTokenizer.from_pretrained("Helsinki-NLP/opus-mt-en-de")
model = MarianMTModel.from_pretrained("Helsinki-NLP/opus-mt-en-de")
input_ids = tokenizer("I want to buy a car", return_tensors="pt").input_ids
decoder_input_ids = tokenizer("" , add_special_tokens=False, return_tensors="pt").input_ids
assert decoder_input_ids[0, 0].item() == model.config.decoder_start_token_id, "`decoder_input_ids` should correspond to `model.config.decoder_start_token_id`"
outputs = model(input_ids, decoder_input_ids=decoder_input_ids, return_dict=True)
encoded_sequence = (outputs.encoder_last_hidden_state,)
lm_logits = outputs.logits
next_decoder_input_ids = torch.argmax(lm_logits[:, -1:], axis=-1)
decoder_input_ids = torch.cat([decoder_input_ids, next_decoder_input_ids], axis=-1)
lm_logits = model(None, encoder_outputs=encoded_sequence, decoder_input_ids=decoder_input_ids, return_dict=True).logits
next_decoder_input_ids = torch.argmax(lm_logits[:, -1:], axis=-1)
decoder_input_ids = torch.cat([decoder_input_ids, next_decoder_input_ids], axis=-1)
lm_logits = model(None, encoder_outputs=encoded_sequence, decoder_input_ids=decoder_input_ids, return_dict=True).logits
next_decoder_input_ids = torch.argmax(lm_logits[:, -1:], axis=-1)
decoder_input_ids = torch.cat([decoder_input_ids, next_decoder_input_ids], axis=-1)
print(f"Generated so far: {tokenizer.decode(decoder_input_ids[0], skip_special_tokens=True)}")
Outputs:
Generated so far: Ich will ein
In this code example, we show exactly what was described earlier. We
pass an input “I want to buy a car” together with the
token to the encoder-decoder model and sample from the first logit (i.e. the first lm_logits line). Hereby, our sampling
strategy is simple: greedily choose the next decoder input vector that
has the highest probability. In an auto-regressive fashion, we then pass
the sampled decoder input vector together with the previous inputs to
the encoder-decoder model and sample again. We repeat this a third time.
As a result, the model has generated the words “Ich will ein”. The result
is spot-on – this is the beginning of the correct translation of the input.
In practice, more complicated decoding methods are used to sample the
lm_logits. Most of which are covered in
this blog post.
