Close Menu
techwavedispatch.com

    Subscribe to Updates

    Get the latest creative news from FooBar about art, design and business.

    What's Hot

    Accelerating SD Turbo and SDXL Turbo Inference with ONNX Runtime and Olive

    November 12, 2026

    ‘It’s a mistake for Nvidia to let Jensen resign’: reactions from tech leaders on Jensen Huang’s resignation

    November 12, 2026

    Deploy frontier AI models on AWS Trainium with SGLang-Neuron

    November 12, 2026
    Facebook X (Twitter) Instagram
    Trending
    • Accelerating SD Turbo and SDXL Turbo Inference with ONNX Runtime and Olive
    • ‘It’s a mistake for Nvidia to let Jensen resign’: reactions from tech leaders on Jensen Huang’s resignation
    • Deploy frontier AI models on AWS Trainium with SGLang-Neuron
    • Preference Tuning LLMs with Direct Preference Optimization Methods
    • How Natera designed an agentic AI system for lab ops with Amazon Bedrock AgentCore
    • Claude Meetings lets Anthropic’s AI join your video calls
    • Walmart Early Black Friday Deals Double as Great Gifts (2026)
    • Nebius tests the neocloud playbook with $40 billion in planned spending
    Facebook X (Twitter) Instagram
    techwavedispatch.com
    Subscribe
    Thursday, November 12
    • Home
    • AI Tools & Software
    • Machine Learning
    • Generative AI
    • Robotics & Automation
    • Future Tech & Hardware
    • AI in Business
    • Ethics & Regulations
    • More
      • Gadgets & Smart Devices
      • Cybersecurity & AI
      • Tech Breakthroughs
    techwavedispatch.com
    Home»Machine Learning»Deploy frontier AI models on AWS Trainium with SGLang-Neuron
    Machine Learning

    Deploy frontier AI models on AWS Trainium with SGLang-Neuron

    adminBy adminNovember 12, 2026No Comments4 Mins Read
    Facebook Twitter Pinterest LinkedIn Tumblr Email
    Deploy frontier AI models on AWS Trainium with SGLang-Neuron
    Share
    Facebook Twitter LinkedIn Pinterest Email

    Today, Amazon announced that SGLang-Neuron is publicly available and can be accessed through an AWS Deep Learning Container, released by RadixArk in collaboration with Annapurna Labs. With SGLang-Neuron, you can serve models and generate reinforcement learning (RL) rollouts with SGLang on AWS Trainium using the same SGLang interface you use today. Trainium is a portfolio of AWS AI chips that delivers strong economics for AI training and inference at scale. Now, running SGLang on Trainium follows the SGLang workflow you already know: you launch models through SGLang’s server interface and invoke the endpoint using the same generation APIs. Underneath that interface, SGLang-Neuron runs on native PyTorch. With its out-of-tree plugin design, Trainium support and SGLang core develop independently and iterate faster.

    How SGLang runs on Trainium

    SGLang-Neuron is an out-of-tree plugin that connects SGLang with AWS Trainium. Installing the plugin registers the neuron platform through SGLang’s plugin entry points, and setting SGLANG_PLATFORM=neuron selects it when the server starts. SGLang core continues to provide the API server, request lifecycle, RadixAttention, and prefix-cache bookkeeping. The plugin implements the Trainium-specific models, attention, mixture of experts (MoE), and the graph runner.
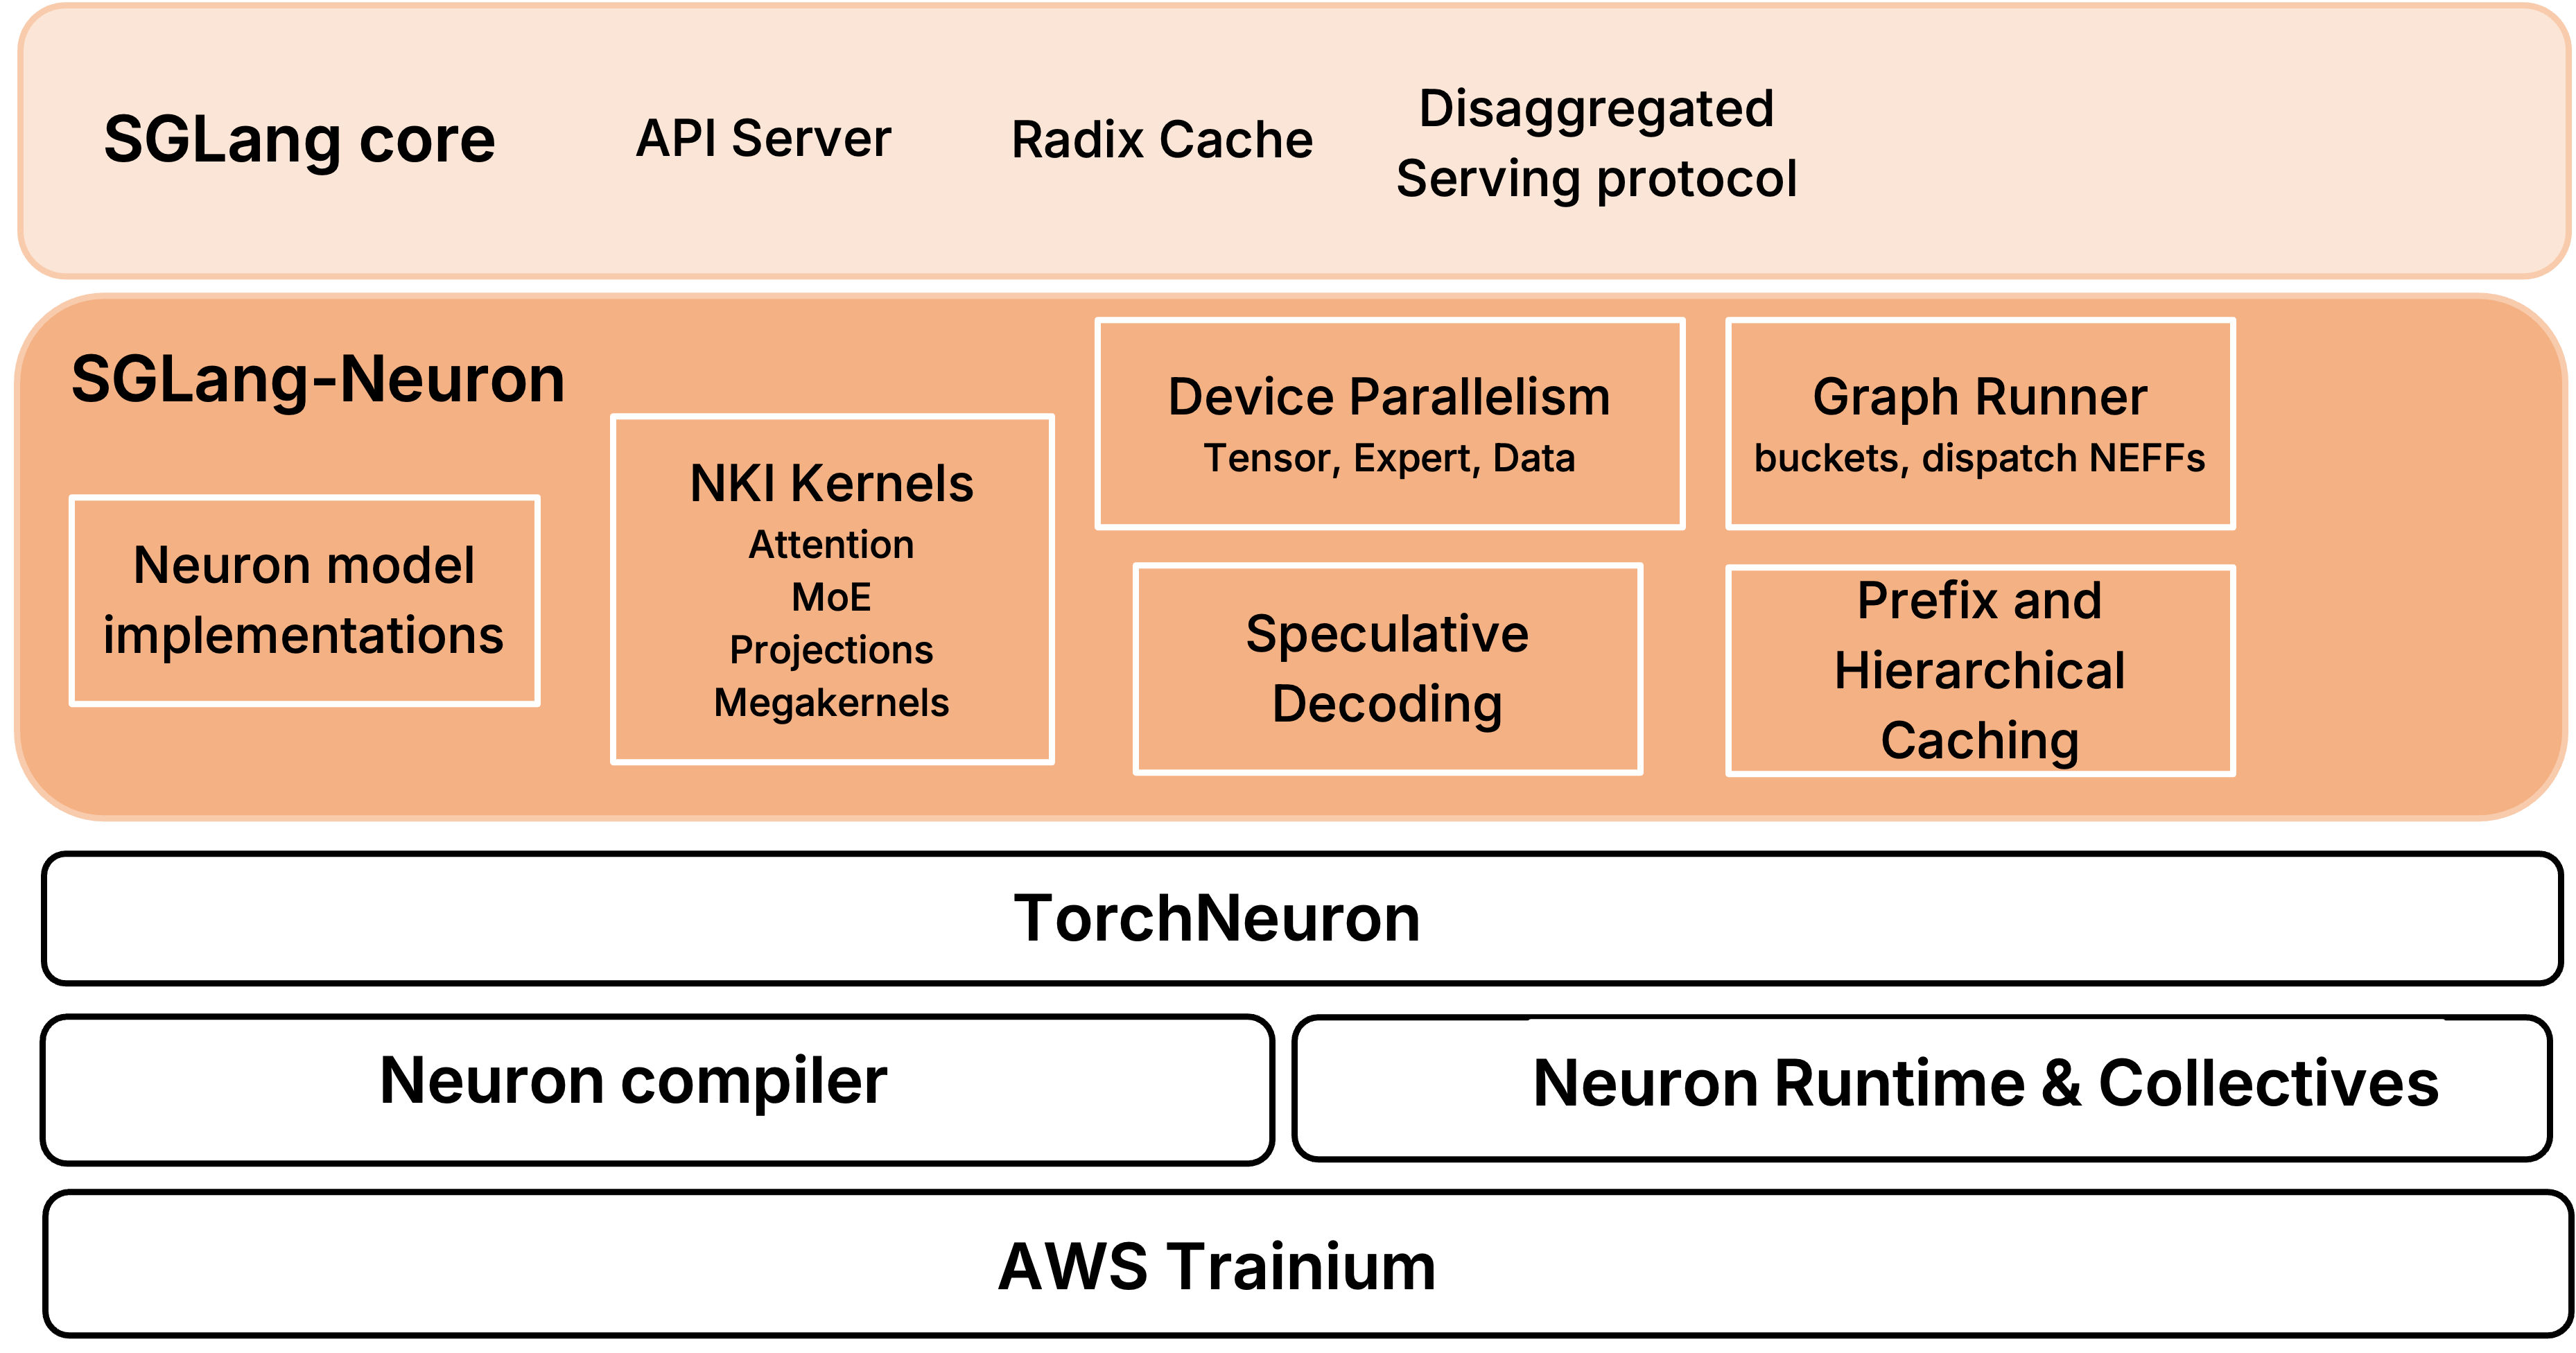
    Architecture of SGLang-Neuron on AWS Trainium, showing SGLang core and the Trainium plugin components

    Figure 1: SGLang-Neuron on AWS Trainium

    TorchNeuron registers Trainium as a native PyTorch device. SGLang-Neuron uses standard PyTorch operations for the model execution path and incorporates kernels written with the Neuron Kernel Interface (NKI) for performance. It compiles these operations and kernels into executable programs using torch.compile, which the graph runner prepares and executes during serving.

    SGLang-Neuron also supports PD disaggregation. In this configuration, a prefill server computes the prompt KV cache and transfers it to a decode server using NIXL over Elastic Fabric Adapter (EFA). The decode server then generates the remaining tokens. Each server still uses SGLang’s scheduler and request lifecycle, while the plugin manages the Trainium execution and KV-cache transfer path.

    Serving models on AWS Trainium using SGLang-Neuron

    To follow this walkthrough, you use a Trainium3 Amazon Elastic Compute Cloud (Amazon EC2) instance with a pytorch-inference-sglang-neuronx container. Here are the steps:

    1. Start the container.
      docker run --rm -it \
      --privileged --ipc=host \
      -v /path/to/work:/work \
      public.ecr.aws/neuron/pytorch-inference-sglang-neuron:v0.1.0-neuron-py314-sdk-2.33.0-ubuntu26.04 \
      /bin/bash

    2. Launch the SGLang model server inside the container.
      SGLANG_PLATFORM=neuron \
      python -m sglang.launch_server \
      --model-path openai/gpt-oss-120b \
      --tp-size 8 \
      --ep-size 8 \
      --kv-cache-dtype fp8_e4m3 \
      --context-length 10240 \
      --chunked-prefill-size 8192 \
      --max-running-requests 64 \
      --max-total-tokens 655360 \
      --mem-fraction-static 0.8 \
      --host 127.0.0.1 \
      --port 30000

    3. Send a request to the model server.
      curl -s http://127.0.0.1:30000/v1/chat/completions \
      -H 'Content-Type: application/json' \
      -d '{
      "model": "openai/gpt-oss-120b",
      "messages": [
      {"role": "user", "content": "Explain why the sky appears blue."}
      ],
      "temperature": 0,
      "max_tokens": 128
      }'

    For additional information, please see the SGLang-Neuron getting started guide for setup instructions, and explore the repository documentation for supported models, features, and validated configurations.

    Conclusion

    SGLang-Neuron brings SGLang’s familiar serving workflow to AWS Trainium through native PyTorch. You can get started by launching the SGLang-Neuron container and following the quickstart to serve a supported model. Try it with your workloads, contribute through the project repository, and share feedback to help shape future model and feature support.


    About the authors

    Alex Nails

    Alex Nails

    Alex is a Member of Technical Staff at RadixArk. He leads MultiHardware and is a core developer of SGLang.

    Yihao Wang

    Yihao Wang

    Yihao is a Member of Technical Staff at RadixArk. He works on both multi-modal/diffusion models and multi-hardware.

    Lingyan Hao

    Lingyan Hao

    Lingyan is a Product Manager at RadixArk. She works on SGLang adoption and multi-hardware enablement.

    Srecharan Selvam

    Srecharan Selvam

    Srecharan is a software engineer working on AI Inference technology at Annapurna Labs, Amazon.

    Zeyu Wang

    Zeyu Wang

    Zeyu is a software engineer working on AI Inference technology at Annapurna Labs, Amazon.

    Vinesh Ravuri

    Vinesh Ravuri

    Vinesh is a software engineer working on AI Inference technology at Annapurna Labs, Amazon.

    Yuchen Jiang

    Yuchen Jiang

    Yuchen is a software engineer working on AI Inference technology at Annapurna Labs, Amazon.

    Pinak Panigrahi

    Pinak Panigrahi

    Pinak works on performance optimization of AI models on AWS Trainium at Annapurna Labs, Amazon.

    Chi Wang

    Chi Wang

    Chi is a Software Development Manager working on AI Inference technology at Annapurna Labs, Amazon.

    AWS Deploy frontier Models SGLangNeuron Trainium
    Share. Facebook Twitter Pinterest LinkedIn Tumblr Email
    admin
    • Website

    Related Posts

    How Natera designed an agentic AI system for lab ops with Amazon Bedrock AgentCore

    November 12, 2026

    Four Amazon Bedrock inference choices that affect cost

    November 12, 2026

    The Hallucinations Leaderboard, an Open Effort to Measure Hallucinations in Large Language Models

    November 12, 2026
    Leave A Reply Cancel Reply

    Top Posts

    NVIDIA Is Investigating Reports That CEO Jensen Huang Was The Target Of Chinese Spy Efforts

    November 8, 202619 Views

    ADIndex: Layer-Adaptive Sparse Attention Indexing via Group-Level Distillation

    November 11, 20265 Views

    Anthropic releases new Mythos and Fable models amid RSI concerns

    November 9, 20265 Views

    Anthropic says AI is eroding Nvidia’s CUDA lead, cutting an AMD chip switch from months to three days

    November 11, 20264 Views
    Don't Miss
    AI Tools & Software

    Accelerating SD Turbo and SDXL Turbo Inference with ONNX Runtime and Olive

    By adminNovember 12, 20260

    Introduction SD Turbo and SDXL Turbo are two fast generative text-to-image models capable of generating…

    ‘It’s a mistake for Nvidia to let Jensen resign’: reactions from tech leaders on Jensen Huang’s resignation

    November 12, 2026

    Deploy frontier AI models on AWS Trainium with SGLang-Neuron

    November 12, 2026

    Preference Tuning LLMs with Direct Preference Optimization Methods

    November 12, 2026
    About Us

    Welcome to TechWave Dispatch

    At TechWave Dispatch, we bring you the latest news, insights, and developments from the ever-evolving world of technology. Our mission is to keep readers informed about the innovations shaping our digital future.

    From artificial intelligence and machine learning to cybersecurity, robotics, smart devices, and groundbreaking technologies, we cover the topics that matter in today's fast-moving tech landscape.

    Our Picks

    Accelerating SD Turbo and SDXL Turbo Inference with ONNX Runtime and Olive

    November 12, 2026

    ‘It’s a mistake for Nvidia to let Jensen resign’: reactions from tech leaders on Jensen Huang’s resignation

    November 12, 2026

    Deploy frontier AI models on AWS Trainium with SGLang-Neuron

    November 12, 2026
    Most Popular

    Who Controls Scientific Discovery? – O’Reilly

    November 6, 20260 Views

    After blocking Muse, Amazon now lets users text Alexa to help them shop

    November 6, 20260 Views

    A controlled world for robot learning and evaluation

    November 6, 20260 Views
    Facebook X (Twitter) Instagram Pinterest
    • Terms and Conditions
    • Privacy Policy
    • Contact Us
    • About Us
    © 2026 TechWave Dispatch. All Rights Reserved.

    Type above and press Enter to search. Press Esc to cancel.