

Hugging Face provides a Hub platform that allows you to upload, share, and deploy your models with ease. It saves developers the time and computational resources required to train models from scratch. However, deploying models in a real-world production environment or in a cloud-native way can still present challenges.
This is where BentoML comes into the picture. BentoML is an open-source platform for machine learning model serving and deployment. It is a unified framework for building, shipping, and scaling production-ready AI applications incorporating traditional, pre-trained, and generative models as well as Large Language Models. Here is how you use the BentoML framework from a high-level perspective:
- Define a model: Before you can use BentoML, you need a machine learning model (or multiple models). This model can be trained using a machine learning library such as TensorFlow and PyTorch.
- Save the model: Once you have a trained model, save it to the BentoML local Model Store, which is used for managing all your trained models locally as well as accessing them for serving.
- Create a BentoML Service: You create a
service.pyfile to wrap the model and define the serving logic. It specifies Runners for models to run model inference at scale and exposes APIs to define how to process inputs and outputs. - Build a Bento: By creating a configuration YAML file, you package all the models and the Service into a Bento, a deployable artifact containing all the code and dependencies.
- Deploy the Bento: Once the Bento is ready, you can containerize the Bento to create a Docker image and run it on Kubernetes. Alternatively, deploy the Bento directly to Yatai, an open-source, end-to-end solution for automating and running machine learning deployments on Kubernetes at scale.
In this blog post, we will demonstrate how to integrate DeepFloyd IF with BentoML by following the above workflow.
Table of contents
A brief introduction to DeepFloyd IF
DeepFloyd IF is a state-of-the-art, open-source text-to-image model. It stands apart from latent diffusion models like Stable Diffusion due to its distinct operational strategy and architecture.
DeepFloyd IF delivers a high degree of photorealism and sophisticated language understanding. Unlike Stable Diffusion, DeepFloyd IF works directly in pixel space, leveraging a modular structure that encompasses a frozen text encoder and three cascaded pixel diffusion modules. Each module plays a unique role in the process: Stage 1 is responsible for the creation of a base 64×64 px image, which is then progressively upscaled to 1024×1024 px across Stage 2 and Stage 3. Another critical aspect of DeepFloyd IF’s uniqueness is its integration of a Large Language Model (T5-XXL-1.1) to encode prompts, which offers superior understanding of complex prompts. For more information, see this Stability AI blog post about DeepFloyd IF.
To make sure your DeepFloyd IF application runs in high performance in production, you may want to allocate and manage your resources wisely. In this respect, BentoML allows you to scale the Runners independently for each Stage. For example, you can use more Pods for your Stage 1 Runners or allocate more powerful GPU servers to them.
Preparing the environment
This GitHub repository stores all necessary files for this project. To run this project locally, make sure you have the following:
- Python 3.8+
pipinstalled- At least 2x16GB VRAM GPU or 1×40 VRAM GPU. For this project, we used a machine of type
n1-standard-16from Google Cloud plus 64 GB of RAM and 2 NVIDIA T4 GPUs. Note that while it is possible to run IF on a single T4, it is not recommended for production-grade serving
Once the prerequisites are met, clone the project repository to your local machine and navigate to the target directory.
git clone https://github.com/bentoml/IF-multi-GPUs-demo.git
cd IF-multi-GPUs-demo
Before building the application, let’s briefly explore the key files within this directory:
import_models.py: Defines the models for each stage of theIFPipeline. You use this file to download all the models to your local machine so that you can package them into a single Bento.requirements.txt: Defines all the packages and dependencies required for this project.service.py: Defines a BentoML Service, which contains three Runners created using theto_runnermethod and exposes an API for generating images. The API takes a JSON object as input (i.e. prompts and negative prompts) and returns an image as output by using a sequence of models.start-server.py: Starts a BentoML HTTP server through the Service defined inservice.pyand creates a Gradio web interface for users to enter prompts to generate images.bentofile.yaml: Defines the metadata of the Bento to be built, including the Service, Python packages, and models.
We recommend you create a Virtual Environment for dependency isolation. For example, run the following command to activate myenv:
python -m venv venv
source venv/bin/activate
Install the required dependencies:
pip install -r requirements.txt
If you haven’t previously downloaded models from Hugging Face using the command line, you must log in first:
pip install -U huggingface_hub
huggingface-cli login
Downloading the model to the BentoML Model Store
As mentioned above, you need to download all the models used by each DeepFloyd IF stage. Once you have set up the environment, run the following command to download models to your local Model store. The process may take some time.
python import_models.py
Once the downloads are complete, view the models in the Model store.
$ bentoml models list

Tag                                                                 Module                Size       Creation Time
sd-upscaler:bb2ckpa3uoypynry                                        bentoml.diffusers     16.29 GiB  2023-07-06 10:15:53
if-stage2:v1.0                                                      bentoml.diffusers     13.63 GiB  2023-07-06 09:55:49
if-stage1:v1.0                                                      bentoml.diffusers     19.33 GiB  2023-07-06 09:37:59
Starting a BentoML Service
You can directly run the BentoML HTTP server with a web UI powered by Gradio using the start-server.py file, which is the entry point of this application. It provides various options for customizing the execution and managing GPU allocation among different Stages. You may use different commands depending on your GPU setup:
-
For a GPU with over 40GB VRAM, run all models on the same GPU.
python start-server.py -
For two Tesla T4 with 15GB VRAM each, assign the Stage 1 model to the first GPU, and the Stage 2 and Stage 3 models to the second GPU.
python start-server.py --stage1-gpu=0 --stage2-gpu=1 --stage3-gpu=1 -
For one Tesla T4 with 15GB VRAM and two additional GPUs with smaller VRAM size, assign the Stage 1 model to T4, and Stage 2 and Stage 3 models to the second and third GPUs respectively.
python start-server.py --stage1-gpu=0 --stage2-gpu=1 --stage3-gpu=2
To see all customizable options (like the server’s port), run:
python start-server.py --help
Testing the server
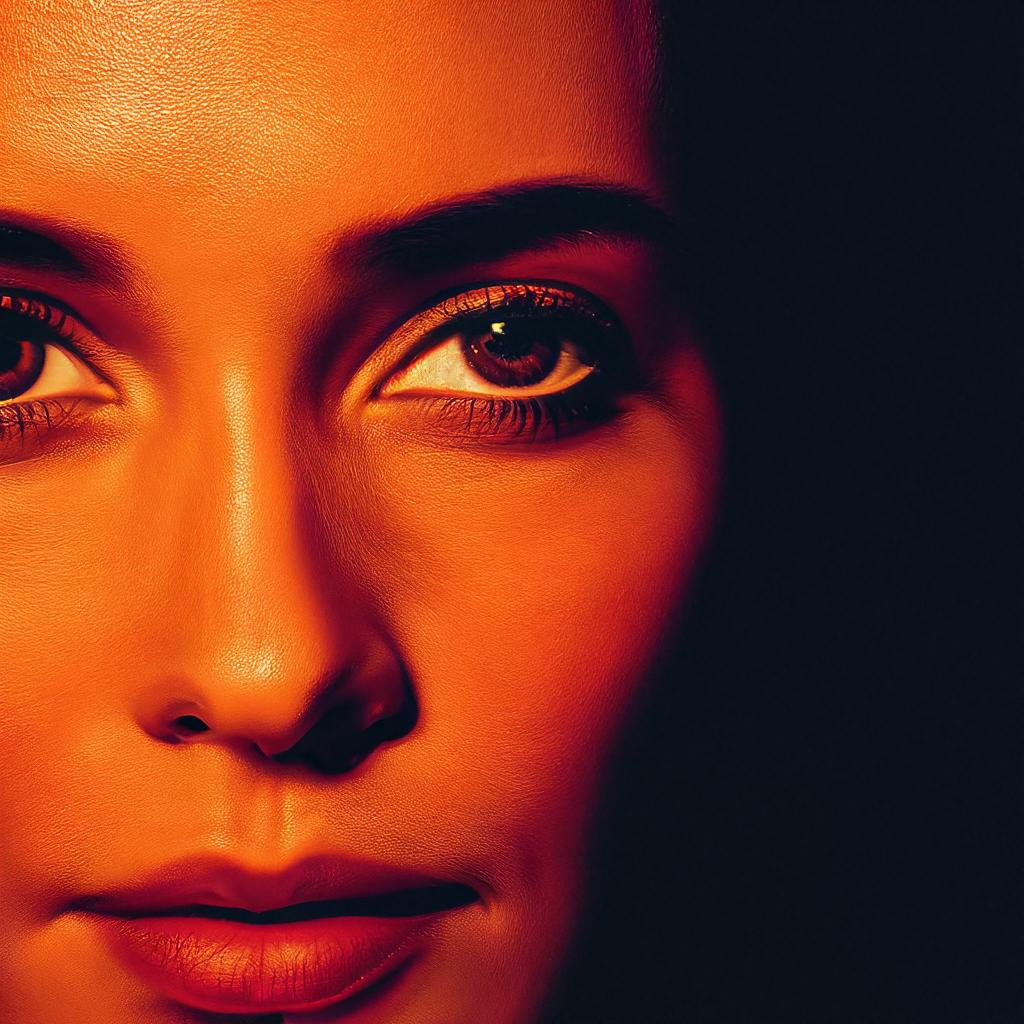
Once the server starts, you can visit the web UI at http://localhost:7860. The BentoML API endpoint is also accessible at http://localhost:3000. Here is an example of a prompt and a negative prompt.
Prompt:
orange and black, head shot of a woman standing under street lights, dark theme, Frank Miller, cinema, ultra realistic, ambiance, insanely detailed and intricate, hyper realistic, 8k resolution, photorealistic, highly textured, intricate details
Negative prompt:
tiling, poorly drawn hands, poorly drawn feet, poorly drawn face, out of frame, mutation, mutated, extra limbs, extra legs, extra arms, disfigured, deformed, cross-eye, body out of frame, blurry, bad art, bad anatomy, blurred, text, watermark, grainy
Result:
Building and serving a Bento
Now that you have successfully run DeepFloyd IF locally, you can package it into a Bento by running the following command in the project directory.
$ bentoml build

Converting 'IF-stage1' to lowercase: 'if-stage1'.
Converting 'IF-stage2' to lowercase: 'if-stage2'.
Converting DeepFloyd-IF to lowercase: deepfloyd-if.
Building BentoML service "deepfloyd-if:6ufnybq3vwszgnry" from build context "/Users/xxx/Documents/github/IF-multi-GPUs-demo".
Packing model "sd-upscaler:bb2ckpa3uoypynry"
Packing model "if-stage1:v1.0"
Packing model "if-stage2:v1.0"
Locking PyPI package versions.

██████╗░███████╗███╗░░██╗████████╗░█████╗░███╗░░░███╗██╗░░░░░
██╔══██╗██╔════╝████╗░██║╚══██╔══╝██╔══██╗████╗░████║██║░░░░░
██████╦╝█████╗░░██╔██╗██║░░░██║░░░██║░░██║██╔████╔██║██║░░░░░
██╔══██╗██╔══╝░░██║╚████║░░░██║░░░██║░░██║██║╚██╔╝██║██║░░░░░
██████╦╝███████╗██║░╚███║░░░██║░░░╚█████╔╝██║░╚═╝░██║███████╗
╚═════╝░╚══════╝╚═╝░░╚══╝░░░╚═╝░░░░╚════╝░╚═╝░░░░░╚═╝╚══════╝

Successfully built Bento(tag="deepfloyd-if:6ufnybq3vwszgnry").
View the Bento in the local Bento Store.
$ bentoml list

Tag                               Size       Creation Time
deepfloyd-if:6ufnybq3vwszgnry     49.25 GiB  2023-07-06 11:34:52
The Bento is now ready for serving in production.
bentoml serve deepfloyd-if:6ufnybq3vwszgnry
To deploy the Bento in a more cloud-native way, generate a Docker image by running the following command:
bentoml containerize deepfloyd-if:6ufnybq3vwszgnry
You can then deploy the model on Kubernetes.
What’s next?
BentoML provides a powerful and straightforward way to deploy Hugging Face models for production. With its support for a wide range of ML frameworks and easy-to-use APIs, you can ship your model to production in no time. Whether you’re working with the DeepFloyd IF model or any other model on the Hugging Face Model Hub, BentoML can help you bring your models to life.
Check out the following resources to see what you can build with BentoML and its ecosystem tools, and stay tuned for more information about BentoML.
