Close Menu
techwavedispatch.com

    Subscribe to Updates

    Get the latest creative news from FooBar about art, design and business.

    What's Hot

    Accelerating Stable Diffusion Inference on Intel CPUs

    November 14, 2026

    Outlook Went Down? Microsoft May Owe You Money

    November 14, 2026

    Ethical Openness at Hugging Face

    November 14, 2026
    Facebook X (Twitter) Instagram
    Trending
    • Accelerating Stable Diffusion Inference on Intel CPUs
    • Outlook Went Down? Microsoft May Owe You Money
    • Ethical Openness at Hugging Face
    • FAA Allows Flights To Resume After Hours-Long Ground Stop Across The US
    • A hands-on guide to train LLaMA with RLHF
    • Tuft & Needle Promo Codes: 20% Off | November 2026
    • unlock foundation models for enterprises
    • PlayStation Discount Code: 15% Off | November 2026
    Facebook X (Twitter) Instagram
    techwavedispatch.com
    Subscribe
    Saturday, November 14
    • Home
    • AI Tools & Software
    • Machine Learning
    • Generative AI
    • Robotics & Automation
    • Future Tech & Hardware
    • AI in Business
    • Ethics & Regulations
    • More
      • Gadgets & Smart Devices
      • Cybersecurity & AI
      • Tech Breakthroughs
    techwavedispatch.com
    Home»AI Tools & Software»Deploying the AI Comic Factory using the Inference API
    AI Tools & Software

    Deploying the AI Comic Factory using the Inference API

    adminBy adminNovember 13, 2026No Comments3 Mins Read
    Facebook Twitter Pinterest LinkedIn Tumblr Email
    Deploying the AI Comic Factory using the Inference API
    Share
    Facebook Twitter LinkedIn Pinterest Email

    We recently announced Inference for PROs, our new offering that makes larger models accessible to a broader audience. This opportunity opens up new possibilities for running end-user applications using Hugging Face as a platform.

    An example of such an application is the AI Comic Factory – a Space that has proved incredibly popular. Thousands of users have tried it to create their own AI comic panels, fostering its own community of regular users. They share their creations, with some even opening pull requests.

    In this tutorial, we’ll show you how to fork and configure the AI Comic Factory to avoid long wait times and deploy it to your own private space using the Inference API. It does not require strong technical skills, but some knowledge of APIs, environment variables and a general understanding of LLMs & Stable Diffusion are recommended.


    Getting started

    First, ensure that you sign up for a PRO Hugging Face account, as this will grant you access to the Llama-2 and SDXL models.


    How the AI Comic Factory works

    The AI Comic Factory is a bit different from other Spaces running on Hugging Face: it is a NextJS application, deployed using Docker, and is based on a client-server approach, requiring two APIs to work:

    • a Language Model API (Currently Llama-2)
    • a Stable Diffusion API (currently SDXL 1.0)


    Duplicating the Space

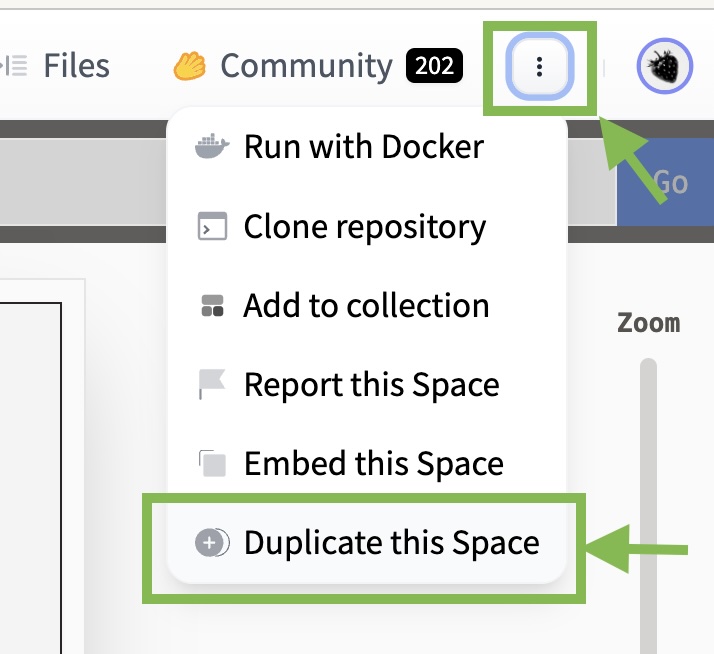
    To duplicate the AI Comic Factory, go to the Space and click on “Duplicate”:
    duplicate-space-1.jpg

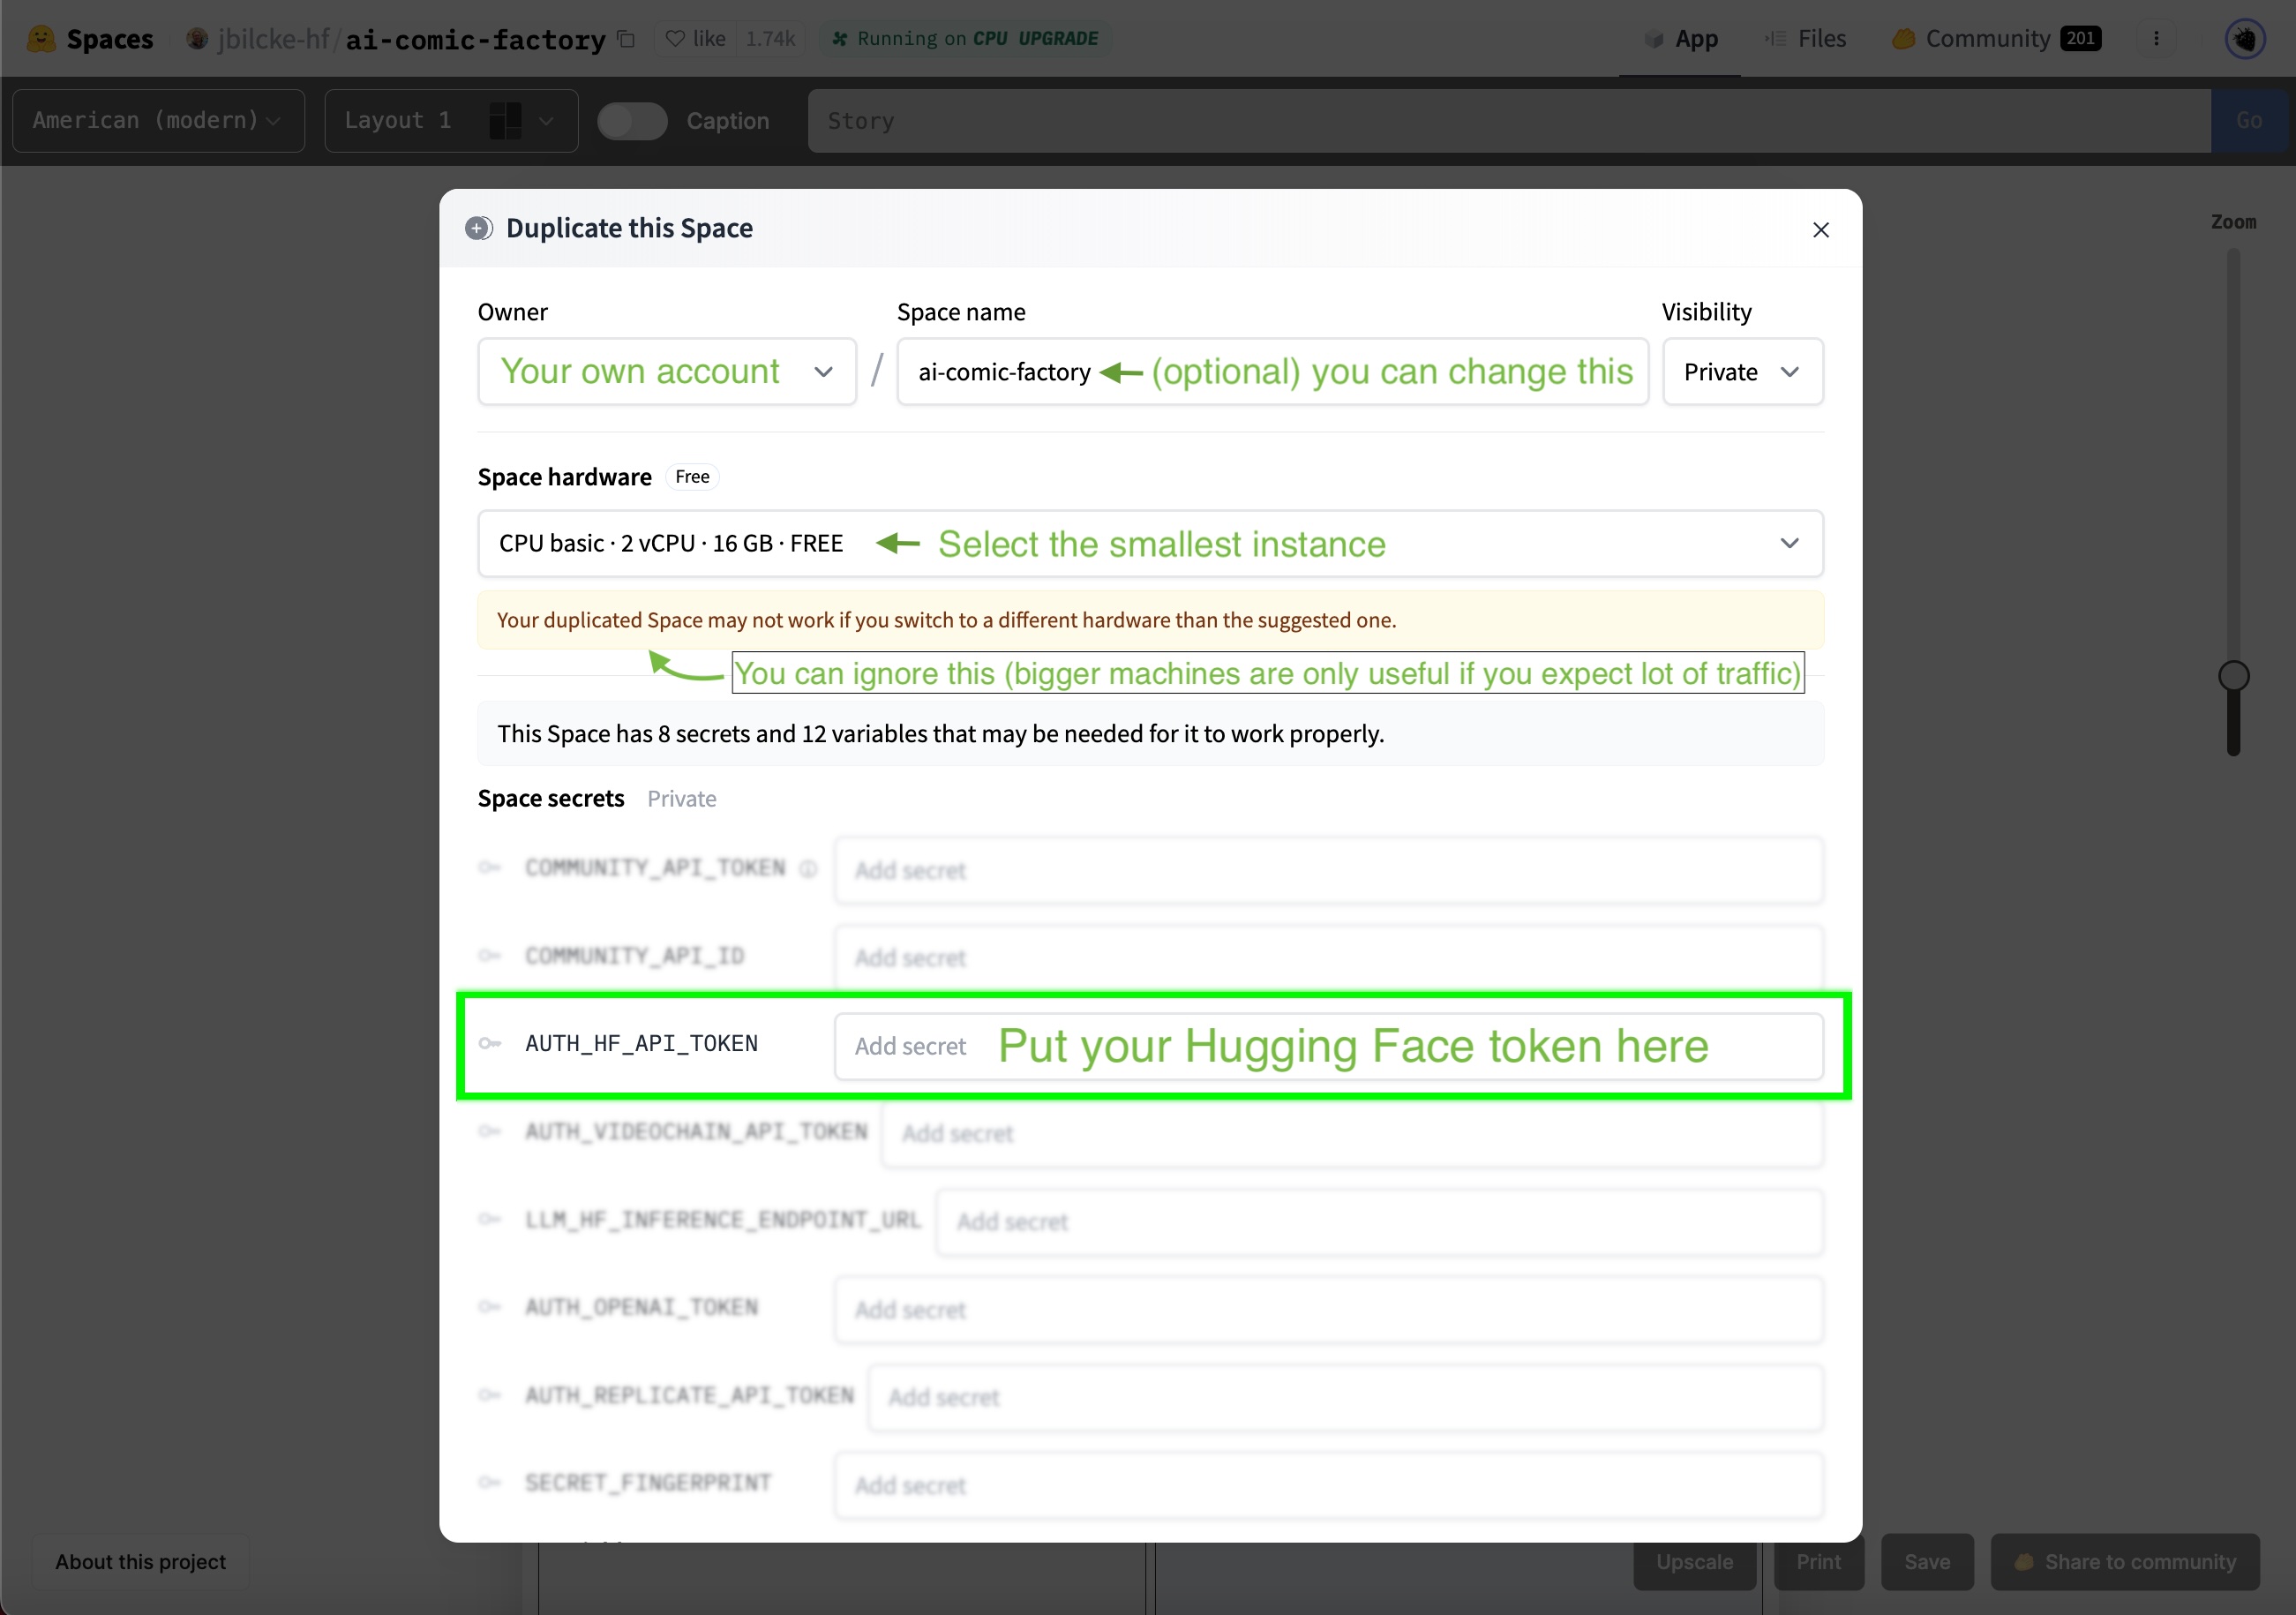
    You’ll observe that the Space owner, name, and visibility are already filled in for you, so you can leave those values as is.

    Your copy of the Space will run inside a Docker container that doesn’t require many resources, so you can use the smallest instance. The official AI Comic Factory Space utilizes a bigger CPU instance, as it caters to a large user base.

    To operate the AI Comic Factory under your account, you need to configure your Hugging Face token:
    duplicate-space-2.jpg


    Selecting the LLM and SD engines

    The AI Comic Factory supports various backend engines, which can be configured using two environment variables:

    • LLM_ENGINE to configure the language model (possible values are INFERENCE_API, INFERENCE_ENDPOINT, OPENAI)
    • RENDERING_ENGINE to configure the image generation engine (possible values are INFERENCE_API, INFERENCE_ENDPOINT, REPLICATE, VIDEOCHAIN).

    We’ll focus on making the AI Comic Factory work on the Inference API, so they both need to be set to INFERENCE_API:

    duplicate-space-3.jpg

    You can find more information about alternative engines and vendors in the project’s README and the .env config file.


    Configuring the models

    The AI Comic Factory comes with the following models pre-configured:

    • LLM_HF_INFERENCE_API_MODEL: default value is meta-llama/Llama-2-70b-chat-hf
    • RENDERING_HF_RENDERING_INFERENCE_API_MODEL: default value is stabilityai/stable-diffusion-xl-base-1.0

    Your PRO Hugging Face account already gives you access to those models, so you don’t have anything to do or change.


    Going further

    Support for the Inference API in the AI Comic Factory is in its early stages, and some features, such as using the refiner step for SDXL or implementing upscaling, haven’t been ported over yet.

    Nonetheless, we hope this information will enable you to start forking and tweaking the AI Comic Factory to suit your requirements.

    Feel free to experiment and try other models from the community, and happy hacking!

    API Comic Deploying Factory Inference
    Share. Facebook Twitter Pinterest LinkedIn Tumblr Email
    admin
    • Website

    Related Posts

    Accelerating Stable Diffusion Inference on Intel CPUs

    November 14, 2026

    Ethical Openness at Hugging Face

    November 14, 2026

    A hands-on guide to train LLaMA with RLHF

    November 14, 2026
    Leave A Reply Cancel Reply

    Top Posts

    NVIDIA Is Investigating Reports That CEO Jensen Huang Was The Target Of Chinese Spy Efforts

    November 8, 202619 Views

    ADIndex: Layer-Adaptive Sparse Attention Indexing via Group-Level Distillation

    November 11, 20265 Views

    Anthropic releases new Mythos and Fable models amid RSI concerns

    November 9, 20265 Views

    One Policy for 100 Household Tasks: Our Solution for the 2026 BEHAVIOR Challenge

    November 11, 20264 Views
    Don't Miss
    AI Tools & Software

    Accelerating Stable Diffusion Inference on Intel CPUs

    By adminNovember 14, 20260

    Recently, we introduced the latest generation of Intel Xeon CPUs (code name Sapphire Rapids), its…

    Outlook Went Down? Microsoft May Owe You Money

    November 14, 2026

    Ethical Openness at Hugging Face

    November 14, 2026

    FAA Allows Flights To Resume After Hours-Long Ground Stop Across The US

    November 14, 2026
    About Us

    Welcome to TechWave Dispatch

    At TechWave Dispatch, we bring you the latest news, insights, and developments from the ever-evolving world of technology. Our mission is to keep readers informed about the innovations shaping our digital future.

    From artificial intelligence and machine learning to cybersecurity, robotics, smart devices, and groundbreaking technologies, we cover the topics that matter in today's fast-moving tech landscape.

    Our Picks

    Accelerating Stable Diffusion Inference on Intel CPUs

    November 14, 2026

    Outlook Went Down? Microsoft May Owe You Money

    November 14, 2026

    Ethical Openness at Hugging Face

    November 14, 2026
    Most Popular

    Who Controls Scientific Discovery? – O’Reilly

    November 6, 20260 Views

    After blocking Muse, Amazon now lets users text Alexa to help them shop

    November 6, 20260 Views

    A controlled world for robot learning and evaluation

    November 6, 20260 Views
    Facebook X (Twitter) Instagram Pinterest
    • Terms and Conditions
    • Privacy Policy
    • Contact Us
    • About Us
    © 2026 TechWave Dispatch. All Rights Reserved.

    Type above and press Enter to search. Press Esc to cancel.