Close Menu
techwavedispatch.com

    Subscribe to Updates

    Get the latest creative news from FooBar about art, design and business.

    What's Hot

    Here’s How Google Says It’s Making Its Smart Glasses More Private

    November 12, 2026

    Cyberattack on Fireworks AI allowed hackers to access Notion customers’ chat transcripts

    November 12, 2026

    Text-Generation Pipeline on Intel® Gaudi® 2 AI Accelerator

    November 12, 2026
    Facebook X (Twitter) Instagram
    Trending
    • Here’s How Google Says It’s Making Its Smart Glasses More Private
    • Cyberattack on Fireworks AI allowed hackers to access Notion customers’ chat transcripts
    • Text-Generation Pipeline on Intel® Gaudi® 2 AI Accelerator
    • Still Great, But Drastically More Expensive
    • Google pushes privacy angle as Gemini-powered smartglasses debut starting at $395
    • Enabling communities to collectively build better datasets together using Argilla and Hugging Face Spaces
    • I reviewed the Apple HomeView, ask me anything
    • The Definitive Fine-Tuning Guide for 3D Generation Models
    Facebook X (Twitter) Instagram
    techwavedispatch.com
    Subscribe
    Thursday, November 12
    • Home
    • AI Tools & Software
    • Machine Learning
    • Generative AI
    • Robotics & Automation
    • Future Tech & Hardware
    • AI in Business
    • Ethics & Regulations
    • More
      • Gadgets & Smart Devices
      • Cybersecurity & AI
      • Tech Breakthroughs
    techwavedispatch.com
    Home»AI Tools & Software»Enabling communities to collectively build better datasets together using Argilla and Hugging Face Spaces
    AI Tools & Software

    Enabling communities to collectively build better datasets together using Argilla and Hugging Face Spaces

    adminBy adminNovember 12, 2026No Comments4 Mins Read
    Facebook Twitter Pinterest LinkedIn Tumblr Email
    Enabling communities to collectively build better datasets together using Argilla and Hugging Face Spaces
    Share
    Facebook Twitter LinkedIn Pinterest Email

    Recently, Argilla and Hugging Face launched Data is Better Together, an experiment to collectively build a preference dataset of prompt rankings. In a few days, we had:

    • 350 community contributors labeling data
    • Over 11,000 prompt ratings

    See the progress dashboard for the latest stats!

    This resulted in the release of 10k_prompts_ranked, a dataset consisting of 10,000 prompts with user ratings for the quality of the prompt. We want to enable many more projects like this!

    In this post, we’ll discuss why we think it’s essential for the community to collaborate on building datasets and share an invitation to join the first cohort of communities Argilla and Hugging Face will support to develop better datasets together!


    Data remains essential for better models

    Data continues to be essential for better models: We see continued evidence from published research, open-source experiments, and from the open-source community that better data can lead to better models.
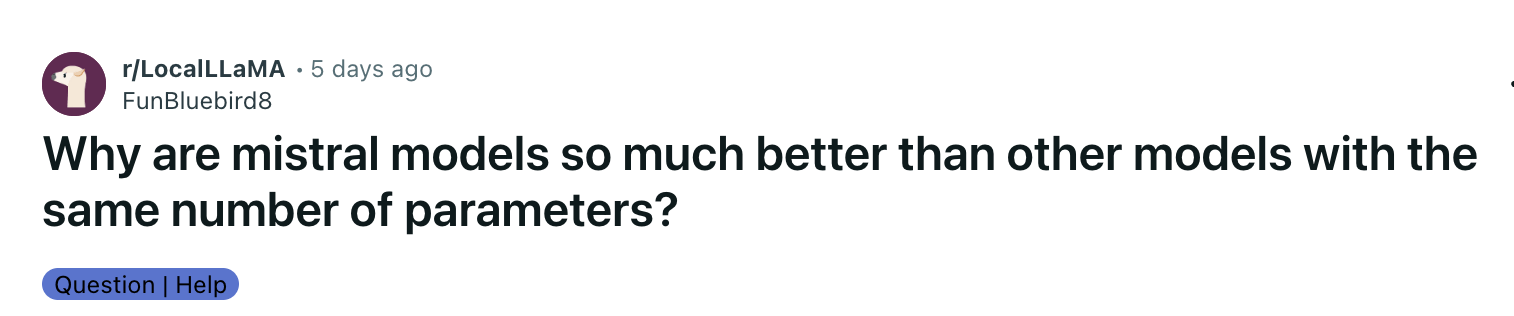
    Screenshot of datasets in the Hugging Face Hub
    The question.

    Screenshot of datasets in the Hugging Face Hub
    A frequent answer.


    Why build datasets collectively?

    Data is vital for machine learning, but many languages, domains, and tasks still lack high-quality datasets for training, evaluating, and benchmarking — the community already shares thousands of models, datasets, and demos daily via the Hugging Face Hub. As a result of collaboration, the open-access AI community has created amazing things. Enabling the community to build datasets collectively will unlock unique opportunities for building the next generation of datasets to build the next generation of models.

    Empowering the community to build and improve datasets collectively will allow people to:

    • Contribute to the development of Open Source ML with no ML or programming skills required.
    • Create chat datasets for a particular language.
    • Develop benchmark datasets for a specific domain.
    • Create preference datasets from a diverse range of participants.
    • Build datasets for a particular task.
    • Build completely new types of datasets collectively as a community.

    Importantly we believe that building datasets collectively will allow the community to build better datasets abd allow people who don’t know how to code to contribute to the development of AI.


    Making it easy for people to contribute

    One of the challenges to many previous efforts to build AI datasets collectively was setting up an efficient annotation task. Argilla is an open-source tool that can help create datasets for LLMs and smaller specialised task-specific models. Hugging Face Spaces is a platform for building and hosting machine learning demos and applications. Recently, Argilla added support for authentication via a Hugging Face account for Argilla instances hosted on Spaces. This means it now takes seconds for users to start contributing to an annotation task.


    Now that we have stress-tested this new workflow when creating the 10k_prompts_ranked, dataset, we want to support the community in launching new collective dataset efforts.


    Join our first cohort of communities who want to build better datasets together!

    We’re very excited about the possibilities unlocked by this new, simple flow for hosting annotation tasks. To support the community in building better datasets, Hugging Face and Argilla invite interested people and communities to join our initial cohort of community dataset builders.

    People joining this cohort will:

    • Be supported in creating an Argilla Space with Hugging Face authentication. Hugging Face will grant free persistent storage and improved CPU spaces for participants.
    • Have their comms and promotion advertising the initiative amplified by Argilla and Hugging Face.
    • Be invited to join a cohort community channel

    Our goal is to support the community in building better datasets together. We are open to many ideas and want to support the community as far as possible in building better datasets together.


    What types of projects are we looking for?

    We are open to supporting many types of projects, especially those of existing open-source communities. We are particularly interested in projects focusing on building datasets for languages, domains, and tasks that are currently underrepresented in the open-source community. Our only current limitation is that we’re primarily focused on text-based datasets. If you have a very cool idea for multimodal datasets, we’d love to hear from you, but we may not be able to support you in this first cohort.

    Tasks can either be fully open or open to members of a particular Hugging Face Hub organization.

    If you want to be part of the first cohort, please join us in the #data-is-better-together channel in the Hugging Face Discord and let us know what you want to build together!

    We are looking forward to building better datasets together with you!

    Argilla build collectively communities datasets Enabling Face Hugging Spaces
    Share. Facebook Twitter Pinterest LinkedIn Tumblr Email
    admin
    • Website

    Related Posts

    Text-Generation Pipeline on Intel® Gaudi® 2 AI Accelerator

    November 12, 2026

    The Definitive Fine-Tuning Guide for 3D Generation Models

    November 12, 2026

    Jensen Huang resigns as Nvidia CEO after espionage scandal wipes out $1.4 trillion in market value

    November 12, 2026
    Leave A Reply Cancel Reply

    Top Posts

    NVIDIA Is Investigating Reports That CEO Jensen Huang Was The Target Of Chinese Spy Efforts

    November 8, 202619 Views

    Anthropic releases new Mythos and Fable models amid RSI concerns

    November 9, 20265 Views

    Anthropic says AI is eroding Nvidia’s CUDA lead, cutting an AMD chip switch from months to three days

    November 11, 20264 Views

    ADIndex: Layer-Adaptive Sparse Attention Indexing via Group-Level Distillation

    November 11, 20264 Views
    Don't Miss
    Gadgets & Smart Devices

    Here’s How Google Says It’s Making Its Smart Glasses More Private

    By adminNovember 12, 20260

    Payne hopes these policies and actions will encourage other companies to follow suit. “We hope…

    Cyberattack on Fireworks AI allowed hackers to access Notion customers’ chat transcripts

    November 12, 2026

    Text-Generation Pipeline on Intel® Gaudi® 2 AI Accelerator

    November 12, 2026

    Still Great, But Drastically More Expensive

    November 12, 2026
    About Us

    Welcome to TechWave Dispatch

    At TechWave Dispatch, we bring you the latest news, insights, and developments from the ever-evolving world of technology. Our mission is to keep readers informed about the innovations shaping our digital future.

    From artificial intelligence and machine learning to cybersecurity, robotics, smart devices, and groundbreaking technologies, we cover the topics that matter in today's fast-moving tech landscape.

    Our Picks

    Here’s How Google Says It’s Making Its Smart Glasses More Private

    November 12, 2026

    Cyberattack on Fireworks AI allowed hackers to access Notion customers’ chat transcripts

    November 12, 2026

    Text-Generation Pipeline on Intel® Gaudi® 2 AI Accelerator

    November 12, 2026
    Most Popular

    Who Controls Scientific Discovery? – O’Reilly

    November 6, 20260 Views

    After blocking Muse, Amazon now lets users text Alexa to help them shop

    November 6, 20260 Views

    A controlled world for robot learning and evaluation

    November 6, 20260 Views
    Facebook X (Twitter) Instagram Pinterest
    • Terms and Conditions
    • Privacy Policy
    • Contact Us
    • About Us
    © 2026 TechWave Dispatch. All Rights Reserved.

    Type above and press Enter to search. Press Esc to cancel.