

We recently announced that Gemma, the open weights language model from Google Deepmind, is available for the broader open-source community via Hugging Face. It’s available in 2 billion and 7 billion parameter sizes with pretrained and instruction-tuned flavors. It’s available on Hugging Face, supported in TGI, and easily accessible for deployment and fine-tuning in the Vertex Model Garden and Google Kubernetes Engine.
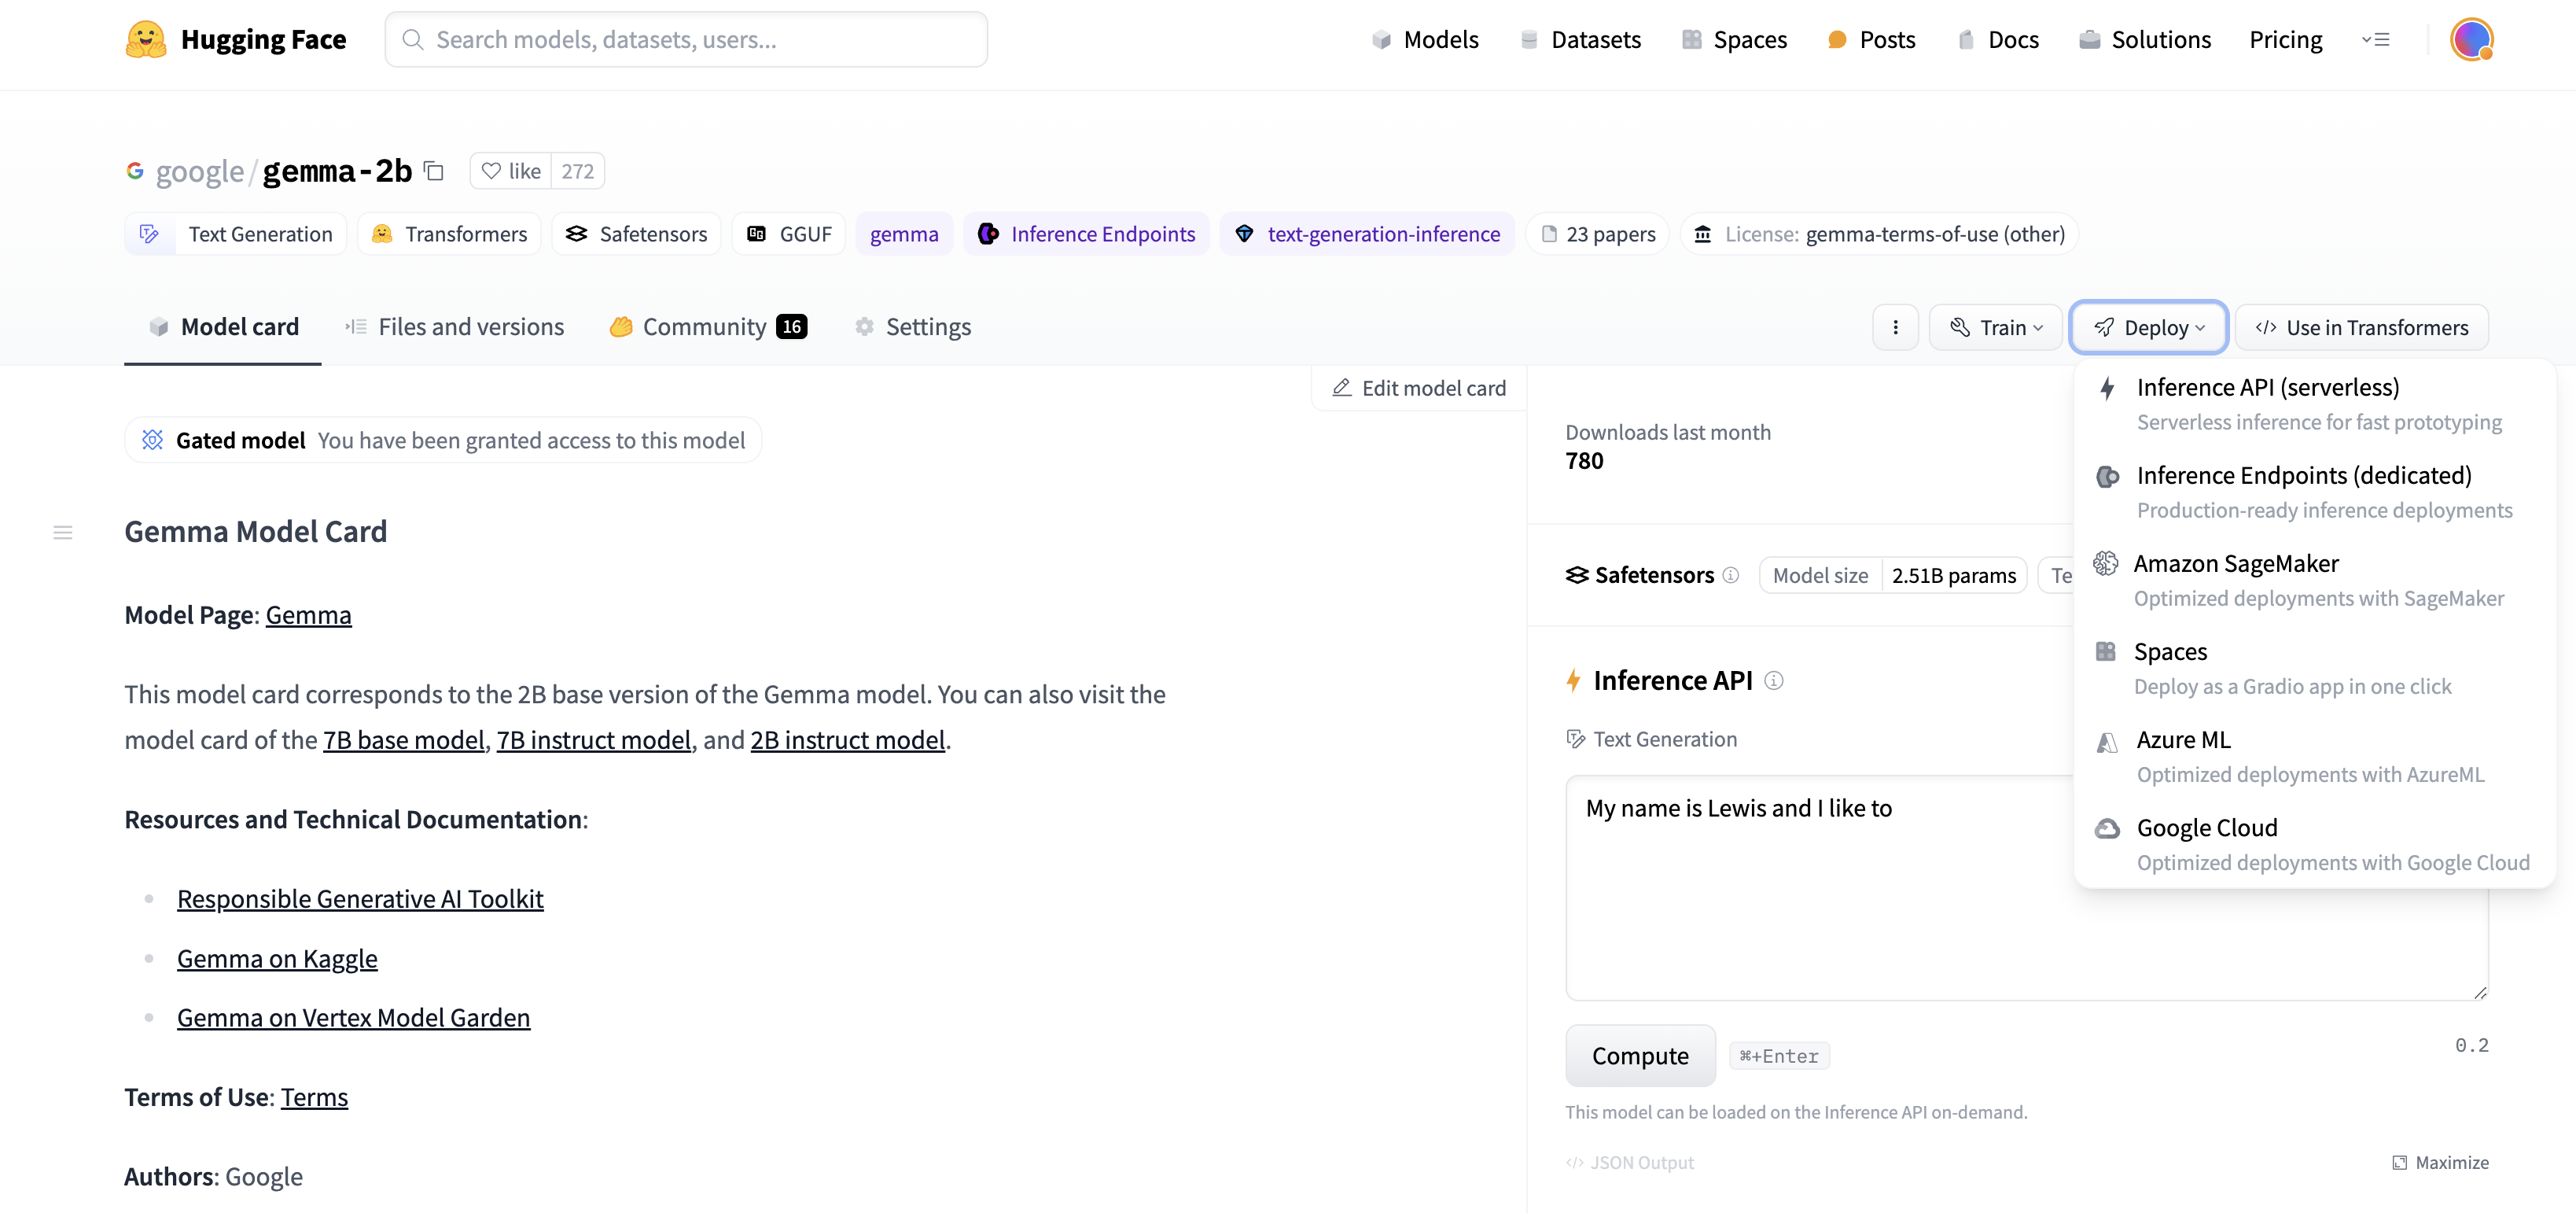
The Gemma family of models also happens to be well suited for prototyping and experimentation using the free GPU resource available via Colab. In this post we will briefly review how you can do Parameter Efficient FineTuning (PEFT) for Gemma models, using the Hugging Face Transformers and PEFT libraries on GPUs and Cloud TPUs for anyone who wants to fine-tune Gemma models on their own dataset.
Why PEFT?
The default (full weight) training for language models, even for modest sizes, tends to be memory and compute-intensive. On one hand, it can be prohibitive for users relying on openly available compute platforms for learning and experimentation, such as Colab or Kaggle. On the other hand, and even for enterprise users, the cost of adapting these models for different domains is an important metric to optimize. PEFT, or parameter-efficient fine tuning, is a popular technique to accomplish this at low cost.
PyTorch on GPU and TPU
Gemma models in Hugging Face transformers are optimized for both PyTorch and PyTorch/XLA. This enables both TPU and GPU users to access and experiment with Gemma models as needed. Together with the Gemma release, we have also improved the FSDP experience for PyTorch/XLA in Hugging Face. This FSDP via SPMD integration also allows other Hugging Face models to take advantage of TPU acceleration via PyTorch/XLA. In this post, we will focus on PEFT, and more specifically on Low-Rank Adaptation (LoRA), for Gemma models. For a more comprehensive set of LoRA techniques, we encourage readers to review the Scaling Down to Scale Up, from Lialin et al. and this excellent post post by Belkada et al.
Low-Rank Adaptation for Large Language Models
Low-Rank Adaptation (LoRA) is one of the parameter-efficient fine-tuning techniques for large language models (LLMs). It addresses just a fraction of the total number of model parameters to be fine-tuned, by freezing the original model and only training adapter layers that are decomposed into low-rank matrices. The PEFT library provides an easy abstraction that allows users to select the model layers where adapter weights should be applied.
from peft import LoraConfig

lora_config = LoraConfig(
    r=8,
    target_modules=["q_proj", "o_proj", "k_proj", "v_proj", "gate_proj", "up_proj", "down_proj"],
    task_type="CAUSAL_LM",
)
In this snippet, we refer to all nn.Linear layers as the target layers to be adapted.
In the following example, we will leverage QLoRA, from Dettmers et al., in order to quantize the base model in 4-bit precision for a more memory efficient fine-tuning protocol. The model can be loaded with QLoRA by first installing the bitsandbytes library on your environment, and then passing a BitsAndBytesConfig object to from_pretrained when loading the model.
Before we begin
In order to access Gemma model artifacts, users are required to accept the consent form.
Now let’s get started with the implementation.
Learning to quote
Assuming that you have submitted the consent form, you can access the model artifacts from the Hugging Face Hub.
We start by downloading the model and the tokenizer. We also include a BitsAndBytesConfig for weight only quantization.
import torch
import os
from transformers import AutoTokenizer, AutoModelForCausalLM, BitsAndBytesConfig

model_id = "google/gemma-2b"
bnb_config = BitsAndBytesConfig(
    load_in_4bit=True,
    bnb_4bit_quant_type="nf4",
    bnb_4bit_compute_dtype=torch.bfloat16
)

tokenizer = AutoTokenizer.from_pretrained(model_id, token=os.environ['HF_TOKEN'])
model = AutoModelForCausalLM.from_pretrained(model_id, quantization_config=bnb_config, device_map={"":0}, token=os.environ['HF_TOKEN'])
Now we test the model before starting the finetuning, using a famous quote:
text = "Quote: Imagination is more"
device = "cuda:0"
inputs = tokenizer(text, return_tensors="pt").to(device)

outputs = model.generate(**inputs, max_new_tokens=20)
print(tokenizer.decode(outputs[0], skip_special_tokens=True))
The model does a reasonable completion with some extra tokens:
Quote: Imagination is more important than knowledge. Knowledge is limited. Imagination encircles the world.

-Albert Einstein

I
But this is not exactly the format we would love the answer to be. Let’s see if we can use fine-tuning to teach the model to generate the answer in the following format.
Quote: Imagination is more important than knowledge. Knowledge is limited. Imagination encircles the world.

Author: Albert Einstein
To begin with, let’s select an English quotes dataset Abirate/english_quotes.
from datasets import load_dataset

data = load_dataset("Abirate/english_quotes")
data = data.map(lambda samples: tokenizer(samples["quote"]), batched=True)
Now let’s finetune this model using the LoRA config stated above:
import transformers
from trl import SFTTrainer

def formatting_func(example):
    text = f"Quote: {example['quote'][0]}\nAuthor: {example['author'][0]}"
    return [text]

trainer = SFTTrainer(
    model=model,
    train_dataset=data["train"],
    args=transformers.TrainingArguments(
        per_device_train_batch_size=1,
        gradient_accumulation_steps=4,
        warmup_steps=2,
        max_steps=10,
        learning_rate=2e-4,
        fp16=True,
        logging_steps=1,
        output_dir="outputs",
        optim="paged_adamw_8bit"
    ),
    peft_config=lora_config,
    formatting_func=formatting_func,
)
trainer.train()
Finally, we are ready to test the model once more with the same prompt we have used earlier:
text = "Quote: Imagination is"
device = "cuda:0"
inputs = tokenizer(text, return_tensors="pt").to(device)

outputs = model.generate(**inputs, max_new_tokens=20)
print(tokenizer.decode(outputs[0], skip_special_tokens=True))
This time we get the response in the format we like:
Quote: Imagination is more important than knowledge. Knowledge is limited. Imagination encircles the world.
Author: Albert Einstein
Accelerate with FSDP via SPMD on TPU
As mentioned earlier, Hugging Face transformers now supports PyTorch/XLA’s latest FSDP implementation. This can greatly accelerate the fine-tuning speed. To enable that, one just needs to add a FSDP config to the transformers.Trainer:
from transformers import DataCollatorForLanguageModeling, Trainer, TrainingArguments


fsdp_config = {
    "fsdp_transformer_layer_cls_to_wrap": ["GemmaDecoderLayer"],
    "xla": True,
    "xla_fsdp_v2": True,
    "xla_fsdp_grad_ckpt": True
}


trainer = Trainer(
    model=model,
    train_dataset=data,
    args=TrainingArguments(
        per_device_train_batch_size=64,
        num_train_epochs=100,
        max_steps=-1,
        output_dir="./output",
        optim="adafactor",
        logging_steps=1,
        dataloader_drop_last = True,
        fsdp="full_shard",
        fsdp_config=fsdp_config,
    ),
    data_collator=DataCollatorForLanguageModeling(tokenizer, mlm=False),
)
trainer.train()
Next Steps
We walked through this simple example adapted from the source notebook to illustrate the LoRA finetuning method applied to Gemma models. The full colab for GPU can be found here, and the full script for TPU can be found here. We are excited about the endless possibilities for research and learning thanks to this recent addition to our open source ecosystem. We encourage users to also visit the Gemma documentation, as well as our launch blog for more examples to train, finetune and deploy Gemma models.
