


Instruction tuning is an approach of fine-tuning that gives large language models (LLMs) the capability to follow natural and human-written instructions. However, for programming tasks, most models are tuned on either human-written instructions (which are very expensive) or instructions generated by huge and proprietary LLMs (which may not be permitted). We introduce StarCoder2-15B-Instruct-v0.1, the very first entirely self-aligned code LLM trained with a fully permissive and transparent pipeline. Our open-source pipeline uses StarCoder2-15B to generate thousands of instruction-response pairs, which are then used to fine-tune StarCoder-15B itself without any human annotations or distilled data from huge and proprietary LLMs.
StarCoder2-15B-Instruct achieves a 72.6 HumanEval score, even surpassing the 72.0 score of CodeLlama-70B-Instruct! Further evaluation on LiveCodeBench shows that the self-aligned model is even better than the same model trained on data distilled from GPT-4, implying that an LLM could learn more effectively from data within its own distribution than a shifted distribution from a teacher LLM.
Method
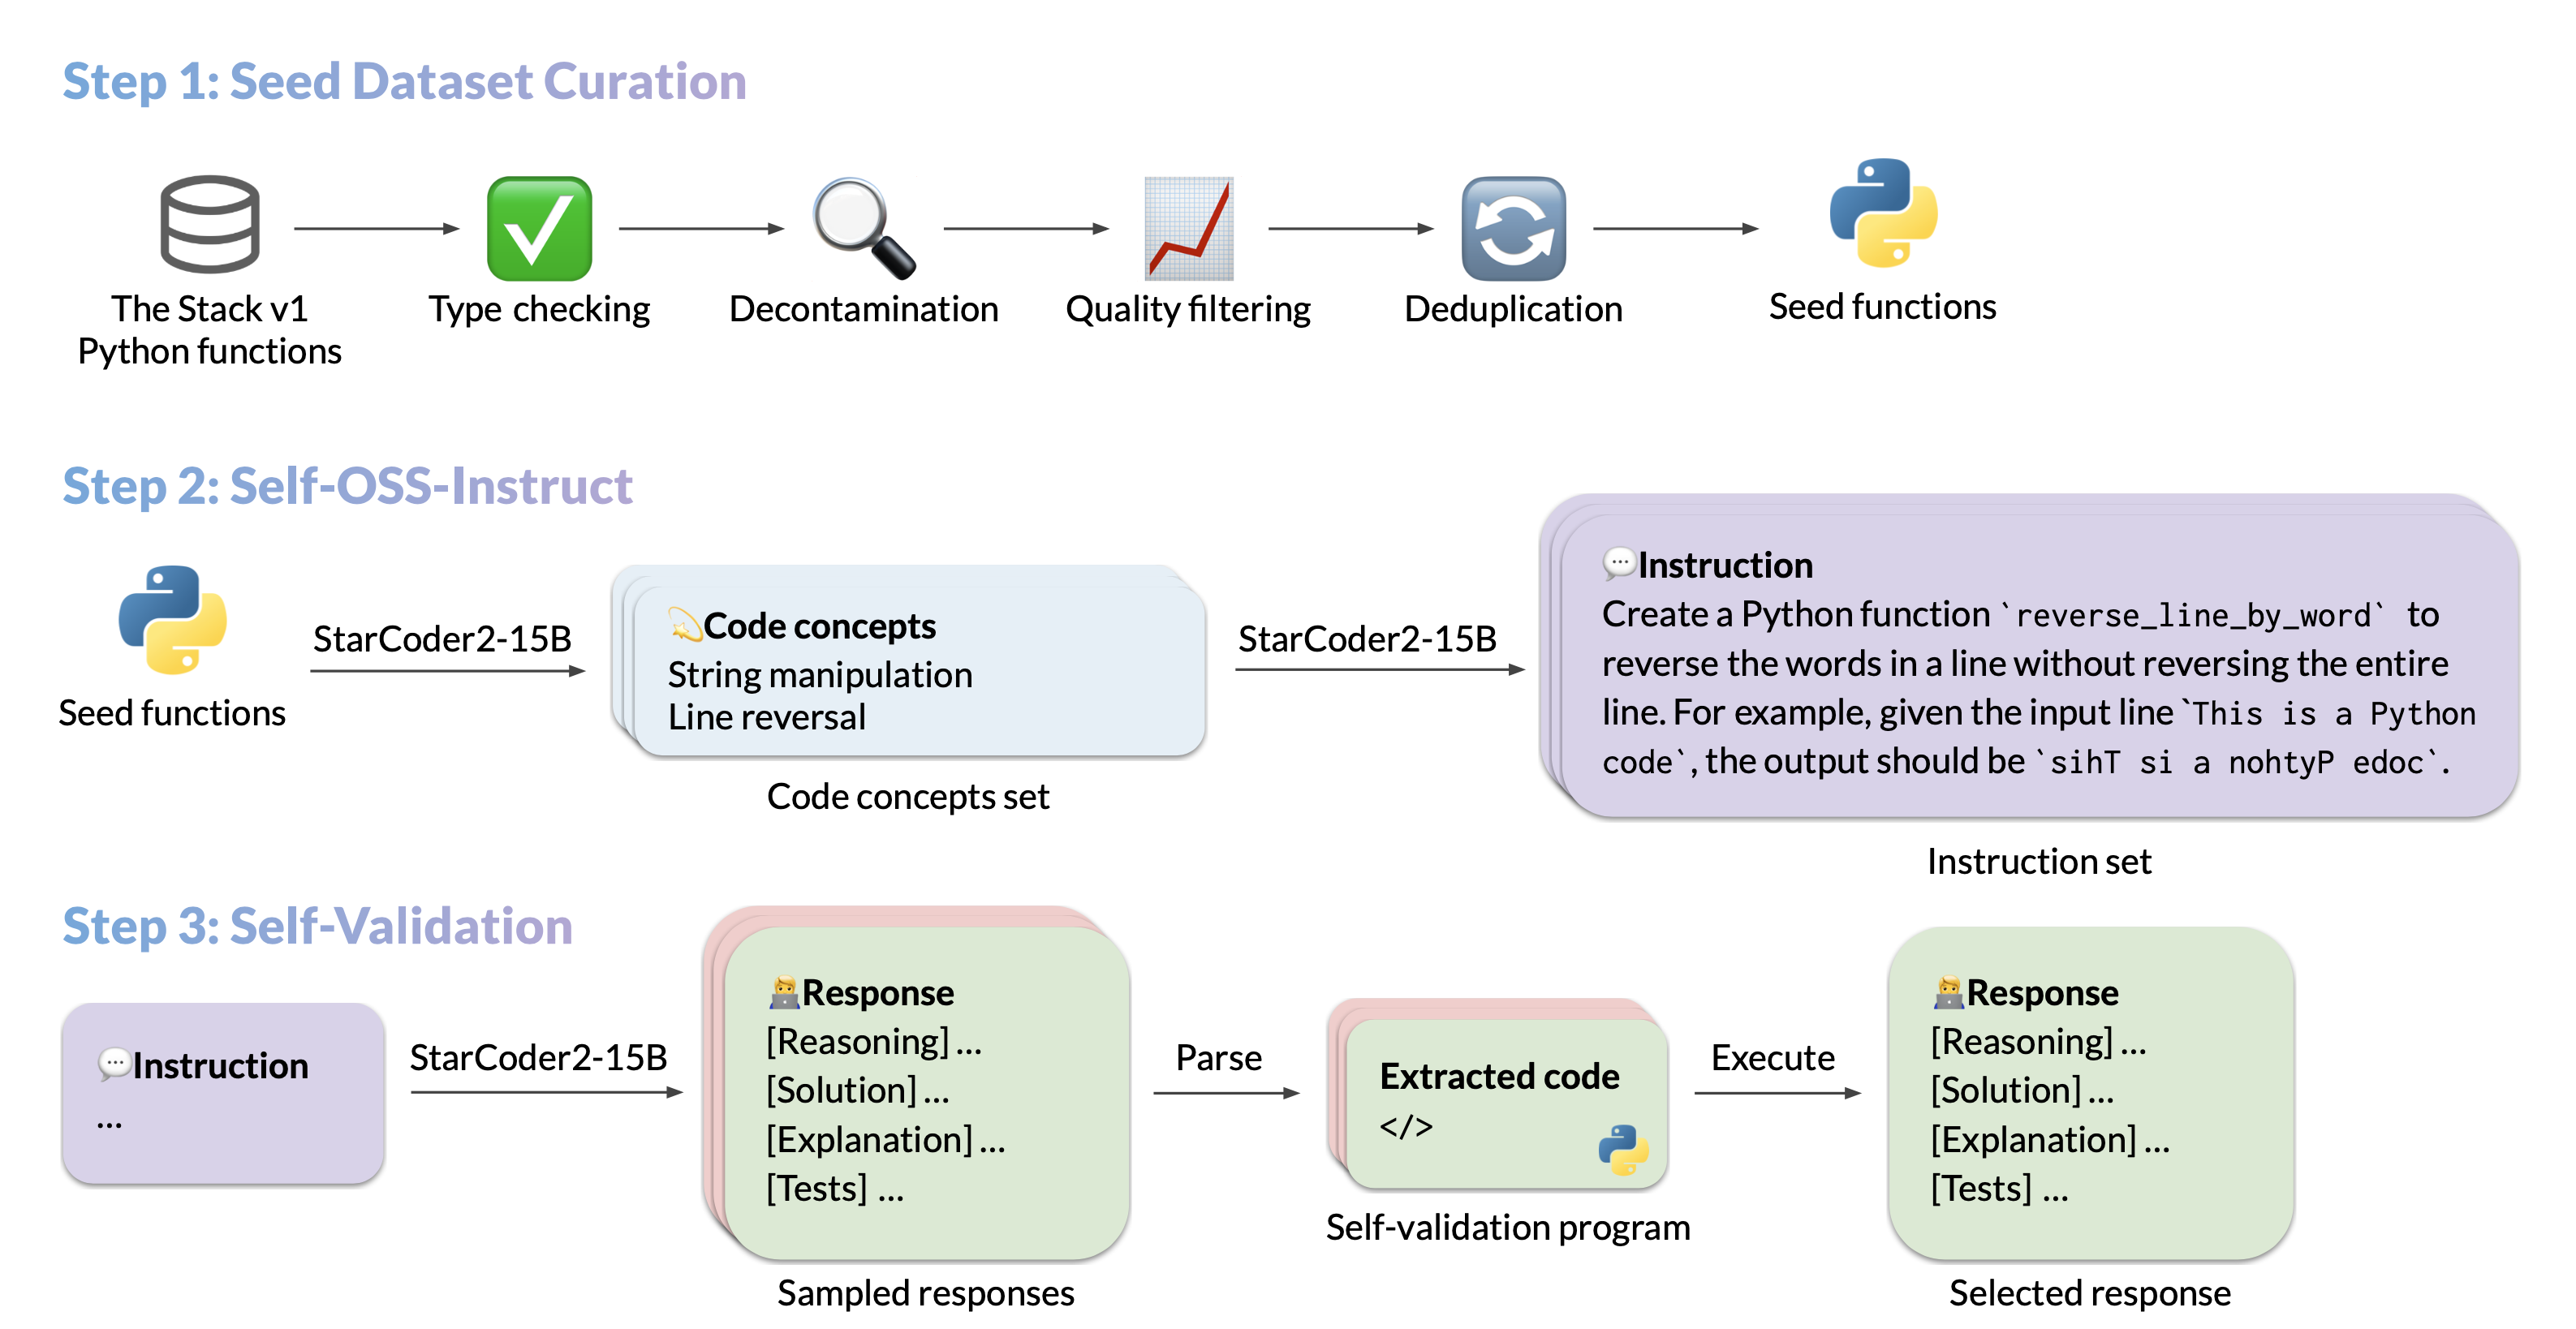
Our data generation pipeline mainly consists of three steps:
- Extract high-quality and diverse seed functions from The Stack v1, a huge corpus of permissively licensed source code.
- Create diverse and realistic code instructions that incorporate different code concepts present in the seed functions (e.g., data deserialization, list concatenation, and recursion).
- For each instruction, generate a high-quality response through execution-guided self-validation.
In the following sections, we will explore each of these aspects in detail.
Collecting seed code snippets
To fully unlock the instruction-following capabilities of a code model, it should be exposed to a diverse set of instructions encompassing a wide range of programming principles and practices. Motivated by OSS-Instruct, we further promote such diversity by mining code concepts from open-source code snippets that are, specifically, well-formed seed Python functions from The Stack V1.
For our seed dataset, we carefully extract all Python functions with docstrings in The Stack V1, infer dependencies required using autoimport, and apply the following filtering rules on all functions:
- Type checking: We apply the Pyright heuristic type-checker to remove all functions that produce static errors, signaling a possibly incorrect item.
- Decontamination: We detect and remove all benchmark items on which we evaluate. We use exact string match on both the solutions and prompts.
- Docstring Quality Filtering: We utilize StarCoder2-15B as a judge to remove functions with poor documentation. We prompt the base model with 7 few-shot examples, requiring it to respond with either “Yes” or “No” for retaining the item.
- Near-Deduplication: We utilize MinHash and locality-sensitive hashing with a Jaccard similarity threshold of 0.5 to filter duplicate seed functions in our dataset. This is the same process applied to StarCoder’s training data.
This filtering pipeline results in a dataset of 250k Python functions filtered from 5M functions with docstrings. This process is highly inspired by the data collection pipeline used in MultiPL-T.
Self-OSS-Instruct
After collecting the seed functions, we use Self-OSS-Instruct to generate diverse instructions. In detail, we employ in-context learning to let the base StarCoder2-15B self-generate instructions from the given seed code snippets. This process utilizes 16 carefully designed few-shot examples, each formatted as (snippet, concepts, instruction). The instruction generation procedure is divided into two steps:
- Concepts extraction: For each seed function, StarCoder2-15B is prompted to produce a list of code concepts present within the function. Code concepts refer to the foundational principles and techniques used in programming, such as pattern matching and data type conversion, which are crucial for developers to master.
- Instruction generation: StarCoder2-15B is then prompted to self-generate a coding task that incorporates the identified code concepts.
Eventually, 238k instructions are generated from this process.
Response self-validation
Given the instructions generated from Self-OSS-Instruct, our next step is to match each instruction with a high-quality response. Prior practices commonly rely on distilling responses from stronger teacher models, such as GPT-4, which hopefully exhibit higher quality. However, distilling proprietary models leads to non-permissive licensing and a stronger teacher model might not always be available. More importantly, teacher models can be wrong as well, and the distribution gap between teacher and student can be detrimental.
We propose to self-align StarCoder2-15B by explicitly instructing the model to generate tests for self-validation after it produces a response interleaved with natural language. This process is similar to how developers test their code implementations. Specifically, for each instruction, StarCoder2-15B generates 10 samples of the format (NL Response, Test) and we filter out those falsified by the test execution under a sandbox environment. We then randomly select one passing response per instruction to the final SFT dataset. In total, we generated 2.4M (10 x 238k) responses for the 238k instructions with temperature 0.7, where 500k passed the execution test. After deduplication, we are left with 50k instructions, each paired with a random passing response, which we finally use as our SFT dataset.
Evaluation
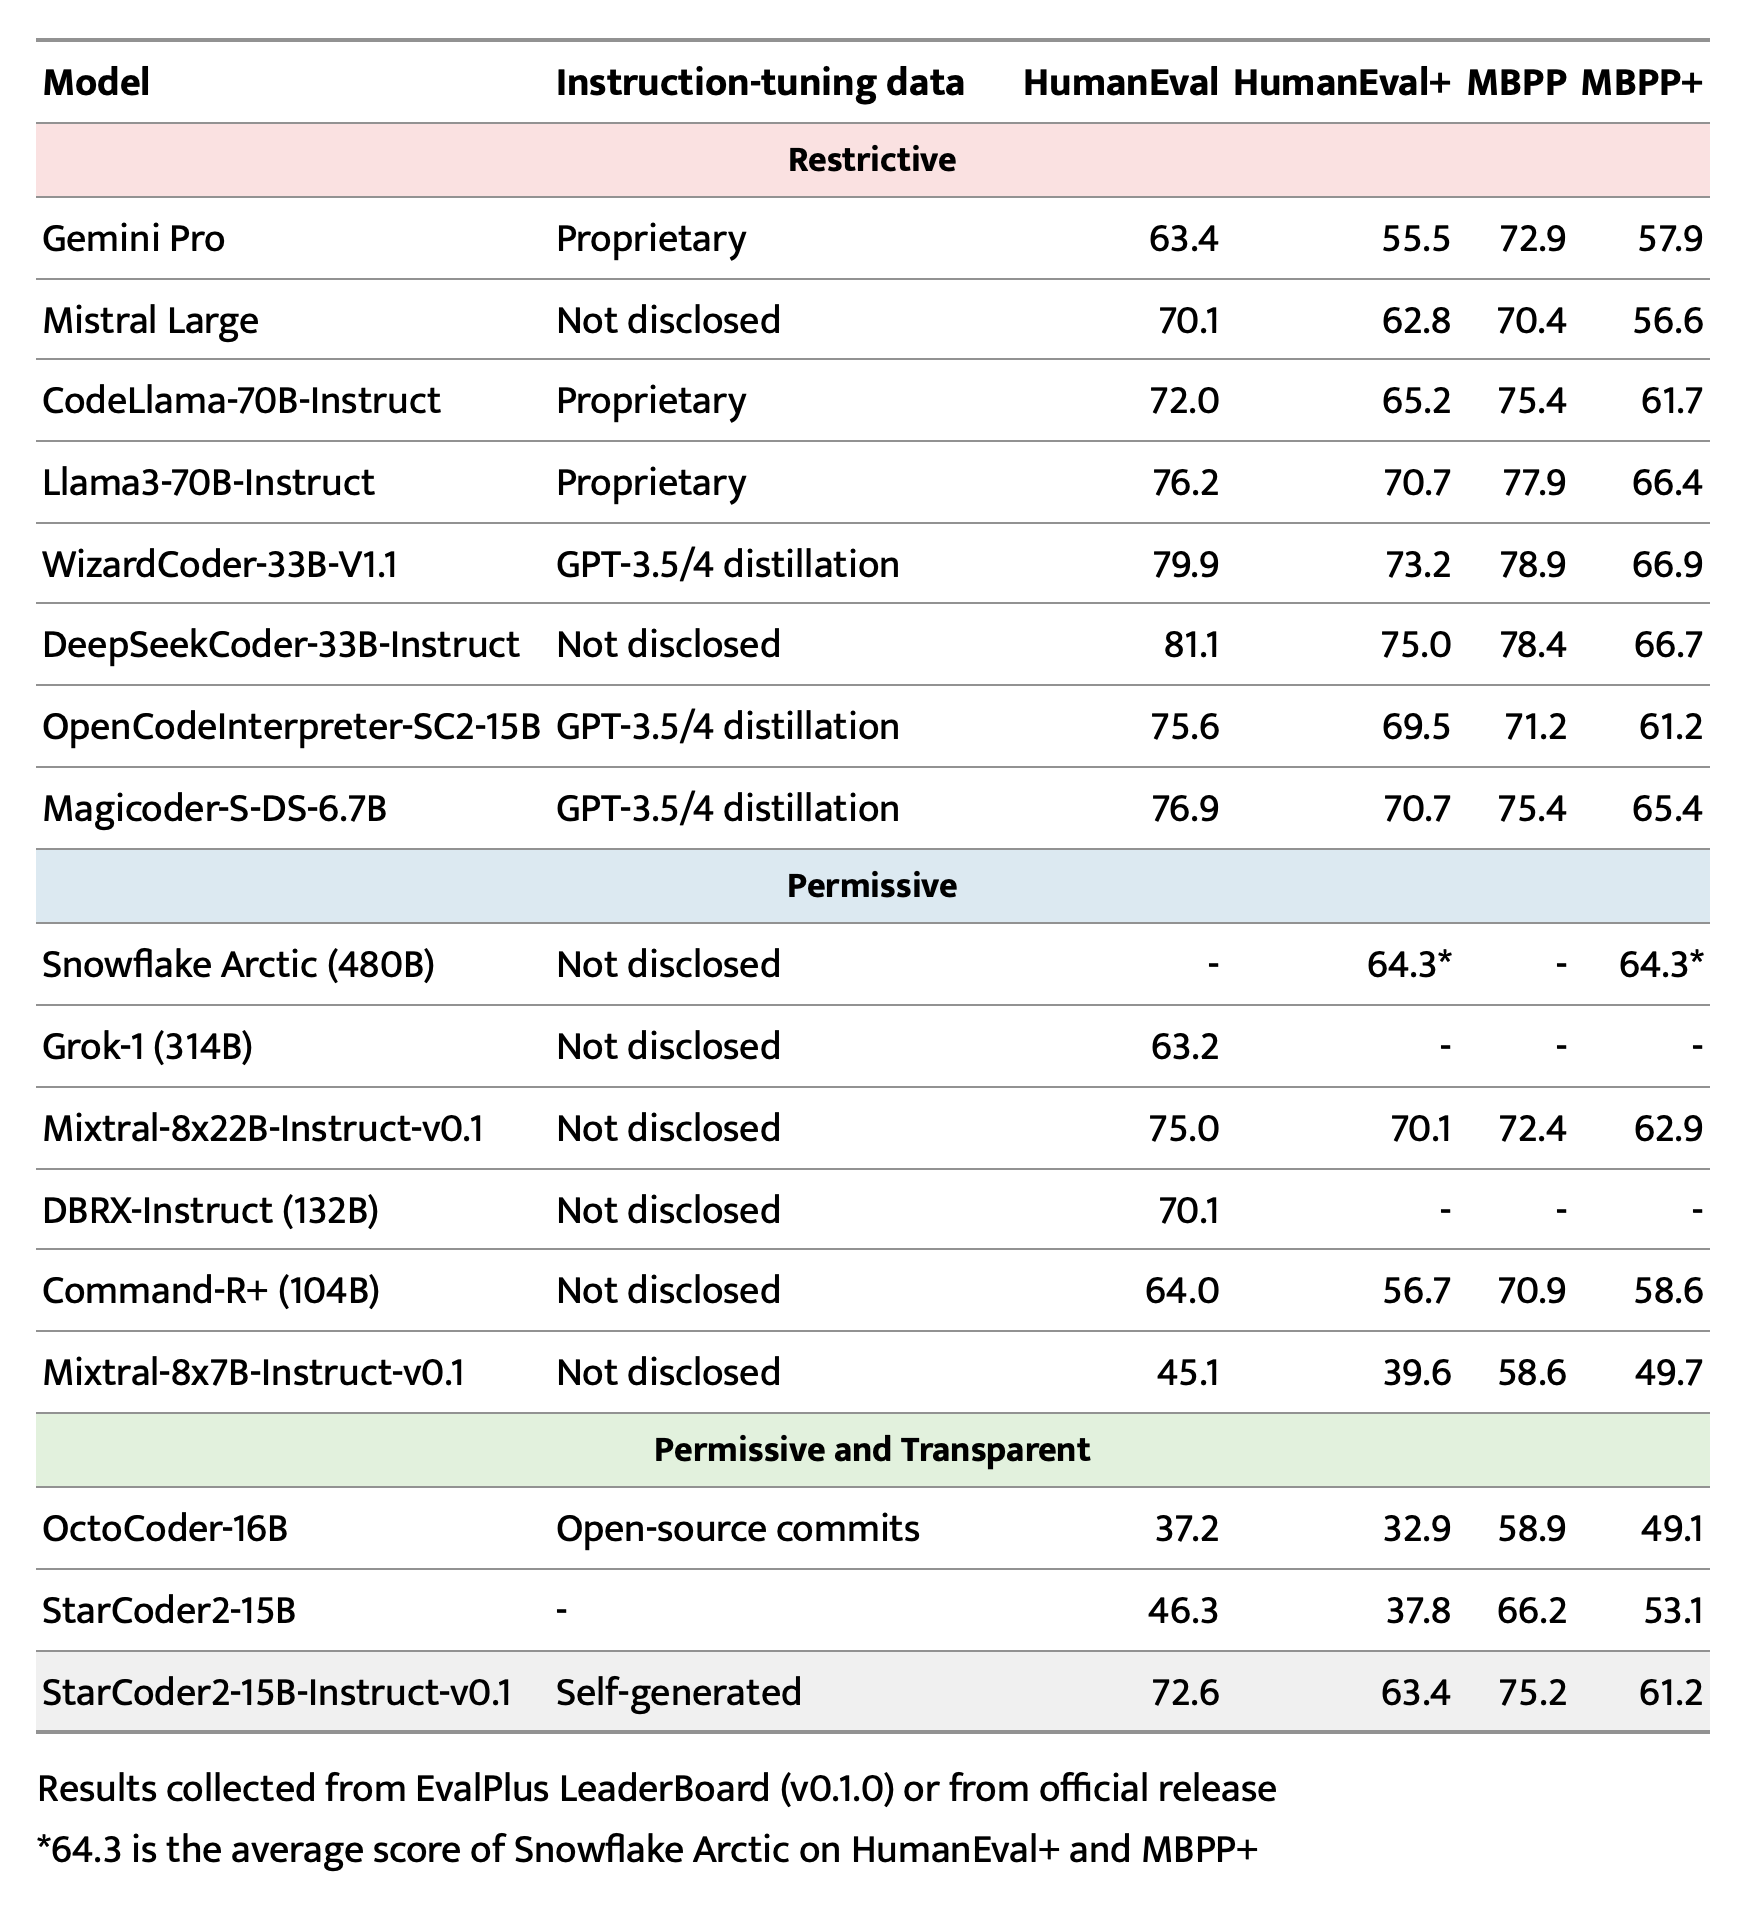
On the popular and rigorous EvalPlus benchmark, StarCoder2-15B-Instruct stands out as the top-performing permissive LLM at its scale, outperforming the much larger Grok-1 Command-R+, DBRX, while closely matching Snowflake Arctic 480B and Mixtral-8x22B-Instruct. To our knowledge, StarCoder2-15B-Instruct is the first code LLM with a fully transparent and permissive pipeline reaching a 70+ HumanEval score. It drastically outperforms OctoCoder, which is the previous state-of-the-art permissive code LLM with a transparent pipeline.
Even compared to powerful LLMs with restrictive licenses, StarCoder2-15B-Instruct remains competitive, surpassing Gemini Pro and Mistral Large and comparable to CodeLlama-70B-Instruct. Additionally, StarCoder2-15B-Instruct, trained purely on self-generated data, closely rivals OpenCodeInterpreter-SC2-15B, which finetunes StarCoder2-15B on distilled data from GPT-3.5/4.
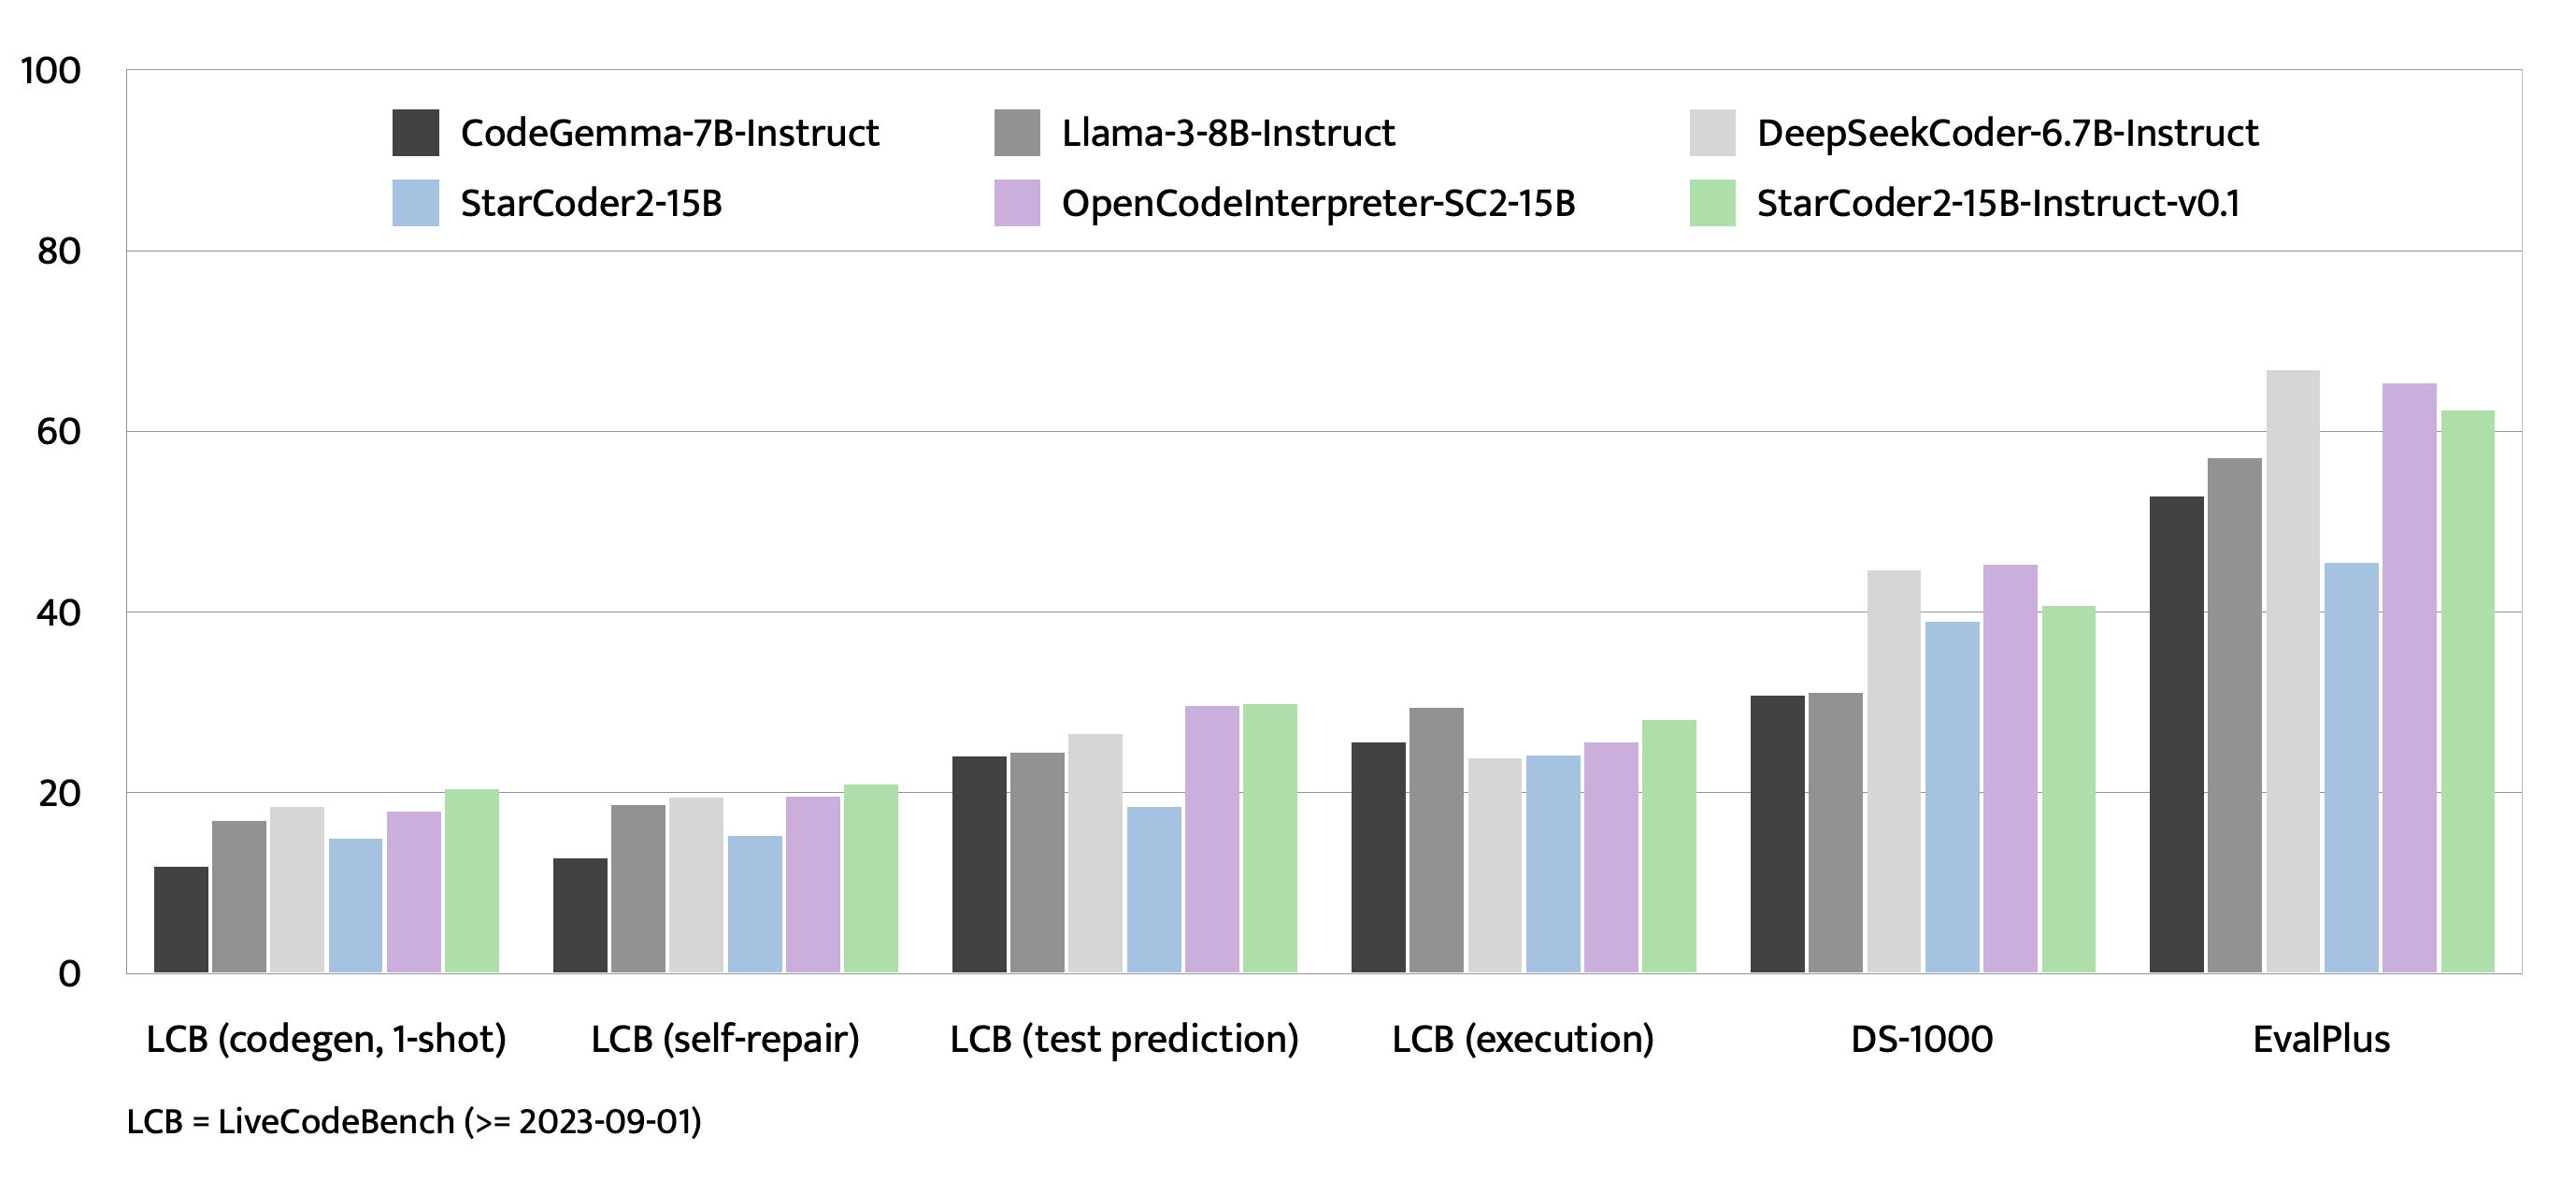
Besides EvalPlus, we also evaluated state-of-the-art open-source models with similar or smaller sizes on LiveCodeBench, which includes fresh coding problems created after 2023-09-01, as well as DS-1000 that targets data science programs. On LiveCodeBench, StarCoder2-15B-Instruct achieves the best results among the models evaluated and consistently outperforms OpenCodeInterpreter-SC2-15B which distills GPT-4 data. On DS-1000, the StarCoder2-15B-Instruct is still competitive despite being trained on very limited data science problems.
Conclusion
StarCoder2-15B-Instruct-v0.1 showcases for the first time that we can create powerful instruction-tuned code models without relying on stronger teacher models like GPT-4. This model demonstrates that self-alignment, where a model uses its own generated content to learn, is also effective for code. It is fully transparent and allows for distillation, setting it apart from other larger permissive but non-transparent models such as Snowflake-Arctic, Grok-1, Mixtral-8x22B, DBRX, and CommandR+. We have made our datasets and the entire pipeline, including data curation and training, fully open-source. We hope this seminal work can inspire more future research and development in this field.
Resources
Citation
@article{wei2024selfcodealign,
  title={SelfCodeAlign: Self-Alignment for Code Generation},
  author={Yuxiang Wei and Federico Cassano and Jiawei Liu and Yifeng Ding and Naman Jain and Zachary Mueller and Harm de Vries and Leandro von Werra and Arjun Guha and Lingming Zhang},
  year={2024},
  journal={arXiv preprint arXiv:2410.24198}
}
