

🤗 Diffusers is happy to celebrate its first anniversary! It has been an exciting year, and we’re proud and grateful for how far we’ve come thanks to our community and open-source contributors. Last year, text-to-image models like DALL-E 2, Imagen, and Stable Diffusion captured the world’s attention with their ability to generate stunningly photorealistic images from text, sparking a massive surge of interest and development in generative AI. But access to these powerful models was limited.
At Hugging Face, our mission is to democratize good machine learning by collaborating and helping each other build an open and ethical AI future together. Our mission motivated us to create the 🤗 Diffusers library so everyone can experiment, research, or simply play with text-to-image models. That’s why we designed the library as a modular toolbox, so you can customize a diffusion model’s components or just start using it out-of-the-box.
As 🤗 Diffusers turns 1, here’s an overview of some of the most notable features we’ve added to the library with the help of our community. We are proud and immensely grateful for being part of an engaged community that promotes accessible usage, pushes diffusion models beyond just text-to-image generation, and is an all-around inspiration.
Table of Contents
Striving for photorealism
Generative AI models are known for creating photorealistic images, but if you look closely, you may notice certain things that don’t look right, like generating extra fingers on a hand. This year, the DeepFloyd IF and Stability AI SDXL models made a splash by improving the quality of generated images to be even more photorealistic.
DeepFloyd IF – A modular diffusion model that includes different processes for generating an image (for example, an image is upscaled 3x to produce a higher resolution image). Unlike Stable Diffusion, the IF model works directly on the pixel level, and it uses a large language model to encode text.
Stable Diffusion XL (SDXL) – The latest Stable Diffusion model from Stability AI, with significantly more parameters than its predecessor Stable Diffusion 2. It generates hyper-realistic images, leveraging a base model for close adherence to the prompt, and a refiner model specialized in the fine details and high-frequency content.
Head over to the DeepFloyd IF docs and the SDXL docs today to learn how to start generating your own images!
Video pipelines
Text-to-image pipelines are cool, but text-to-video is even cooler! We currently support two text-to-video pipelines, VideoFusion and Text2Video-Zero.
If you’re already familiar with text-to-image pipelines, using a text-to-video pipeline is very similar:
import torch
from diffusers import DiffusionPipeline
from diffusers.utils import export_to_video

pipe = DiffusionPipeline.from_pretrained("cerspense/zeroscope_v2_576w", torch_dtype=torch.float16)
pipe.enable_model_cpu_offload()

prompt = "Darth Vader surfing a wave"
video_frames = pipe(prompt, num_frames=24).frames
video_path = export_to_video(video_frames)
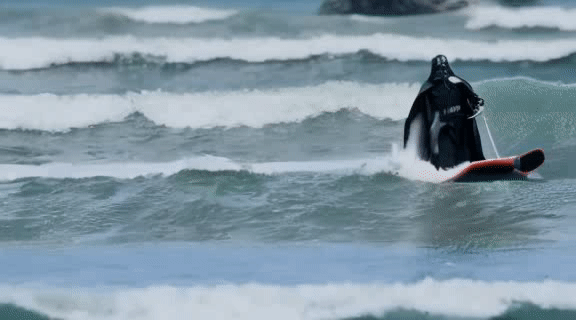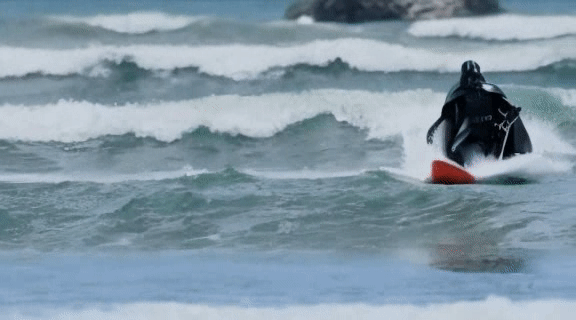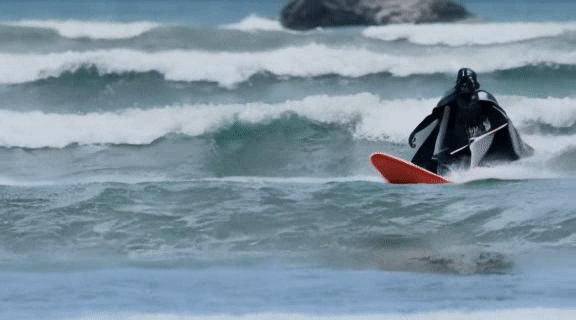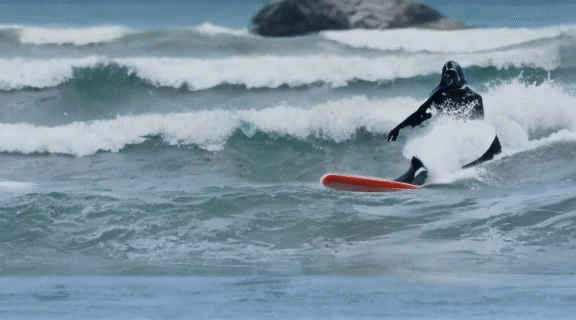
We expect text-to-video to go through a revolution during 🤗 Diffusers second year, and we are excited to see what the community builds on top of these to push the boundaries of video generation from language!
Text-to-3D models
In addition to text-to-video, we also have text-to-3D generation now thanks to OpenAI’s Shap-E model. Shap-E is trained by encoding a large dataset of 3D-text pairs, and a diffusion model is conditioned on the encoder’s outputs. You can design 3D assets for video games, interior design, and architecture.
Try it out today with the ShapEPipeline and ShapEImg2ImgPipeline.
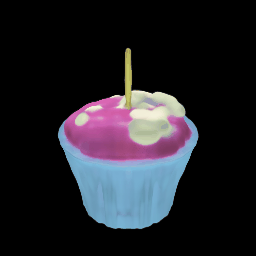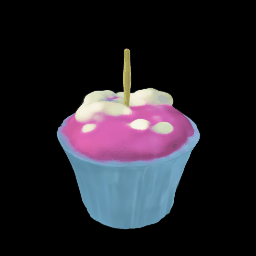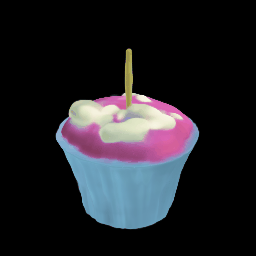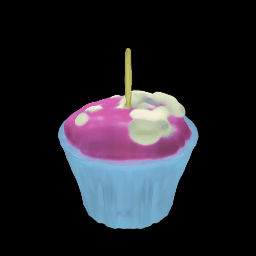
Image editing pipelines
Image editing is one of the most practical use cases in fashion, material design, and photography. With diffusion models, the possibilities of image editing continue to expand.
We have many pipelines in 🤗 Diffusers to support image editing. There are image editing pipelines that allow you to describe your desired edit as a prompt, removing concepts from an image, and even a pipeline that unifies multiple generation methods to create high-quality images like panoramas. With 🤗 Diffusers, you can experiment with the future of photo editing now!
Faster diffusion models
Diffusion models are known to be time-intensive because of their iterative steps. With OpenAI’s Consistency Models, the image generation process is significantly faster. Generating a single 256×256 resolution image only takes 3/4 of a second on a modern CPU! You can try this out in 🤗 Diffusers with the ConsistencyModelPipeline.
On top of speedier diffusion models, we also offer many optimization techniques for faster inference like PyTorch 2.0’s scaled_dot_product_attention() (SDPA) and torch.compile(), sliced attention, feed-forward chunking, VAE tiling, CPU and model offloading, and more. These optimizations save memory, which translates to faster generation, and allow you to run inference on consumer GPUs. When you distribute a model with 🤗 Diffusers, all of these optimizations are immediately supported!
In addition to that, we also support specific hardware and formats like ONNX, the mps PyTorch device for Apple Silicon computers, Core ML, and others.
To learn more about how we optimize inference with 🤗 Diffusers, check out the docs!
Ethics and safety
Generative models are cool, but they also have the ability to produce harmful and NSFW content. To help users interact with these models responsibly and ethically, we’ve added a safety_checker component that flags inappropriate content generated during inference. Model creators can choose to incorporate this component into their models if they want.
In addition, generative models can also be used to produce disinformation. Earlier this year, the Balenciaga Pope went viral for how realistic the image was despite it being fake. This underscores the importance and need for a mechanism to distinguish between generated and human content. That’s why we’ve added an invisible watermark for images generated by the SDXL model, which helps users be better informed.
The development of these features is guided by our ethical charter, which you can find in our documentation.
Support for LoRA
Fine-tuning diffusion models is expensive and out of reach for most consumer GPUs. We added the Low-Rank Adaptation (LoRA) technique to close this gap. With LoRA, which is a method for parameter-efficient fine-tuning, you can fine-tune large diffusion models faster and consume less memory. The resulting model weights are also very lightweight compared to the original model, so you can easily share your custom models. If you want to learn more, our documentation shows how to perform fine-tuning and inference on Stable Diffusion with LoRA.
In addition to LoRA, we support other training techniques for personalized generation, including DreamBooth, textual inversion, custom diffusion, and more!
Torch 2.0 optimizations
PyTorch 2.0 introduced support for torch.compile()and scaled_dot_product_attention(), a more efficient implementation of the attention mechanism. 🤗 Diffusers provides first-class support for these features resulting in massive speedups in inference latency, which can sometimes be more than twice as fast!
In addition to visual content (images, videos, 3D assets, etc.), we also added support for audio! Check out the documentation to learn more.
Community highlights
One of the most gratifying experiences of the past year has been seeing how the community is incorporating 🤗 Diffusers into their projects. From adapting Low-rank adaptation (LoRA) for faster training of text-to-image models to building a state-of-the-art inpainting tool, here are a few of our favorite projects:
We built Core ML Stable Diffusion to make it easier for developers to add state-of-the-art generative AI capabilities in their iOS, iPadOS and macOS apps with the highest efficiency on Apple Silicon. We built on top of 🤗 Diffusers instead of from scratch as 🤗 Diffusers consistently stays on top of a rapidly evolving field and promotes much needed interoperability of new and old ideas.

🤗 Diffusers has been absolutely developer-friendly for me to dive right into stable diffusion models. Main differentiating factor clearly being that 🤗 Diffusers implementation is often not some code from research lab, that are mostly focused on high velocity driven. While research codes are often poorly written and difficult to understand (lack of typing, assertions, inconsistent design patterns and conventions), 🤗 Diffusers was a breeze to use for me to hack my ideas within couple of hours. Without it, I would have needed to invest significantly more amount of time to start hacking. Well-written documentations and examples are extremely helpful as well.

BentoML is the unified framework for for building, shipping, and scaling production-ready AI applications incorporating traditional ML, pre-trained AI models, Generative and Large Language Models. All Hugging Face Diffuser models and pipelines can be seamlessly integrated into BentoML applications, enabling the running of models on the most suitable hardware and independent scaling based on usage.

Invoke AI is an open-source Generative AI tool built to empower professional creatives, from game designers and photographers to architects and product designers. Invoke recently launched their hosted offering at invoke.ai, allowing users to generate assets from any computer, powered by the latest research in open-source.

TaskMatrix connects Large Language Model and a series of Visual Models to enable sending and receiving images during chatting.

Lama Cleaner is a powerful image inpainting tool that uses Stable Diffusion technology to remove unwanted objects, defects, or people from your pictures. It can also erase and replace anything in your images with ease.

Grounded-SAM combines a powerful Zero-Shot detector Grounding-DINO and Segment-Anything-Model (SAM) to build a strong pipeline to detect and segment everything with text inputs. When combined with 🤗 Diffusers inpainting models, Grounded-SAM can do highly controllable image editing tasks, including replacing specific objects, inpainting the background, etc.

Stable-Dreamfusion leverages the convenient implementations of 2D diffusion models in 🤗 Diffusers to replicate recent text-to-3D and image-to-3D methods.

MMagic (Multimodal Advanced, Generative, and Intelligent Creation) is an advanced and comprehensive Generative AI toolbox that provides state-of-the-art AI models (e.g., diffusion models powered by 🤗 Diffusers and GAN) to synthesize, edit and enhance images and videos. In MMagic, users can use rich components to customize their own models like playing with Legos and manage the training loop easily.

Tune-A-Video, developed by Jay Zhangjie Wu and his team at Show Lab, is the first to fine-tune a pre-trained text-to-image diffusion model using a single text-video pair and enables changing video content while preserving motion.

We also collaborated with Google Cloud (who generously provided the compute) to provide technical guidance and mentorship to help the community train diffusion models with TPUs (check out a summary of the event here). There were many cool models such as this demo that combines ControlNet with Segment Anything.

Finally, we were delighted to receive contributions to our codebase from over 300 contributors, which allowed us to collaborate together in the most open way possible. Here are just a few of the contributions from our community:
Besides these, a heartfelt shoutout to the following contributors who helped us ship some of the most powerful features of Diffusers (in no particular order):
Building products with 🤗 Diffusers
Over the last year, we also saw many companies choosing to build their products on top of 🤗 Diffusers. Here are a couple of products that have caught our attention:
- PlaiDay: “PlaiDay is a Generative AI experience where people collaborate, create, and connect. Our platform unlocks the limitless creativity of the human mind, and provides a safe, fun social canvas for expression.”
- Previs One: “Previs One is a diffuser pipeline for cinematic storyboarding and previsualization — it understands film and television compositional rules just as a director would speak them.”
- Zust.AI: “We leverage Generative AI to create studio-quality product photos for brands and marketing agencies.”
- Dashtoon: “Dashtoon is building a platform to create and consume visual content. We have multiple pipelines that load multiple LORAs, multiple control-nets and even multiple models powered by diffusers. Diffusers has made the gap between a product engineer and a ML engineer super low allowing dashtoon to ship user value faster and better.”
- Virtual Staging AI: “Filling empty rooms with beautiful furniture using generative models.”
- Hexo.AI: “Hexo AI helps brands get higher ROI on marketing spends through Personalized Marketing at Scale. Hexo is building a proprietary campaign generation engine which ingests customer data and generates brand compliant personalized creatives.”
If you’re building products on top of 🤗 Diffusers, we’d love to chat to understand how we can make the library better together! Feel free to reach out to patrick@hf.co or sayak@hf.co.
Looking forward
As we celebrate our first anniversary, we’re grateful to our community and open-source contributors who have helped us come so far in such a short time. We’re happy to share that we’ll be presenting a 🤗 Diffusers demo at ICCV 2023 this fall – if you’re attending, do come and see us! We’ll continue to develop and improve our library, making it easier for everyone to use. We’re also excited to see what the community will create next with our tools and resources. Thank you for being a part of our journey so far, and we look forward to continuing to democratize good machine learning together! 🥳
❤️ Diffusers team
Acknowledgements: Thank you to Omar Sanseviero, Patrick von Platen, Giada Pistilli for their reviews, and Chunte Lee for designing the thumbnail.
