

Handling load from multiple users in parallel is crucial for the performance of LLM applications. In the previous part of our series on LLM performance, we discussed queueing strategies for the prioritization of different users. In this second part, we will now focus on the concurrent processing of requests, and how it impacts relevant metrics such as latency and throughput as well as GPU resource utilization.

At TNG, we are self-hosting numerous Large Language Models on our cluster of 24 H100 GPUs. It supports 50 different applications, handles over 5,000 inferences per hour, and generates more than ten million tokens every day.
The Two Stages of Token Generation: Prefill and Decode
Most LLMs generate text token by token, which guarantees that every new token is computed based on all preceding tokens (this model property is called auto-regressive). The first output token depends on all prompt tokens, but the second output token already depends on all prompt tokens plus the first output token, and so on. As a consequence, token generation cannot be parallelized at the level of an individual request.
In LLMs with attention mechanisms, computing a new token requires calculating key, value, and query vectors for each preceding token. Fortunately, the results of some particular calculations can be re-used for subsequent tokens. This concept is known as key-value (KV) cache. For every additional output token, only one more set of key and value vectors needs to be calculated and added to the KV cache. For the very first output token, however, we start with an initially empty KV cache and need to calculate as many sets of key and value vectors as there are tokens in the input prompt. Luckily, and in contrast to any later token generation, all input tokens are known from the beginning, and we can parallelize the calculation of their respective key and value vectors. This difference motivates the distinction between the prefill (computing the first output token) and the decode phase (computing any later output token).
In the prefill phase, the calculations for all input tokens can be executed in parallel, while in the decode phase, no parallelization is possible on the level of individual requests.

Metrics
The difference between the prefill and decode phases is also reflected in two key metrics for text generation: Time to first token and time per output token. The time to first token is given by the latency of the prefill phase, while the time per output token is the latency of a single decode step. Even though the prefill phase also generates only a single token, it takes much longer than a single decode step, because all input tokens need to be processed. On the other hand, the prefill phase is much faster with respect to the number of input tokens than a decode phase for the same number of output tokens (this difference is the reason why commercial LLM APIs charge input tokens at a much lower rate than ouput tokens).

Both latencies are relevant metrics for interactive applications like a chat bot. If users have to wait for more than 5 seconds before they see a response, they might think that the application is broken and leave. Similarly, if the text generation is as slow as 1 token per second, they would not be patient enough to wait until it is finished. Typical latency targets for interactive applications are 100-300ms per output token (i.e. a token generation speed of 3-10 tokens per second, at least as fast as reading speed, which ideally allows for skimming the output text as it is being generated), and a time to first token of 3 seconds or less. Both of these latency targets can be quite challenging to achieve, depending on the model size, hardware, prompt length, and concurrent load.
Other, non-interactive use cases might not be interested in the latencies of individual requests, but only in the total token throughput (tokens per second, summed up over all concurrent requests). This could be relevant when you want to generate translations for books, or summarize code files in a large repository.
As we will see in a later section, there generally is a trade-off between maximizing the total throughput and minimizing latencies for each individual request.
Resource Utilization
Because of the parallelized calculation for all input tokens, the prefill phase is very GPU compute-intensive. In contrast, the decode step for an individual output token utilizes very little computational power; here, the speed is typically limited by the GPU memory bandwidth, i.e. how quickly model weights and activations (including key and value vectors) can be loaded from and accessed within the GPU memory.
In general, token throughput can be increased until the GPU utilization (w.r.t. computational power) is saturated. In the prefill phase, a single request with a long prompt can already achieve maximum GPU utilization. In the decode phase, the GPU utilization can be increased by batch processing of multiple requests. As a consequence, when you plot the token throughput as a function of the number of concurrent requests, you see an almost linear increase in throughput at low concurrency, because this memory-bound regime benefits from larger batch sizes. Once the GPU utilization saturates and the compute-bound regime is entered, the throughput remains invariant to an increase in concurrency.

Concurrent Processing
We will now consider how exactly an inference engine handles multiple requests that arrive within a short time interval.
Both the prefill and decode phases can make use of batching strategies to apply the same set of operations to different requests. But what are the consequences of running prefill and decode of different requests at the same time?
Static Batching vs. Continuous Batching
The most naive form of batching is called static batching. (1) You start with an empty batch, (2) you fill the batch with as many items as are waiting and as fit into the batch, (3) you process the batch until all batched items are finished, and (4) you repeat the procedure with a new empty batch.
All requests start their prefill phase at the same time. Since prefill is just a single, but heavily parallelized, GPU operation (think of it as a very large matrix multiplication), the prefill phases of all concurrent requests are completed at the same time. Then, all decode phases start simultaneously. Requests with fewer output tokens would finish earlier, but because of the static batching the next waiting request can only start once the longest batched request has been completed.

Static batching optimizes the time per output token, since the decode phase is uninterrupted. The drawback is a very inefficient resource utilization. Since a single, long prompt can already saturate the compute power during prefill, handling multiple prefills in parallel does not yield a speed-up and will certainly max out GPU utilization. In contrast, the GPU will likely be underutilized during the decode phase, since even a large number of concurrent decodes is not as compute-intensive as the prefill for a long prompt.
The biggest disadvantage, however, is the potentially long time to first token. Even if some short requests finish early, the next queuing request has to wait for the longest decode in the batch to finish before its prefill can begin. Because of this flaw of static batching, inference engines typically implement continuous batching strategies. Here, any completed request is immediately removed from the batch, and the batch space is filled with the next request in line. As a consequence, every continuous batching strategy has to deal with concurrency between prefill and decode phases.
Prefill-First
In an attempt to reduce the waiting time of requests, inference engines such as vLLM and TGI schedule the prefill phase of new requests as soon as they arrive and fit into the current batch. It is possible to run the prefill of new requests in parallel with a single decode step for each of all previous requests, but since everything is executed in the same GPU operation, its duration is dominated by the prefill, and for every request in the decode phase only a single output token can be generated in that time. Therefore, this prioritization of prefills minimizes the time to first token but interrupts the decode phase of already running requests. In a chat application, users can experience this as pausing of the streamed token generation when other users submit long prompts.
In the following measurement you can see the effect of continuous batching with a prefill-first strategy.

Chunked Prefill
One approach to alleviate the impact of interruptive prefills on running decodes is a chunked prefill. Instead of processing the entire prompt in a single prefill step, it can be distributed over multiple chunks. Then there can be as many concurrent decode steps during prefill as there are prefill chunks (as opposed to only a single decode step per concurrent request during the entire prefill). A chunked prefill step will still take longer than an isolated decode step, but for small chunk sizes the user now experiences only a slowing-down of token generation instead of a complete pause; this reduces the average time per output token. From the perspective of the interrupting request, a chunked prefill comes with some overhead and takes a bit longer than an isolated, contiguous prefill, so there is a small increase in the time to first token. With the chunk size we now have a tuning knob for prioritizing either the time to first token or the time per output token. Typical chunk sizes are between 512 and 8192 tokens (the vLLM default was 512 when chunked prefill was first implemented, and was later updated to higher values).
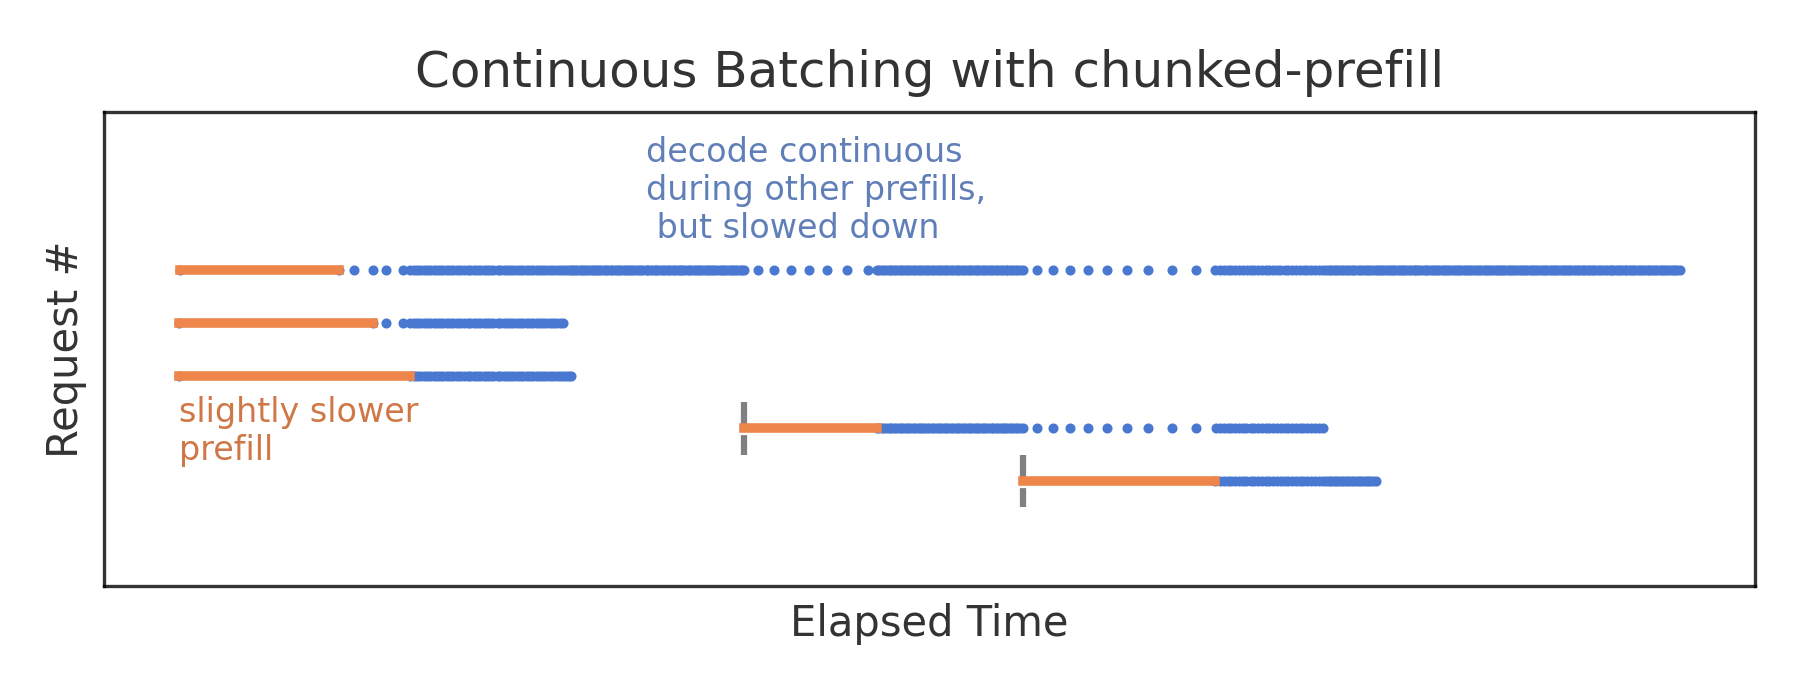
The biggest advantage of this strategy is, however, that chunked prefill maximizes resource efficiency. Prefill is compute-intensive, while decode is memory-bound. By running both operations in parallel, one can increase the overall throughput without being limited by GPU resources. Of course, maximum efficiency is only achieved at a certain chunk size, which in turn depends on the exact load pattern.
In a standard vLLM deployment and for evenly sized requests, we observed that chunked prefill increased the total token throughput by +50%. It is now enabled for every vLLM deployment of self-hosted LLMs at TNG. Overall, chunked prefill is a good default strategy for most use cases. Optimizing the chunk size, however, is quite difficult in environments with unpredictable load patterns (like TNG with its many diverse applications); typically, you stick with the defaults.
Regardless of the exact chunk size configuration, concurrent processing with chunked prefill comes with two challenges that we will address in the next article.
