


This is a guest blog post by the Pollen Robotics team. We are the creators of Reachy, an open-source humanoid robot designed for manipulation in the real world.
In the context of autonomous behaviors, the essence of a robot’s usability lies in its ability to understand and interact with its environment. This understanding primarily comes from visual perception, which enables robots to identify objects, recognize people, navigate spaces, and much more.
We’re excited to share the initial launch of our open-source pollen-vision library, a first step towards empowering our robots with the autonomy to grasp unknown objects. This library is a carefully curated collection of vision models chosen for their direct applicability to robotics. Pollen-vision is designed for ease of installation and use, composed of independent modules that can be combined to create a 3D object detection pipeline, getting the position of the objects in 3D space (x, y, z).
We focused on selecting zero-shot models, eliminating the need for any training, and making these tools instantly usable right out of the box.
Our initial release is focused on 3D object detection—laying the groundwork for tasks like robotic grasping by providing a reliable estimate of objects’ spatial coordinates. Currently limited to positioning within a 3D space (not extending to full 6D pose estimation), this functionality establishes a solid foundation for basic robotic manipulation tasks.
The Core Models of Pollen-Vision
The library encapsulates several key models. We want the models we use to be zero-shot and versatile, allowing a wide range of detectable objects without re-training. The models also have to be “real-time capable”, meaning they should run at least at a few fps on a consumer GPU. The first models we chose are:
- OWL-VIT (Open World Localization – Vision Transformer, By Google Research): This model performs text-conditioned zero-shot 2D object localization in RGB images. It outputs bounding boxes (like YOLO)
- Mobile Sam: A lightweight version of the Segment Anything Model (SAM) by Meta AI. SAM is a zero-shot image segmentation model. It can be prompted with bounding boxes or points.
- RAM (Recognize Anything Model by OPPO Research Institute): Designed for zero-shot image tagging, RAM can determine the presence of an object in an image based on textual descriptions, laying the groundwork for further analysis.
Get started in very few lines of code!
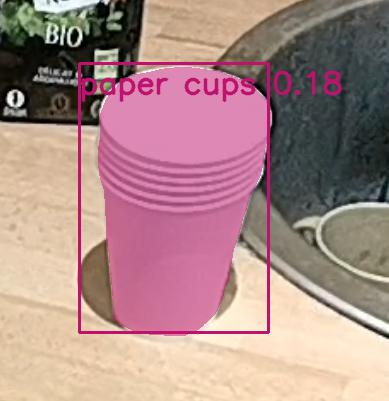
Below is an example of how to use pollen-vision to build a simple object detection and segmentation pipeline, taking only images and text as input.
from pollen_vision.vision_models.object_detection import OwlVitWrapper
from pollen_vision.vision_models.object_segmentation import MobileSamWrapper
from pollen_vision.vision_models.utils import Annotator, get_bboxes

owl = OwlVitWrapper()
sam = MobileSamWrapper()
annotator = Annotator()

im = ...
predictions = owl.infer(im, ["paper cups"])
bboxes = get_bboxes(predictions)

masks = sam.infer(im, bboxes=bboxes)
annotated_im = annotator.annotate(im, predictions, masks=masks)
OWL-VIT’s inference time depends on the number of prompts provided (i.e., the number of objects to detect). On a Laptop with a RTX 3070 GPU:
1 prompt   : ~75ms  per frame
2 prompts  : ~130ms per frame
3 prompts  : ~180ms per frame
4 prompts  : ~240ms per frame
5 prompts  : ~330ms per frame
10 prompts : ~650ms per frame
So it is interesting, performance-wise, to only prompt OWL-VIT with objects that we know are in the image. That’s where RAM is useful, as it is fast and provides exactly this information.
A robotics use case: grasping unknown objects in unconstrained environments
With the object’s segmentation mask, we can estimate its (u, v) position in pixel space by computing the centroid of the binary mask. Here, having the segmentation mask is very useful because it allows us to average the depth values inside the mask rather than inside the full bounding box, which also contains a background that would skew the average.
One way to do that is by averaging the u and v coordinates of the non zero pixels in the mask
def get_centroid(mask):
    x_center, y_center = np.argwhere(mask == 1).sum(0) / np.count_nonzero(mask)
    return int(y_center), int(x_center)
We can now bring in depth information in order to estimate the z coordinate of the object. The depth values are already in meters, but the (u, v) coordinates are expressed in pixels. We can get the (x, y, z) position of the centroid of the object in meters using the camera’s intrinsic matrix (K)
def uv_to_xyz(z, u, v, K):
    cx = K[0, 2]
    cy = K[1, 2]
    fx = K[0, 0]
    fy = K[1, 1]

    x = (u - cx) * z / fx
    y = (v - cy) * z / fy

    return np.array([x, y, z])
We now have an estimation of the 3D position of the object in the camera’s reference frame.
If we know where the camera is positioned relative to the robot’s origin frame, we can perform a simple transformation to get the 3D position of the object in the robot’s frame. This means we can move the end effector of our robot where the object is, and grasp it ! 🥳
What’s next?
What we presented in this post is a first step towards our goal, which is autonomous grasping of unknown objects in the wild. There are a few issues that still need addressing:
- OWL-Vit does not detect everything every time and can be inconsistent. We are looking for a better option.
- There is no temporal or spatial consistency so far. All is recomputed every frame
- We are currently working on integrating a point tracking solution to enhance the consistency of the detections
- Grasping technique (only front grasp for now) was not the focus of this work. We will be working on different approaches to enhance the grasping capabilities in terms of perception (6D detection) and grasping pose generation.
- Overall speed could be improved
Try pollen-vision
Wanna try pollen-vision? Check out our Github repository !
