Close Menu
techwavedispatch.com

    Subscribe to Updates

    Get the latest creative news from FooBar about art, design and business.

    What's Hot

    Amazon Is Reportedly Working On A Database For ‘Virtually Every Item For Sale On Earth’

    November 15, 2026

    SNL gathers all the tech tycoons for a lesson in dating and spycraft

    November 15, 2026

    Supercharged Searching on the πŸ€— Hub

    November 15, 2026
    Facebook X (Twitter) Instagram
    Trending
    • Amazon Is Reportedly Working On A Database For ‘Virtually Every Item For Sale On Earth’
    • SNL gathers all the tech tycoons for a lesson in dating and spycraft
    • Supercharged Searching on the πŸ€— Hub
    • What’s The Meaning Of The “A” On Your USB-A Ports?
    • Making automatic speech recognition work on large files with Wav2Vec2 in πŸ€— Transformers
    • Sony Is Ditching Its Cross-Product Support App For Dedicated Alternatives
    • Getting Started with Sentiment Analysis using Python
    • How To Change And Customize Your App Icons On Samsung Galaxy
    Facebook X (Twitter) Instagram
    techwavedispatch.com
    Subscribe
    Sunday, November 15
    • Home
    • AI Tools & Software
    • Machine Learning
    • Generative AI
    • Robotics & Automation
    • Future Tech & Hardware
    • AI in Business
    • Ethics & Regulations
    • More
      • Gadgets & Smart Devices
      • Cybersecurity & AI
      • Tech Breakthroughs
    techwavedispatch.com
    Home»AI Tools & Software»Making automatic speech recognition work on large files with Wav2Vec2 in πŸ€— Transformers
    AI Tools & Software

    Making automatic speech recognition work on large files with Wav2Vec2 in πŸ€— Transformers

    adminBy adminNovember 15, 2026No Comments5 Mins Read
    Facebook Twitter Pinterest LinkedIn Tumblr Email
    Making automatic speech recognition work on large files with Wav2Vec2 in πŸ€— Transformers
    Share
    Facebook Twitter LinkedIn Pinterest Email

    Tl;dr: This post explains how to use the specificities of the Connectionist
    Temporal Classification (CTC) architecture in order to achieve very good
    quality automatic speech recognition (ASR) even on arbitrarily long files or 
    during live inference.
    

    Wav2Vec2 is a popular pre-trained model for speech recognition.
    Released in September 2020
    by Meta AI Research, the novel architecture catalyzed progress in
    self-supervised pretraining for speech recognition, e.g. G. Ng et
    al.
    , 2021
    , Chen et al,
    2021
    , Hsu et al.,
    2021
    and Babu et al.,
    2021
    . On the Hugging Face Hub,
    Wav2Vec2’s most popular pre-trained checkpoint currently amounts to
    over 250,000 monthly
    downloads
    .

    Wav2Vec2 is at its core a transformers models and one caveat
    of transformers is that it usually has a finite amount of sequence
    length it can handle. Either because it uses position encodings (not
    the case here) or simply because the cost of attention in transformers
    is actually O(nΒ²) in sequence_length, meaning that using very large
    sequence_length explodes in complexity/memory. So you cannot run with finite hardware
    (even a very large GPU like A100), simply run Wav2Vec2 on an hour long
    file. Your program will crash. Let’s try it !

    pip install transformers
    
    from transformers import pipeline


    pipe = pipeline(model="facebook/wav2vec2-base-960h")


    pipe("very_long_file.mp3")
    
    
    pipe("very_long_file.mp3", chunk_length_s=10)


    Simple Chunking

    The simplest way to achieve inference on very long files would be to simply chunk
    the initial audio into shorter samples, let’s say 10 seconds each, run inference on those, and end up
    with a final reconstruction. This is efficient computationally but usually leads
    to subpar results, the reason being that in order to do good inference, the model
    needs some context, so around the chunking border, inference tends to be of poor
    quality.

    Look at the following diagram:
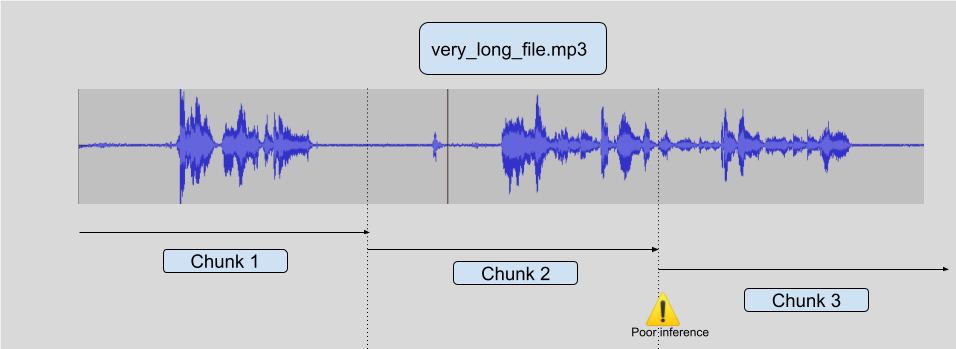
    Simple chunking

    There are ways to try and work around the problem in a general fashion, but
    they are never entirely robust. You can try to chunk only when you encounter
    silence but you may have a non silent audio for a long time (a song, or noisy
    cafΓ© audio). You can also try to cut only when there’s no voice but it requires
    another model and this is not an entirely solved problem. You could also have
    a continous voice for a very long time.

    As it turns out, CTC structure, which is used by Wav2Vec2, can be exploited
    in order to achieve very robust speech recognition even on very long files
    without falling into those pitfalls.


    Chunking with stride

    Wav2Vec2 uses the CTC algorithm, which means that every frame of audio is mapped
    to a single letter prediction (logit).
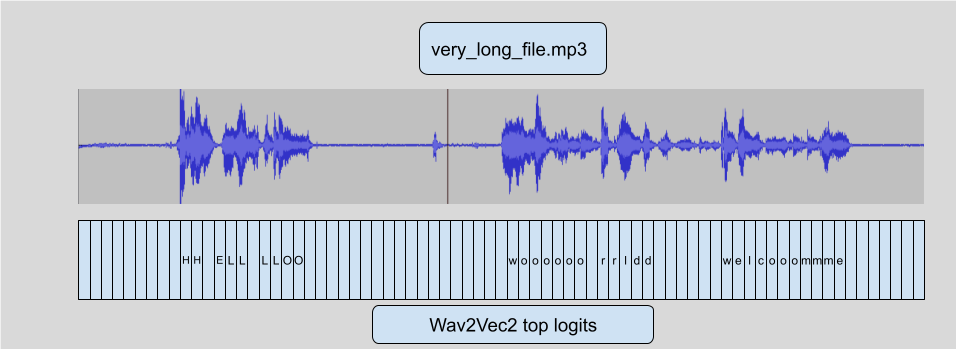
    CTC

    That’s the main feature we’re going to use in order to add a stride.
    This link explains it
    in the image context, but it’s the same concept for audio.
    Because of this property, we can:

    • Start doing inference on overlapping chunks
      so that the model actually has proper context in the center.
    • Drop the inferenced logits on the side.
    • Chain the logits without their dropped sides to recover something extremely close to what the model would have
      predicted on the full length audio.
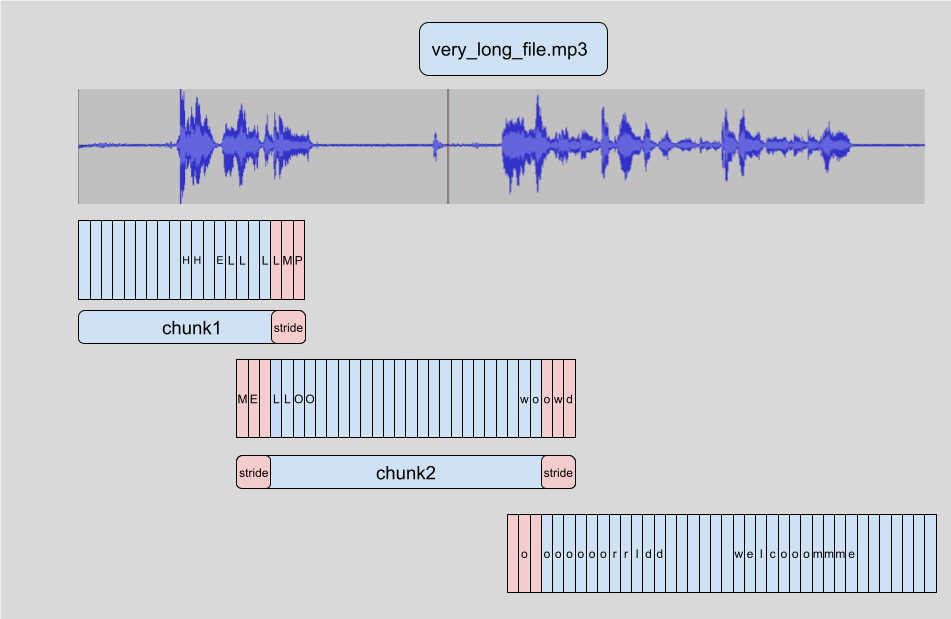
    Striding

    This is not technically 100% the same thing as running the model on the whole
    file so it is not enabled by default, but as you saw in the earlier example you
    need only to add chunk_length_s to your pipeline for it to work.

    In practice, we observed that most of the bad inference is kept within
    the strides, which get dropped before inference, leading to a proper
    inference of the full text.

    Let’s note that you can choose every argument of this technique:

    from transformers import pipeline
    
    pipe = pipeline(model="facebook/wav2vec2-base-960h")


    output = pipe("very_long_file.mp3", chunk_length_s=10, stride_length_s=(4, 2))


    Chunking with stride on LM augmented models

    In transformers, we also
    added support for adding LM to Wav2Vec2 in order to boost the WER performance
    of the models without even finetuning. See this excellent blogpost explaining
    how it works
    .

    It turns out, that the LM works directly on the logits themselves, so we
    can actually apply the exact same technique as before without any modification !
    So chunking large files on these LM boosted models still works out of the box.


    Live inference

    A very nice perk of using a CTC model like Wav2vec2, is that it is a single
    pass model, so it is very fast. Especially on GPU. We can exploit that in order
    to do live inference.

    The principle is exactly the same as regular striding, but this time we can
    feed the pipeline data as it is coming in and simply use striding on
    full chunks of length 10s for instance with 1s striding to get proper context.

    That requires running much more inference steps than simple file chunking, but it can make the
    live experience much better because the model can print things as you are
    speaking, without having to wait for X seconds before seeing something displayed.

    Automatic Files Large Making recognition Speech Transformers Wav2Vec2 Work
    Share. Facebook Twitter Pinterest LinkedIn Tumblr Email
    admin
    • Website

    Related Posts

    Supercharged Searching on the πŸ€— Hub

    November 15, 2026

    Getting Started with Sentiment Analysis using Python

    November 15, 2026

    Fine-Tune ViT for Image Classification with πŸ€— Transformers

    November 15, 2026
    Leave A Reply Cancel Reply

    Top Posts

    NVIDIA Is Investigating Reports That CEO Jensen Huang Was The Target Of Chinese Spy Efforts

    November 8, 202619 Views

    ADIndex: Layer-Adaptive Sparse Attention Indexing via Group-Level Distillation

    November 11, 20265 Views

    Anthropic releases new Mythos and Fable models amid RSI concerns

    November 9, 20265 Views

    One Policy for 100 Household Tasks: Our Solution for the 2026 BEHAVIOR Challenge

    November 11, 20264 Views
    Don't Miss
    Gadgets & Smart Devices

    Amazon Is Reportedly Working On A Database For ‘Virtually Every Item For Sale On Earth’

    By adminNovember 15, 20260

    This would include products that the online commerce giant doesn’t even sell. …

    SNL gathers all the tech tycoons for a lesson in dating and spycraft

    November 15, 2026

    Supercharged Searching on the πŸ€— Hub

    November 15, 2026

    What’s The Meaning Of The “A” On Your USB-A Ports?

    November 15, 2026
    About Us

    Welcome to TechWave Dispatch

    At TechWave Dispatch, we bring you the latest news, insights, and developments from the ever-evolving world of technology. Our mission is to keep readers informed about the innovations shaping our digital future.

    From artificial intelligence and machine learning to cybersecurity, robotics, smart devices, and groundbreaking technologies, we cover the topics that matter in today's fast-moving tech landscape.

    Our Picks

    Amazon Is Reportedly Working On A Database For ‘Virtually Every Item For Sale On Earth’

    November 15, 2026

    SNL gathers all the tech tycoons for a lesson in dating and spycraft

    November 15, 2026

    Supercharged Searching on the πŸ€— Hub

    November 15, 2026
    Most Popular

    After blocking Muse, Amazon now lets users text Alexa to help them shop

    November 6, 20260 Views

    A controlled world for robot learning and evaluation

    November 6, 20260 Views

    Perplexity now has its own always-on AI agent

    November 6, 20260 Views
    Facebook X (Twitter) Instagram Pinterest
    • Terms and Conditions
    • Privacy Policy
    • Contact Us
    • About Us
    Β© 2026 TechWave Dispatch. All Rights Reserved.

    Type above and press Enter to search. Press Esc to cancel.