

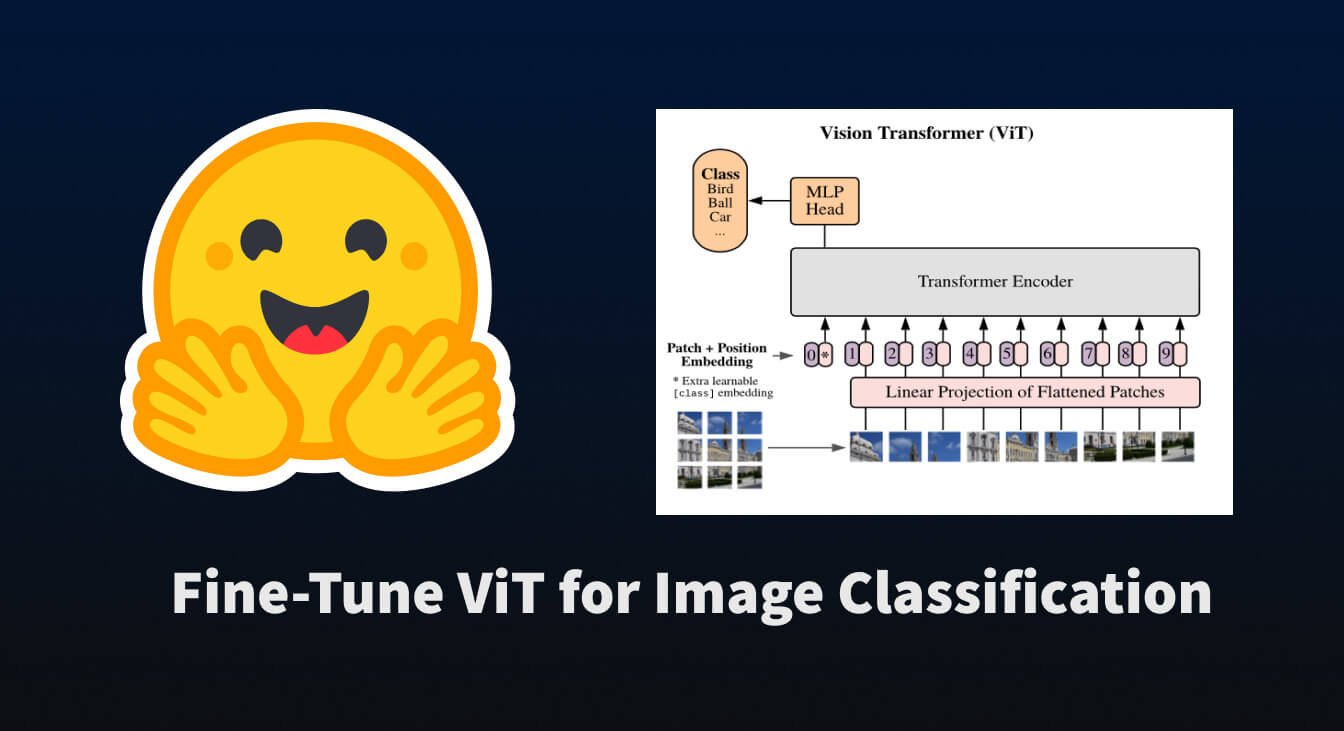

Just as transformers-based models have revolutionized NLP, we’re now seeing an explosion of papers applying them to all sorts of other domains. One of the most revolutionary of these was the Vision Transformer (ViT), which was introduced in June 2021 by a team of researchers at Google Brain.
This paper explored how you can tokenize images, just as you would tokenize sentences, so that they can be passed to transformer models for training. It’s quite a simple concept, really…
- Split an image into a grid of sub-image patches
- Embed each patch with a linear projection
- Each embedded patch becomes a token, and the resulting sequence of embedded patches is the sequence you pass to the model.
It turns out that once you’ve done the above, you can pre-train and fine-tune transformers just as you’re used to with NLP tasks. Pretty sweet 😎.
In this blog post, we’ll walk through how to leverage 🤗 datasets to download and process image classification datasets, and then use them to fine-tune a pre-trained ViT with 🤗 transformers.
To get started, let’s first install both those packages.
pip install datasets transformers
Load a dataset
Let’s start by loading a small image classification dataset and taking a look at its structure.
We’ll use the beans dataset, which is a collection of pictures of healthy and unhealthy bean leaves. 🍃
from datasets import load_dataset

ds = load_dataset('beans')
ds
Let’s take a look at the 400th example from the 'train' split from the beans dataset. You’ll notice each example from the dataset has 3 features:
image: A PIL Imageimage_file_path: Thestrpath to the image file that was loaded asimagelabels: Adatasets.ClassLabelfeature, which is an integer representation of the label. (Later you’ll see how to get the string class names, don’t worry!)
ex = ds['train'][400]
ex
{
  'image': ,
  'image_file_path': '/root/.cache/.../bean_rust_train.4.jpg',
  'labels': 1
}
Let’s take a look at the image 👀
image = ex['image']
image
That’s definitely a leaf! But what kind? 😅
Since the 'labels' feature of this dataset is a datasets.features.ClassLabel, we can use it to look up the corresponding name for this example’s label ID.
First, let’s access the feature definition for the 'labels'.
labels = ds['train'].features['labels']
labels
ClassLabel(num_classes=3, names=['angular_leaf_spot', 'bean_rust', 'healthy'], names_file=None, id=None)
Now, let’s print out the class label for our example. You can do that by using the int2str function of ClassLabel, which, as the name implies, allows to pass the integer representation of the class to look up the string label.
labels.int2str(ex['labels'])
'bean_rust'
Turns out the leaf shown above is infected with Bean Rust, a serious disease in bean plants. 😢
Let’s write a function that’ll display a grid of examples from each class to get a better idea of what you’re working with.
import random
from PIL import ImageDraw, ImageFont, Image

def show_examples(ds, seed: int = 1234, examples_per_class: int = 3, size=(350, 350)):

    w, h = size
    labels = ds['train'].features['labels'].names
    grid = Image.new('RGB', size=(examples_per_class * w, len(labels) * h))
    draw = ImageDraw.Draw(grid)
    font = ImageFont.truetype("/usr/share/fonts/truetype/liberation/LiberationMono-Bold.ttf", 24)

    for label_id, label in enumerate(labels):


        ds_slice = ds['train'].filter(lambda ex: ex['labels'] == label_id).shuffle(seed).select(range(examples_per_class))


        for i, example in enumerate(ds_slice):
            image = example['image']
            idx = examples_per_class * label_id + i
            box = (idx % examples_per_class * w, idx // examples_per_class * h)
            grid.paste(image.resize(size), box=box)
            draw.text(box, label, (255, 255, 255), font=font)

    return grid

show_examples(ds, seed=random.randint(0, 1337), examples_per_class=3)
From what I’m seeing,
- Angular Leaf Spot: Has irregular brown patches
- Bean Rust: Has circular brown spots surrounded with a white-ish yellow ring
- Healthy: …looks healthy. 🤷♂️
Loading ViT Image Processor
Now we know what our images look like and better understand the problem we’re trying to solve. Let’s see how we can prepare these images for our model!
When ViT models are trained, specific transformations are applied to images fed into them. Use the wrong transformations on your image, and the model won’t understand what it’s seeing! 🖼 ➡️ 🔢
To make sure we apply the correct transformations, we will use a ViTImageProcessor initialized with a configuration that was saved along with the pretrained model we plan to use. In our case, we’ll be using the google/vit-base-patch16-224-in21k model, so let’s load its image processor from the Hugging Face Hub.
from transformers import ViTImageProcessor

model_name_or_path = 'google/vit-base-patch16-224-in21k'
processor = ViTImageProcessor.from_pretrained(model_name_or_path)
You can see the image processor configuration by printing it.
ViTImageProcessor {
  "do_normalize": true,
  "do_resize": true,
  "image_mean": [
    0.5,
    0.5,
    0.5
  ],
  "image_std": [
    0.5,
    0.5,
    0.5
  ],
  "resample": 2,
  "size": 224
}
To process an image, simply pass it to the image processor’s call function. This will return a dict containing pixel values, which is the numeric representation to be passed to the model.
You get a NumPy array by default, but if you add the return_tensors="pt" argument, you’ll get back torch tensors instead.
processor(image, return_tensors='pt')
Should give you something like…
{
  'pixel_values': tensor([[[[ 0.2706,  0.3255,  0.3804,  ...]]]])
}
…where the shape of the tensor is (1, 3, 224, 224).
Processing the Dataset
Now that you know how to read images and transform them into inputs, let’s write a function that will put those two things together to process a single example from the dataset.
def process_example(example):
    inputs = processor(example['image'], return_tensors='pt')
    inputs['labels'] = example['labels']
    return inputs
process_example(ds['train'][0])
{
  'pixel_values': tensor([[[[-0.6157, -0.6000, -0.6078,  ..., ]]]]),
  'labels': 0
}
While you could call ds.map and apply this to every example at once, this can be very slow, especially if you use a larger dataset. Instead, you can apply a transform to the dataset. Transforms are only applied to examples as you index them.
First, though, you’ll need to update the last function to accept a batch of data, as that’s what ds.with_transform expects.
ds = load_dataset('beans')

def transform(example_batch):

    inputs = processor([x for x in example_batch['image']], return_tensors='pt')


    inputs['labels'] = example_batch['labels']
    return inputs
You can directly apply this to the dataset using ds.with_transform(transform).
prepared_ds = ds.with_transform(transform)
Now, whenever you get an example from the dataset, the transform will be
applied in real time (on both samples and slices, as shown below)
prepared_ds['train'][0:2]
This time, the resulting pixel_values tensor will have shape (2, 3, 224, 224).
{
  'pixel_values': tensor([[[[-0.6157, -0.6000, -0.6078,  ..., ]]]]),
  'labels': [0, 0]
}
Training and Evaluation
The data is processed and you are ready to start setting up the training pipeline. This blog post uses 🤗’s Trainer, but that’ll require us to do a few things first:
-
Define a collate function.
-
Define an evaluation metric. During training, the model should be evaluated on its prediction accuracy. You should define a
compute_metricsfunction accordingly. -
Load a pretrained checkpoint. You need to load a pretrained checkpoint and configure it correctly for training.
-
Define the training configuration.
After fine-tuning the model, you will correctly evaluate it on the evaluation data and verify that it has indeed learned to correctly classify the images.
Define our data collator
Batches are coming in as lists of dicts, so you can just unpack + stack those into batch tensors.
Since the collate_fn will return a batch dict, you can **unpack the inputs to the model later. ✨
import torch

def collate_fn(batch):
    return {
        'pixel_values': torch.stack([x['pixel_values'] for x in batch]),
        'labels': torch.tensor([x['labels'] for x in batch])
    }
Define an evaluation metric
The accuracy metric from evaluate can easily be used to compare the predictions with the labels. Below, you can see how to use it within a compute_metrics function that will be used by the Trainer.
import numpy as np
from evaluate import load

metric = load("accuracy")
def compute_metrics(p):
    return metric.compute(predictions=np.argmax(p.predictions, axis=1), references=p.label_ids)
Let’s load the pretrained model. We’ll add num_labels on init so the model creates a classification head with the right number of units. We’ll also include the id2label and label2id mappings to have human-readable labels in the Hub widget (if you choose to push_to_hub).
from transformers import ViTForImageClassification

labels = ds['train'].features['labels'].names

model = ViTForImageClassification.from_pretrained(
    model_name_or_path,
    num_labels=len(labels),
    id2label={str(i): c for i, c in enumerate(labels)},
    label2id={c: str(i) for i, c in enumerate(labels)}
)
Almost ready to train! The last thing needed before that is to set up the training configuration by defining TrainingArguments.
Most of these are pretty self-explanatory, but one that is quite important here is remove_unused_columns=False. This one will drop any features not used by the model’s call function. By default it’s True because usually it’s ideal to drop unused feature columns, making it easier to unpack inputs into the model’s call function. But, in our case, we need the unused features (‘image’ in particular) in order to create ‘pixel_values’.
What I’m trying to say is that you’ll have a bad time if you forget to set remove_unused_columns=False.
from transformers import TrainingArguments

training_args = TrainingArguments(
  output_dir="./vit-base-beans",
  per_device_train_batch_size=16,
  evaluation_strategy="steps",
  num_train_epochs=4,
  fp16=True,
  save_steps=100,
  eval_steps=100,
  logging_steps=10,
  learning_rate=2e-4,
  save_total_limit=2,
  remove_unused_columns=False,
  push_to_hub=False,
  report_to='tensorboard',
  load_best_model_at_end=True,
)
Now, all instances can be passed to Trainer and we are ready to start training!
from transformers import Trainer

trainer = Trainer(
    model=model,
    args=training_args,
    data_collator=collate_fn,
    compute_metrics=compute_metrics,
    train_dataset=prepared_ds["train"],
    eval_dataset=prepared_ds["validation"],
    tokenizer=processor,
)
Train 🚀
train_results = trainer.train()
trainer.save_model()
trainer.log_metrics("train", train_results.metrics)
trainer.save_metrics("train", train_results.metrics)
trainer.save_state()
Evaluate 📊
metrics = trainer.evaluate(prepared_ds['validation'])
trainer.log_metrics("eval", metrics)
trainer.save_metrics("eval", metrics)
Here were my evaluation results – Cool beans! Sorry, had to say it.
***** eval metrics *****
  epoch                   =        4.0
  eval_accuracy           =      0.985
  eval_loss               =     0.0637
  eval_runtime            = 0:00:02.13
  eval_samples_per_second =     62.356
  eval_steps_per_second   =       7.97
Finally, if you want, you can push your model up to the hub. Here, we’ll push it up if you specified push_to_hub=True in the training configuration. Note that in order to push to hub, you’ll have to have git-lfs installed and be logged into your Hugging Face account (which can be done via huggingface-cli login).
kwargs = {
    "finetuned_from": model.config._name_or_path,
    "tasks": "image-classification",
    "dataset": 'beans',
    "tags": ['image-classification'],
}

if training_args.push_to_hub:
    trainer.push_to_hub('🍻 cheers', **kwargs)
else:
    trainer.create_model_card(**kwargs)
The resulting model has been shared to nateraw/vit-base-beans. I’m assuming you don’t have pictures of bean leaves laying around, so I added some examples for you to give it a try! 🚀
