


Building a router into your agent sounds like an easy win. Send simple requests to cheaper models, reserve expensive ones for harder tasks, or route by specialty — Claude for code, Gemini for multimodal, and so on. A classifier or heuristic makes the call, costs go down, performance stays up. Done.
Except it’s not. Most routing systems assume that model selection is a classification problem. In our experience building routing into agentic systems, what looks like a model-selection problem quickly becomes a systems optimization problem. Three dimensions made this surprisingly hard for us.
1. Cost Is More Than Model Pricing
We expected GPT-4.1 to be cheaper than Claude Sonnet 4.6. It wasn’t.
Across 417 tasks on the AppWorld Test Challenge using the same CodeAct agent, Sonnet cost $79 total ($0.19/task) while GPT-4.1 cost $155 ($0.37/task) — nearly double. On paper, this makes no sense. GPT-4.1’s token pricing is lower on both input and output, and Sonnet takes roughly three times as many reasoning steps to finish the same tasks. By sticker price alone, GPT-4.1 should win easily.
The explanation? Caching — something most routing discussions ignore entirely.
Agent workloads tend to reuse large chunks of context across steps. When cache hit rates are high, effective input costs drop dramatically. Sonnet’s lower cache-read pricing meant it benefited disproportionately from this pattern, enough to overcome both its higher base pricing and its longer trajectories.
The takeaway: actual cost depends on the interaction between the model, the workload, and the serving infrastructure. A router that only looks at pricing sheets is optimizing against the wrong numbers.
2. Complexity Is More Than Task Difficulty
A common routing strategy is to estimate how hard a task is and send harder tasks to stronger models. Intuitive, but it breaks down in two ways.
First, difficulty is often invisible at routing time. A request like “summarize this contract” looks simple, but might trigger retrieval, compliance checks, tool use, and multiple rounds of refinement before it’s done. Meanwhile, a highly technical prompt might be handled efficiently by a smaller specialized model. You often don’t know how hard a task actually is until execution is underway.
Second, even if you could perfectly estimate difficulty, it’s only one signal among many. In production, routers need to balance cost, latency, model specialization, and reliability simultaneously. Enterprise deployments pile on more: compliance requirements, data residency rules, privacy constraints, approved model lists. A task that would ideally go to one model might need to go elsewhere because of governance — and the router has to handle that gracefully.
Routers aren’t solving one problem. They’re constantly juggling cost, quality, latency, compliance, and reliability all at once.
3. Latency Is More Than Model Speed
It’s tempting to think about latency purely in terms of model size — bigger models are slower, smaller ones are faster. But what the user actually experiences depends on much more than that.
Routing itself adds overhead. Infrastructure factors — which hardware a model is running on, whether the cache is warm, how busy the endpoint is — often dominate end-to-end response times. A theoretically faster model can still produce a slower experience if the serving conditions aren’t right.
Then there’s routing granularity. Routing once per task adds minimal overhead. But routing at every step — which gives you more flexibility to adapt mid-execution — means every additional decision point introduces latency and operational complexity.
A router that ignores the serving system is optimizing against the wrong reality.
So How Did We Handle This?
These lessons shaped how we built our router. The key shift: we stopped treating routing as a classification problem and started treating it as an optimization problem. Rather than asking “which model is best for this task?”, our algorithm optimizes across cost, quality, and latency simultaneously — while staying lightweight enough to avoid becoming a bottleneck itself.
The figure below shows the result on the AppWorld Test Challenge with a CodeAct agent. Each blue square is a different configuration of our router, tracing out a cost-accuracy frontier. The important thing isn’t any single point — it’s that the router gives you a range of operating points to choose from depending on whether you want to prioritize cost, latency, or accuracy. Configuration 1 (latency-optimized) lands at 84% accuracy for $93 and 83s — a 21% cost reduction and 9% latency reduction compared to running Opus alone, with only a 4% accuracy drop. Configuration 2 pushes cost even lower.
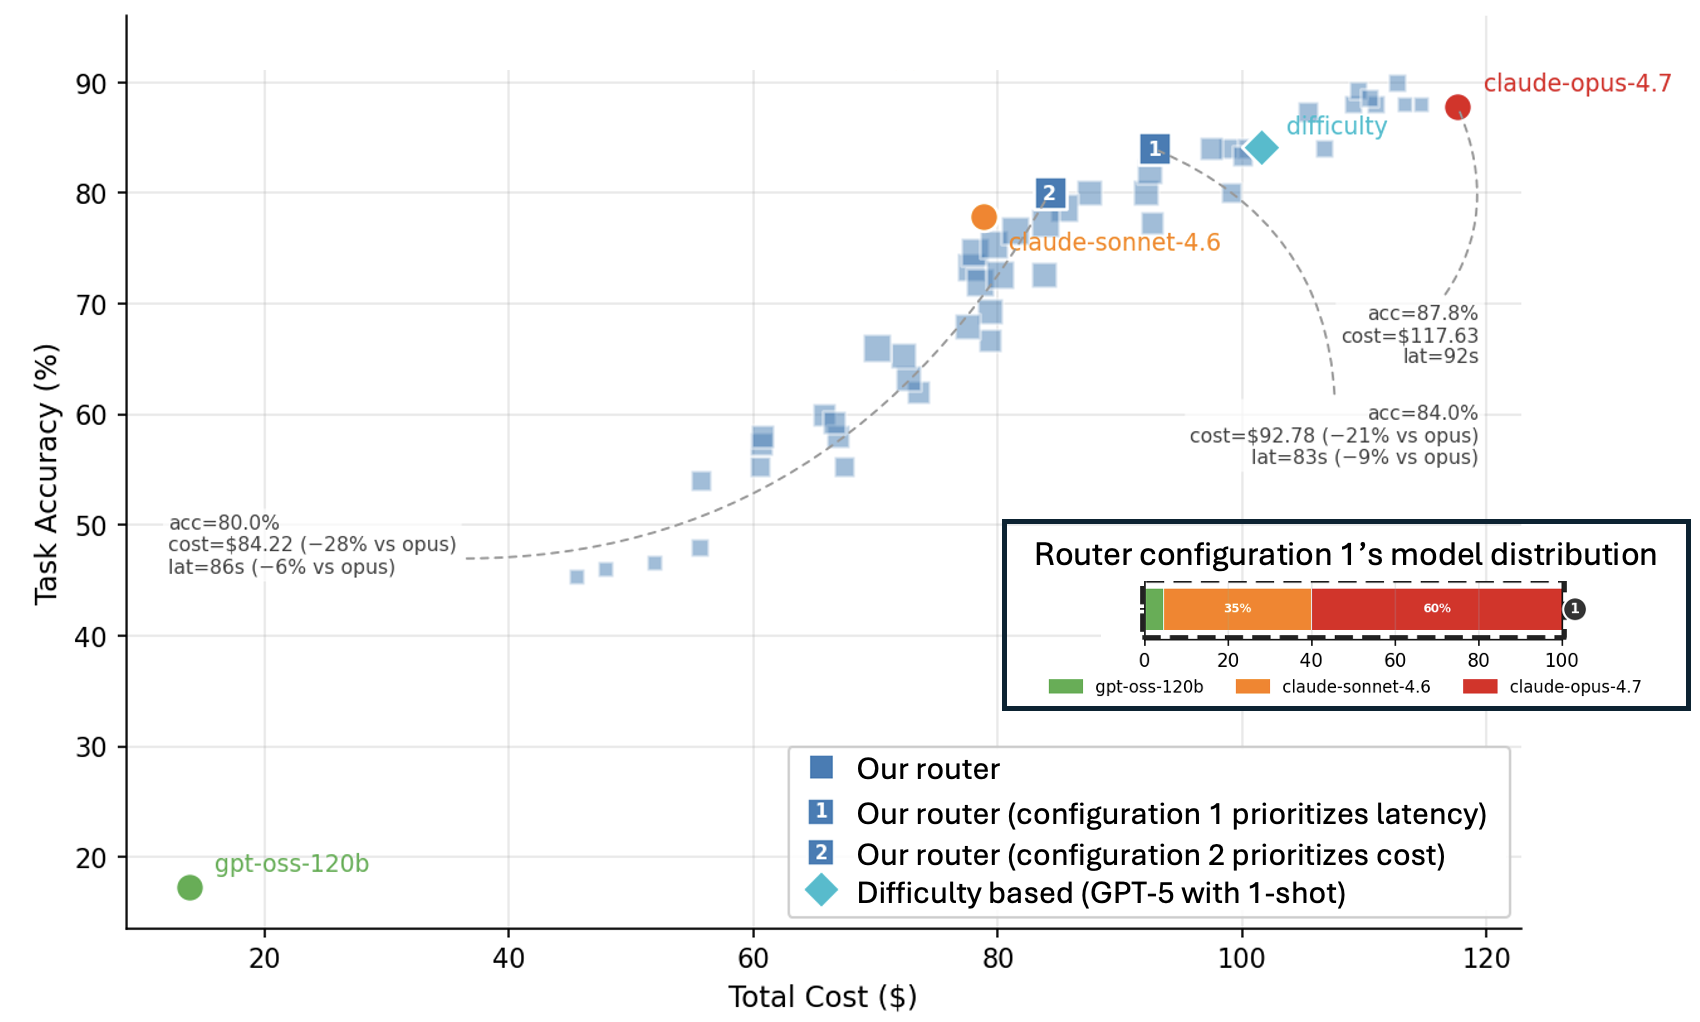
Notice that a standard difficulty-based router (the teal diamond) lands in a similar accuracy range but at higher cost — it doesn’t explore the full tradeoff space the way an optimization-based approach can. And because the optimization itself is lightweight (roughly 6 ms and 2 kB of memory per task), the router doesn’t become the bottleneck we warned about earlier.
The Bigger Picture
The lesson we took away from this work is that routing isn’t really about choosing models. It’s about optimizing systems. Models are one variable — an important one, but just one among caching behavior, infrastructure state, compliance constraints, and workload patterns.
When routing works well, it’s rarely because it found the “best” model for a given task. It’s because it found the best operating point for the entire system. That’s a harder problem than classification, but it’s the one worth solving.
We’ll be sharing more about the technical details behind our approach in a follow-up post. In the meantime, if you’re building routing into your own agentic systems, we’d love to hear what tradeoffs you’re running into.
Acknowledgement
This post was influenced by numerous conversations with colleagues, whose thoughtful questions, feedback, and insights helped refine our thinking.
